A 4B agent that learns from its failed patches
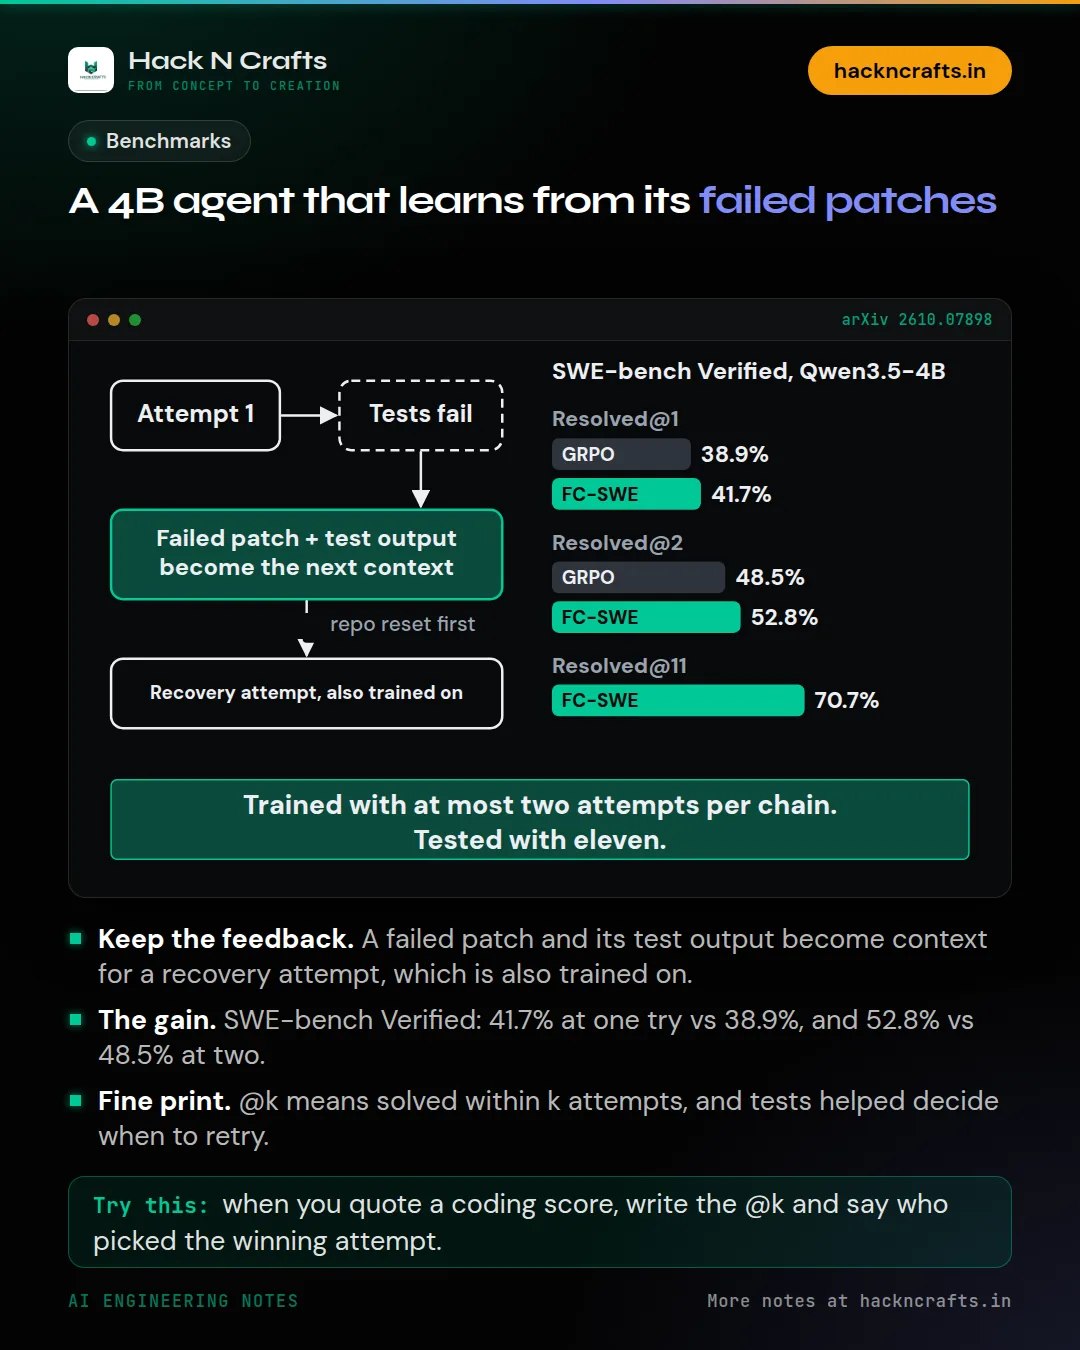
A 4B-parameter model reached 41.7% on SWE-bench Verified by learning from its own failed patches. The same setup without that idea scored 38.9%.
The paper is FC-SWE (NVIDIA and Tsinghua, on arXiv in early October). The idea is simple. Most RL training for coding agents samples several attempts per issue, runs the tests and compares scores. When a patch fails, the verifier's feedback gets thrown away. FC-SWE keeps it: after a failure it resets the repository, hands the failed patch and the test feedback to the agent as context, and trains on the recovery attempt too.
The results, on all 500 SWE-bench Verified tasks with Qwen3.5-4B and SWE-agent, under a verifier-assisted protocol:
- 1Resolved@1: 41.7% versus 38.9% for the GRPO baseline.
- 2Resolved@2: 52.8% versus 48.5%.
- 3With an eleven-attempt test-time budget: 70.7% Resolved@11, even though training used at most two attempts per chain.
Read the fine print. Resolved@k means solved within k attempts, and the verifier-assisted protocol means tests helped decide when to retry. It isn't the same number as a single-shot leaderboard score.
Which would you rather have in production: a higher first-try score, or an agent that recovers well on the second?
Sources
New notes go out on LinkedIn first. Building something with AI? We can help.