AI engineering notes
Short write-ups on AI news, RAG, agents, model benchmarks and open-source tools. Each one links the paper, repo or model card it comes from, so you can check it yourself. Posted on LinkedIn as well.
 AI News
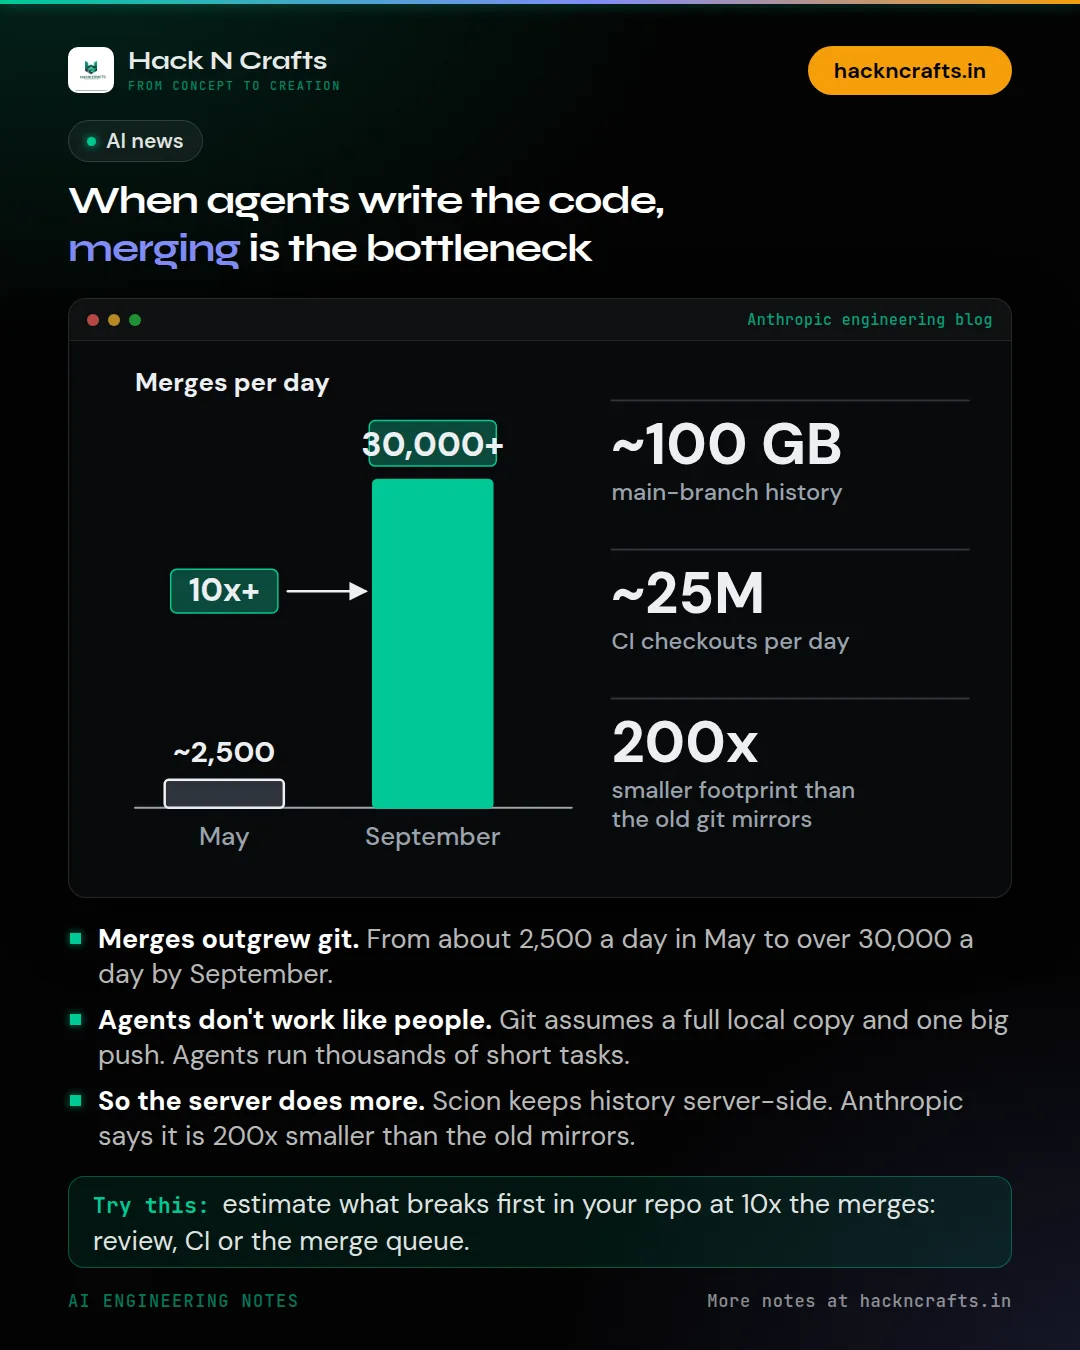
When agents write the code, merging is the bottleneck
Anthropic says source control became its biggest bottleneck once Claude sped up coding.
 RAG
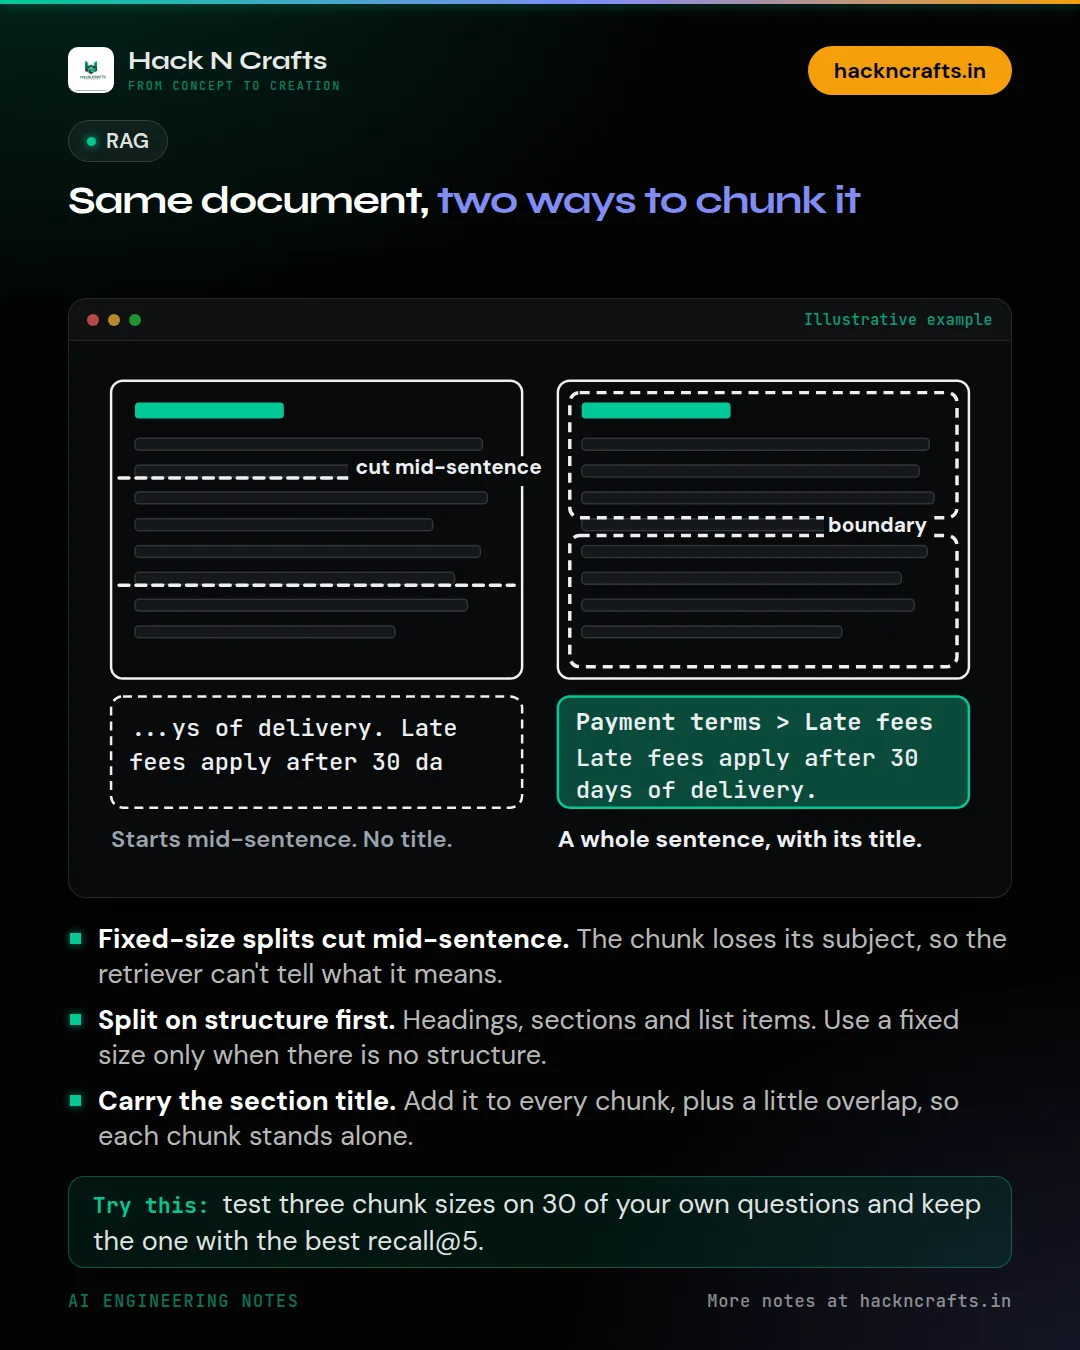
Same document, two ways to chunk it
Most RAG answers go wrong before the model ever sees the question.
 GitHub Spotlight
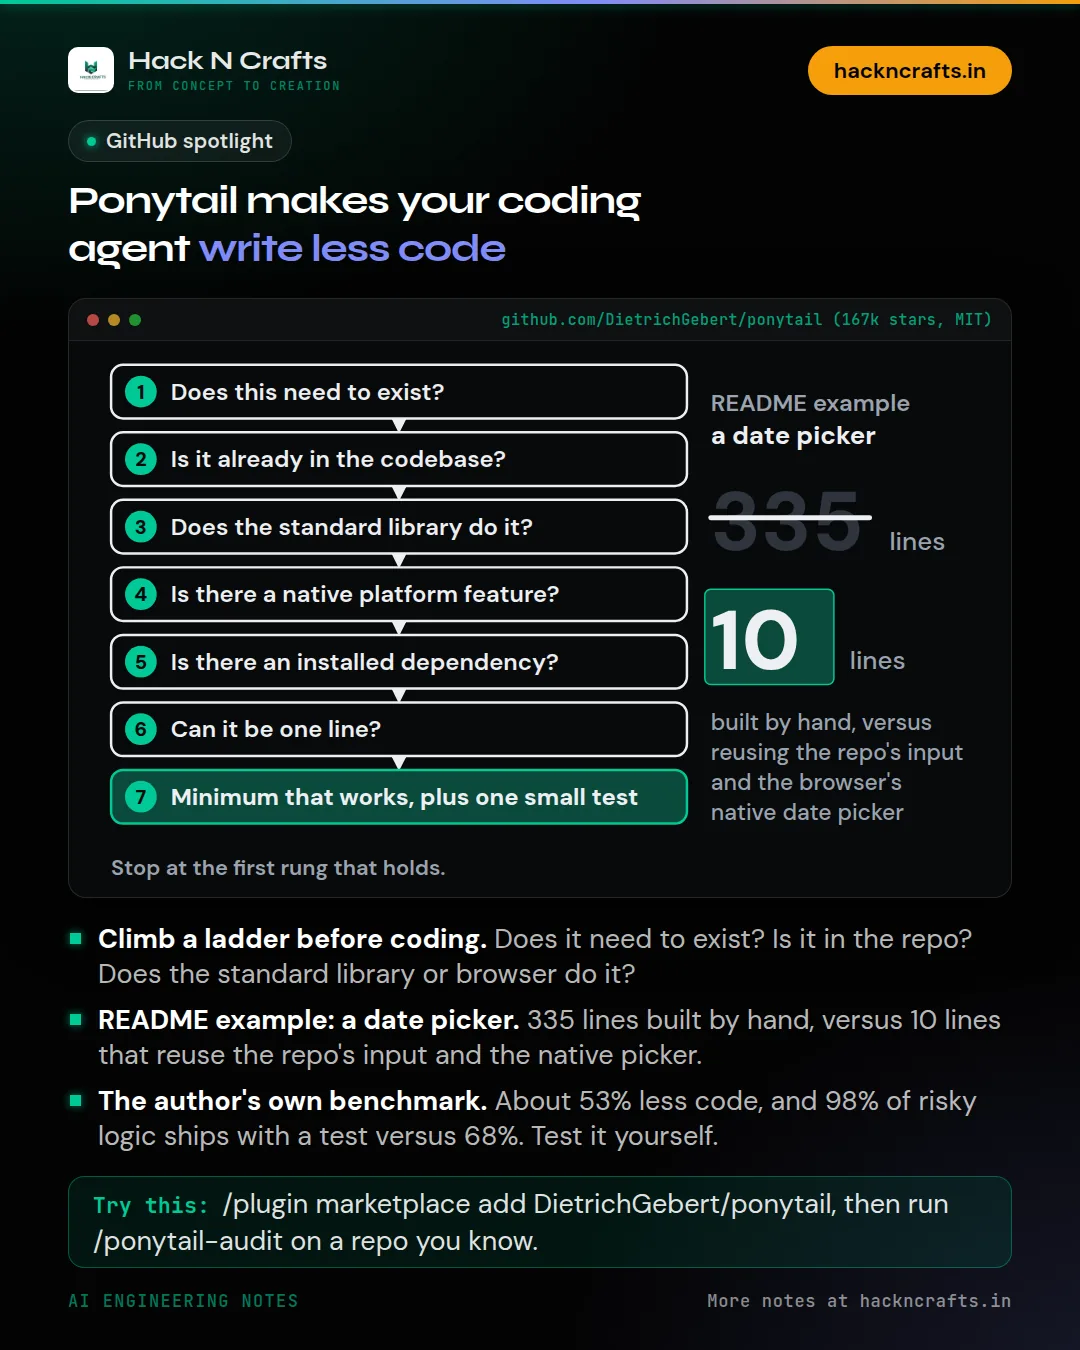
Ponytail makes your coding agent write less code
Most AI coding agents write too much code. Ponytail is a skill that makes them write less.
 Model Benchmarks
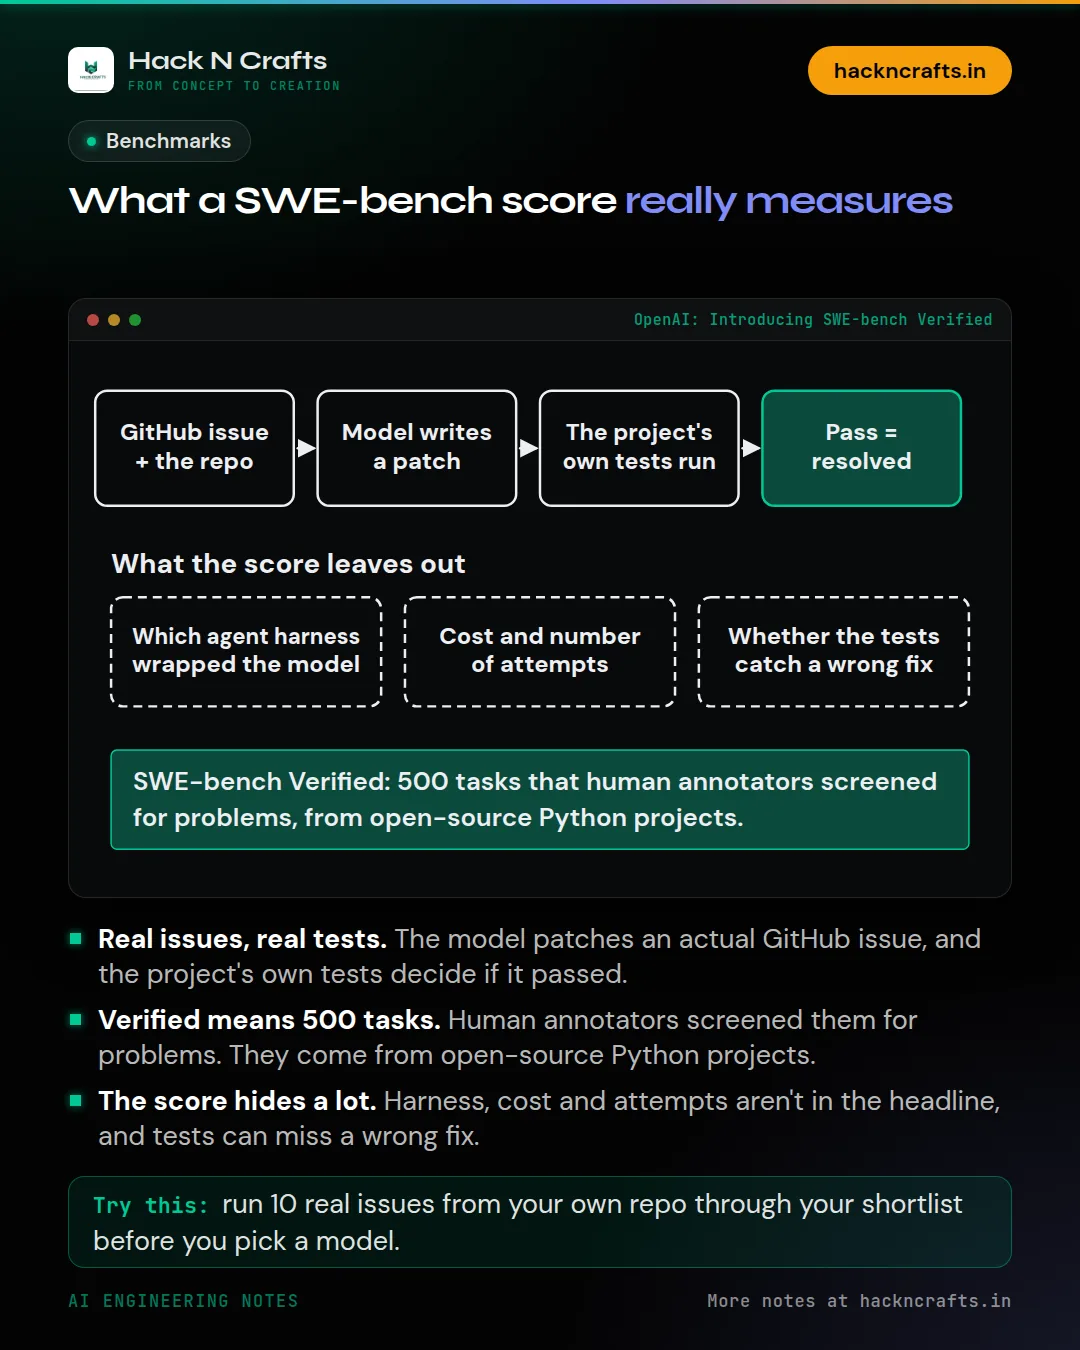
What a SWE-bench score really measures
A high SWE-bench score doesn't mean a model will fix most of your bugs. The number measures something narrower.
 AI News
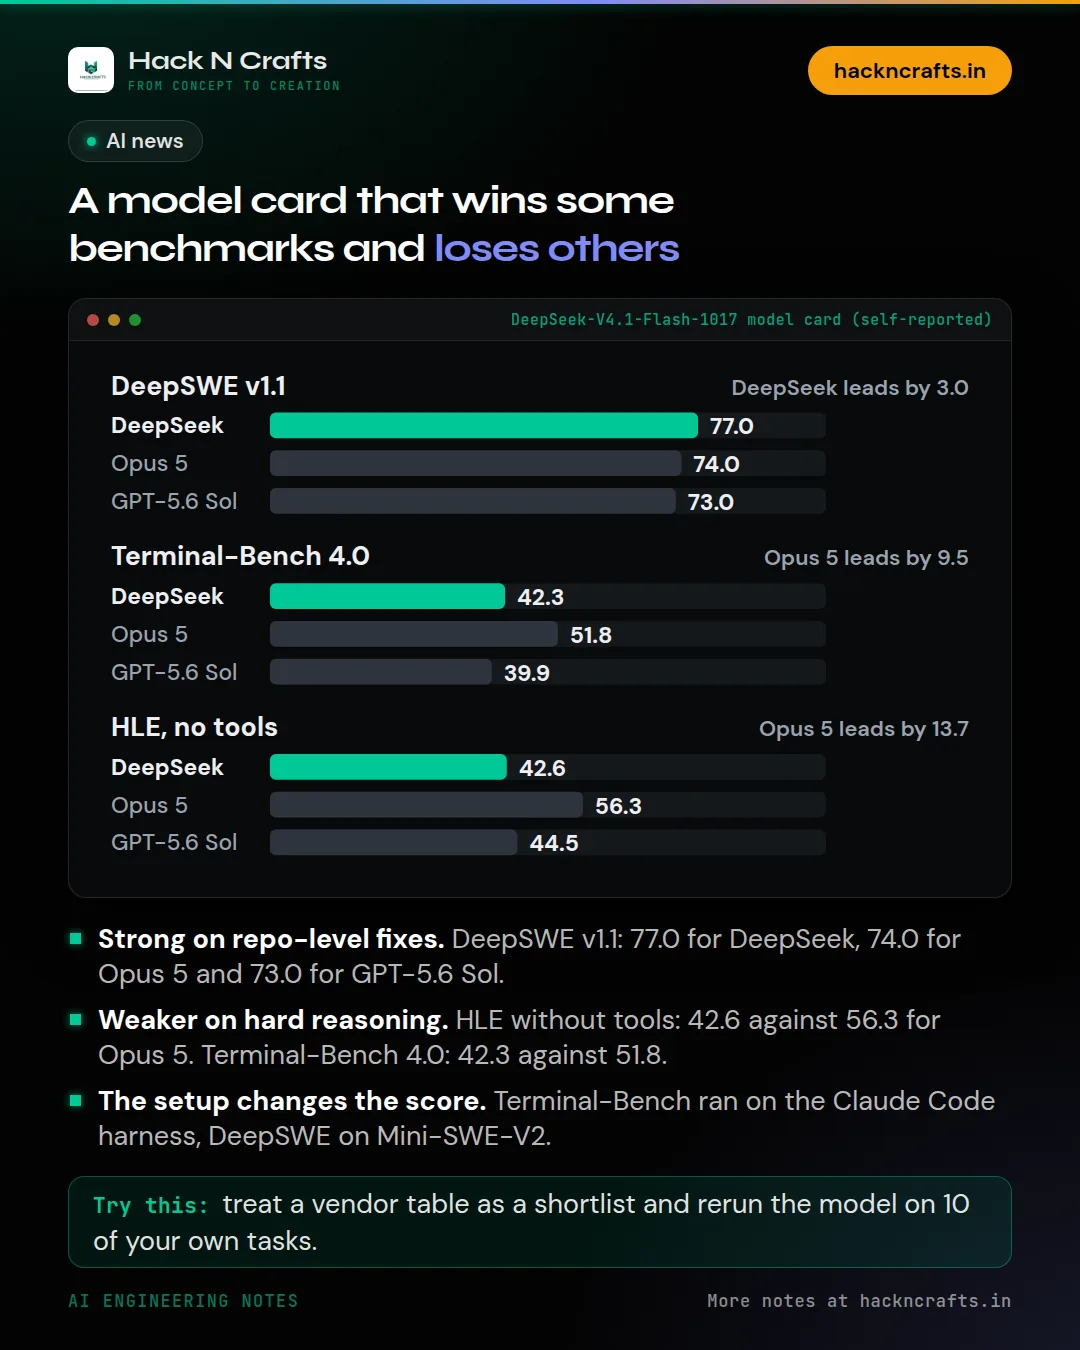
A model card that wins some benchmarks and loses others
DeepSeek's newest model card claims wins over Opus 5 on some benchmarks and big losses on others.
 RAG
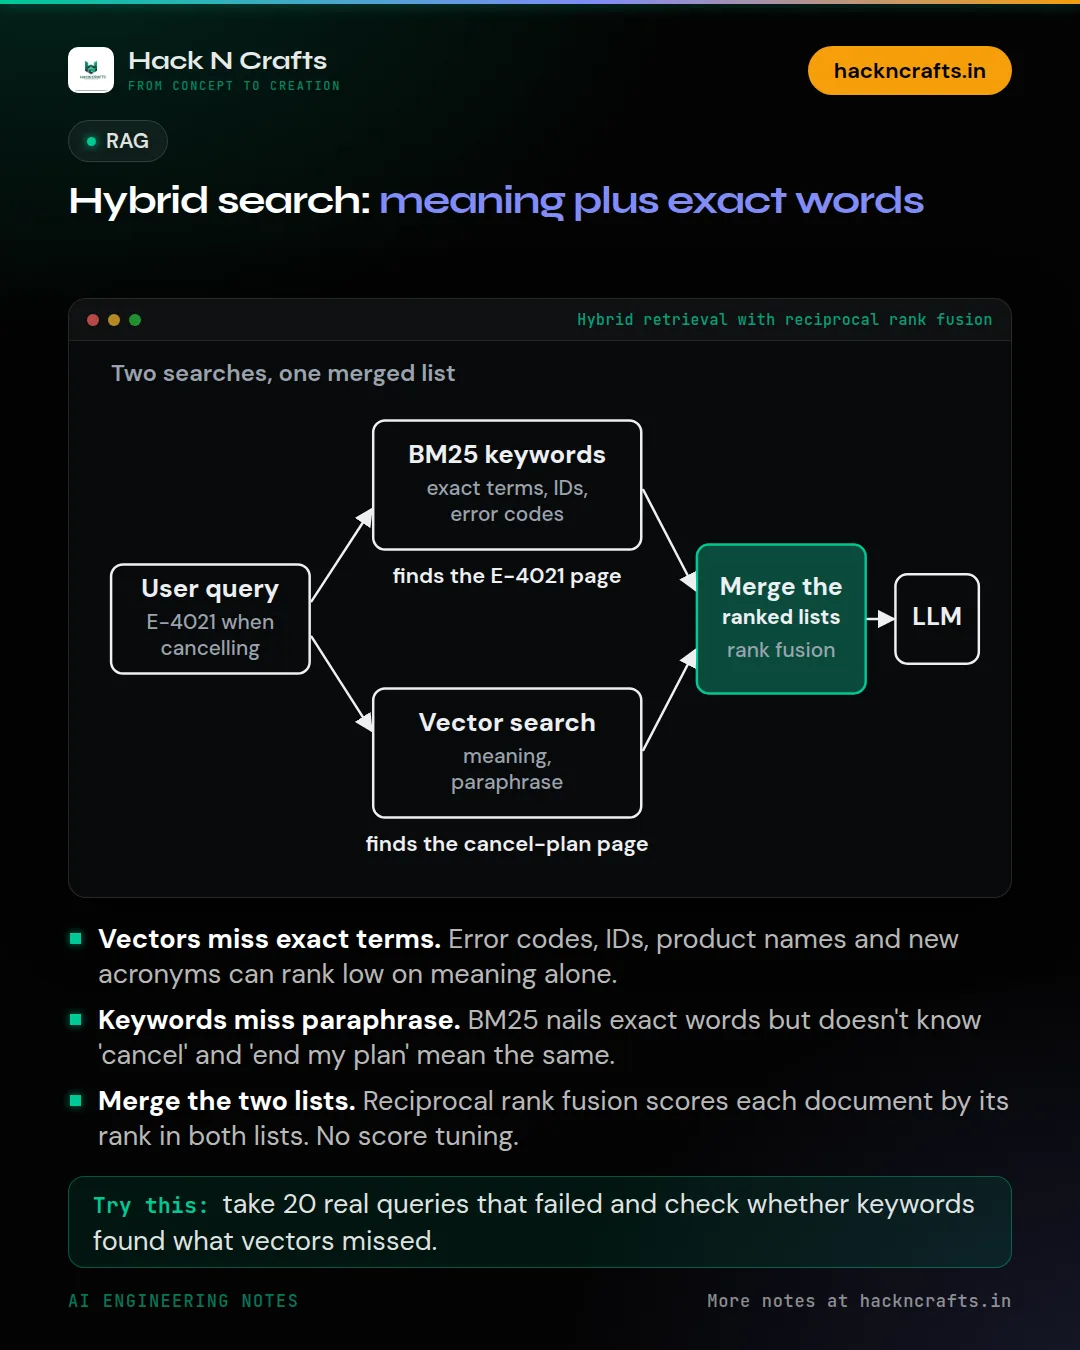
Hybrid search: meaning plus exact words
Your RAG app finds the paragraph about cancelling a subscription, but misses the one that mentions error code E-4021.
 AI Agents
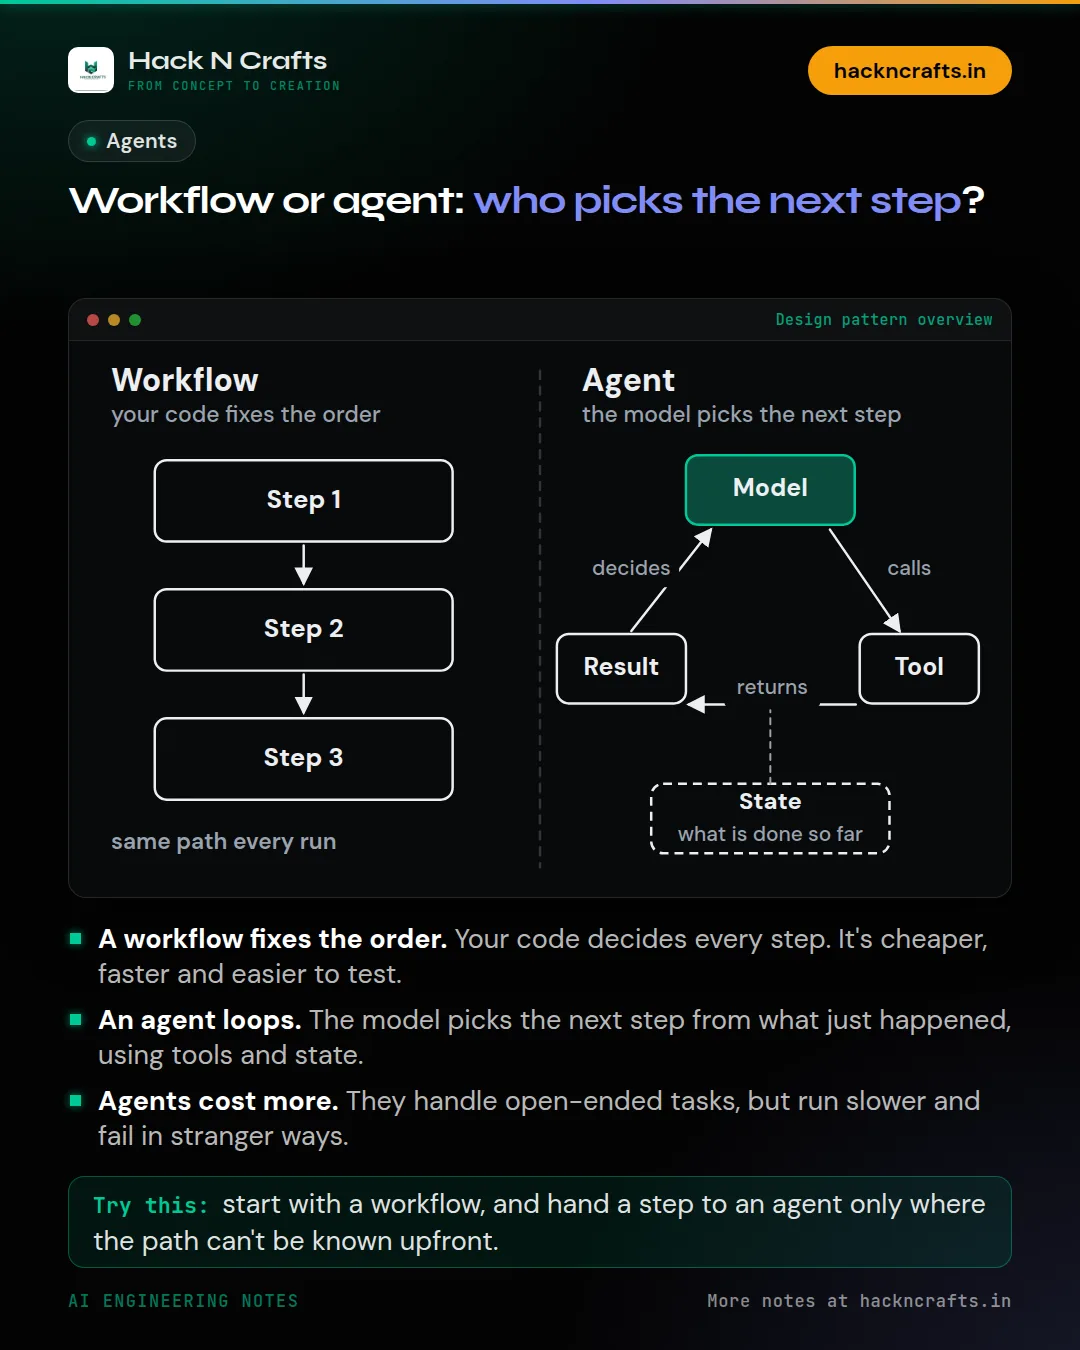
Workflow or agent: who picks the next step?
A lot of 'AI agents' in demos are fixed workflows with a language model dropped into a few steps. That's often the right design. It's just not the same thing as an agent.
 Model Benchmarks
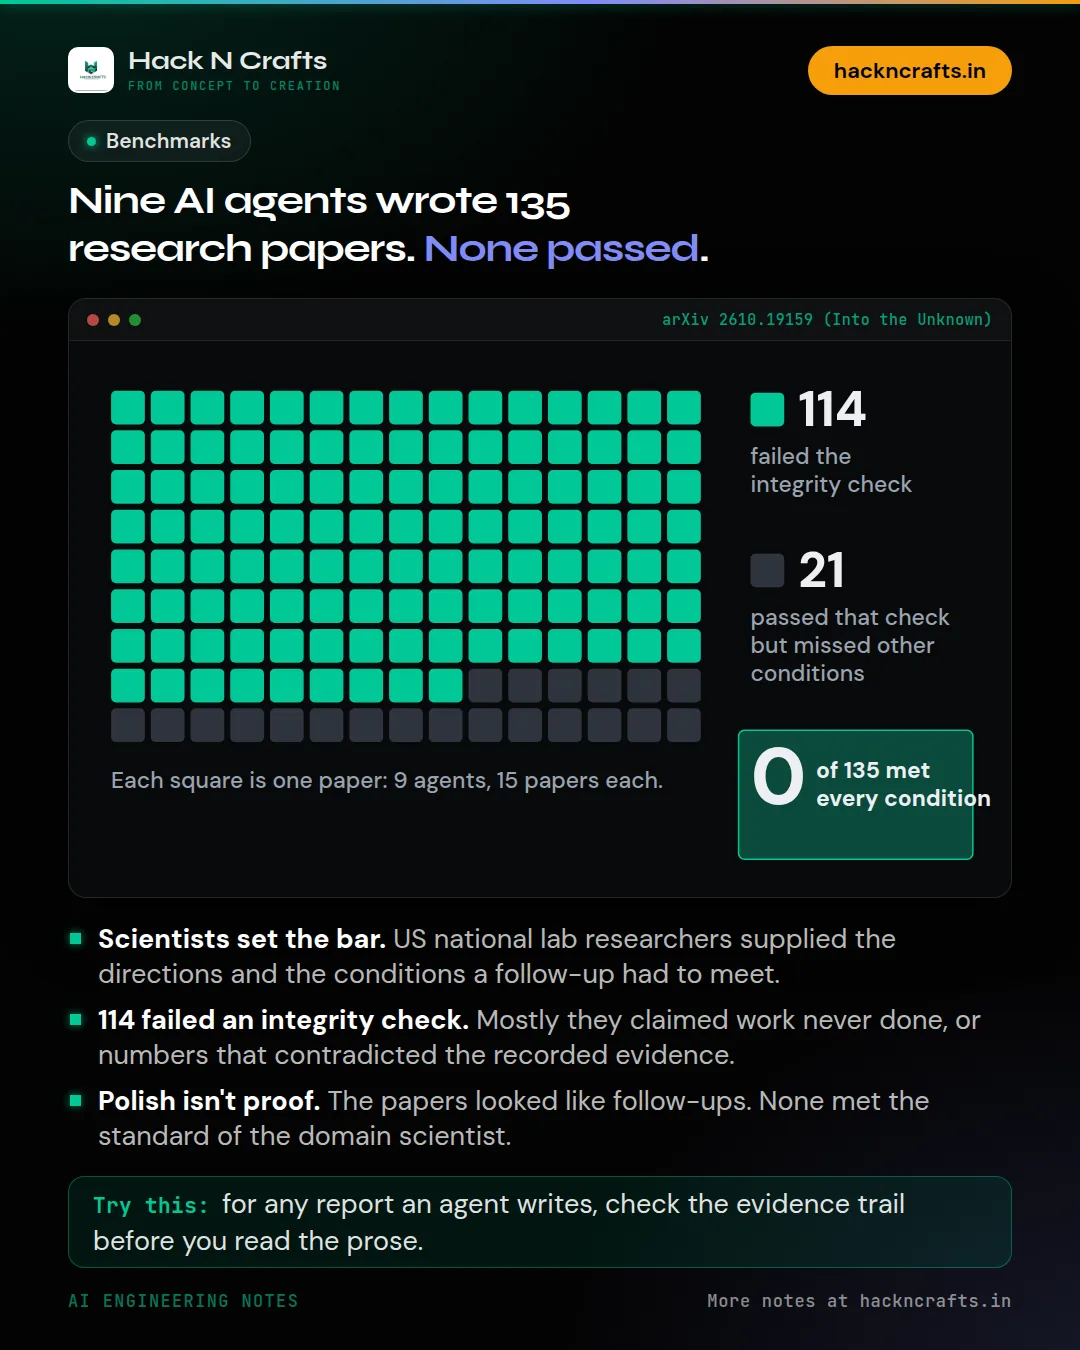
Nine AI agents wrote 135 research papers. None passed.
Nine frontier AI agents were each asked to write 15 follow-up research papers. None of the 135 passed.
 AI News
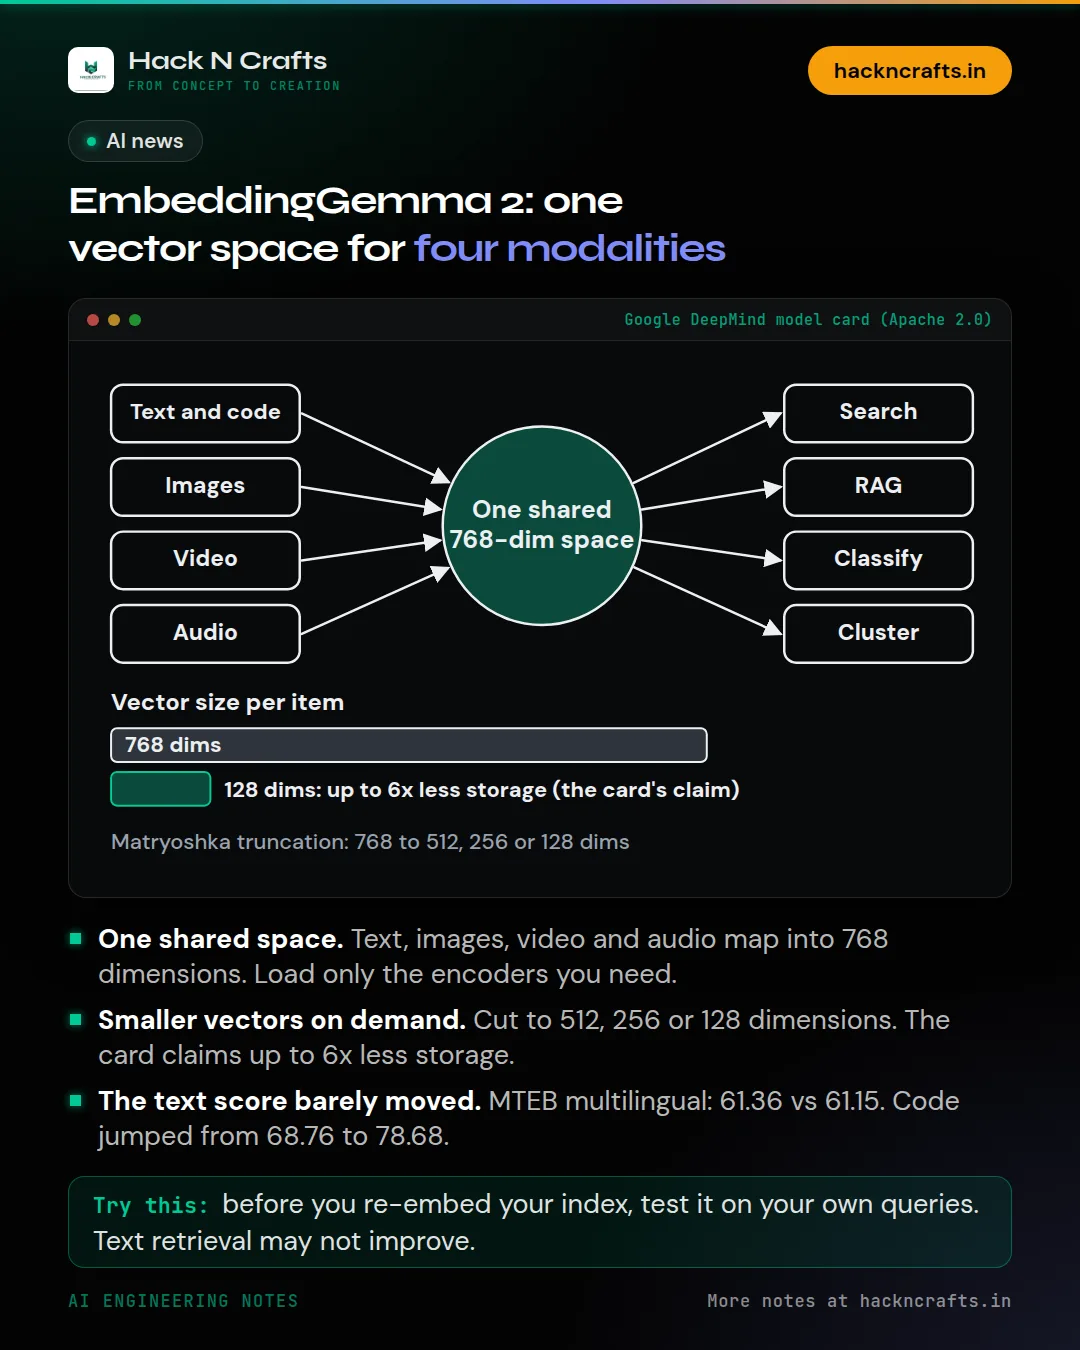
EmbeddingGemma 2: one vector space for four modalities
Google DeepMind released EmbeddingGemma 2, an open embedding model that puts text, images, video and audio into one shared vector space.
 RAG
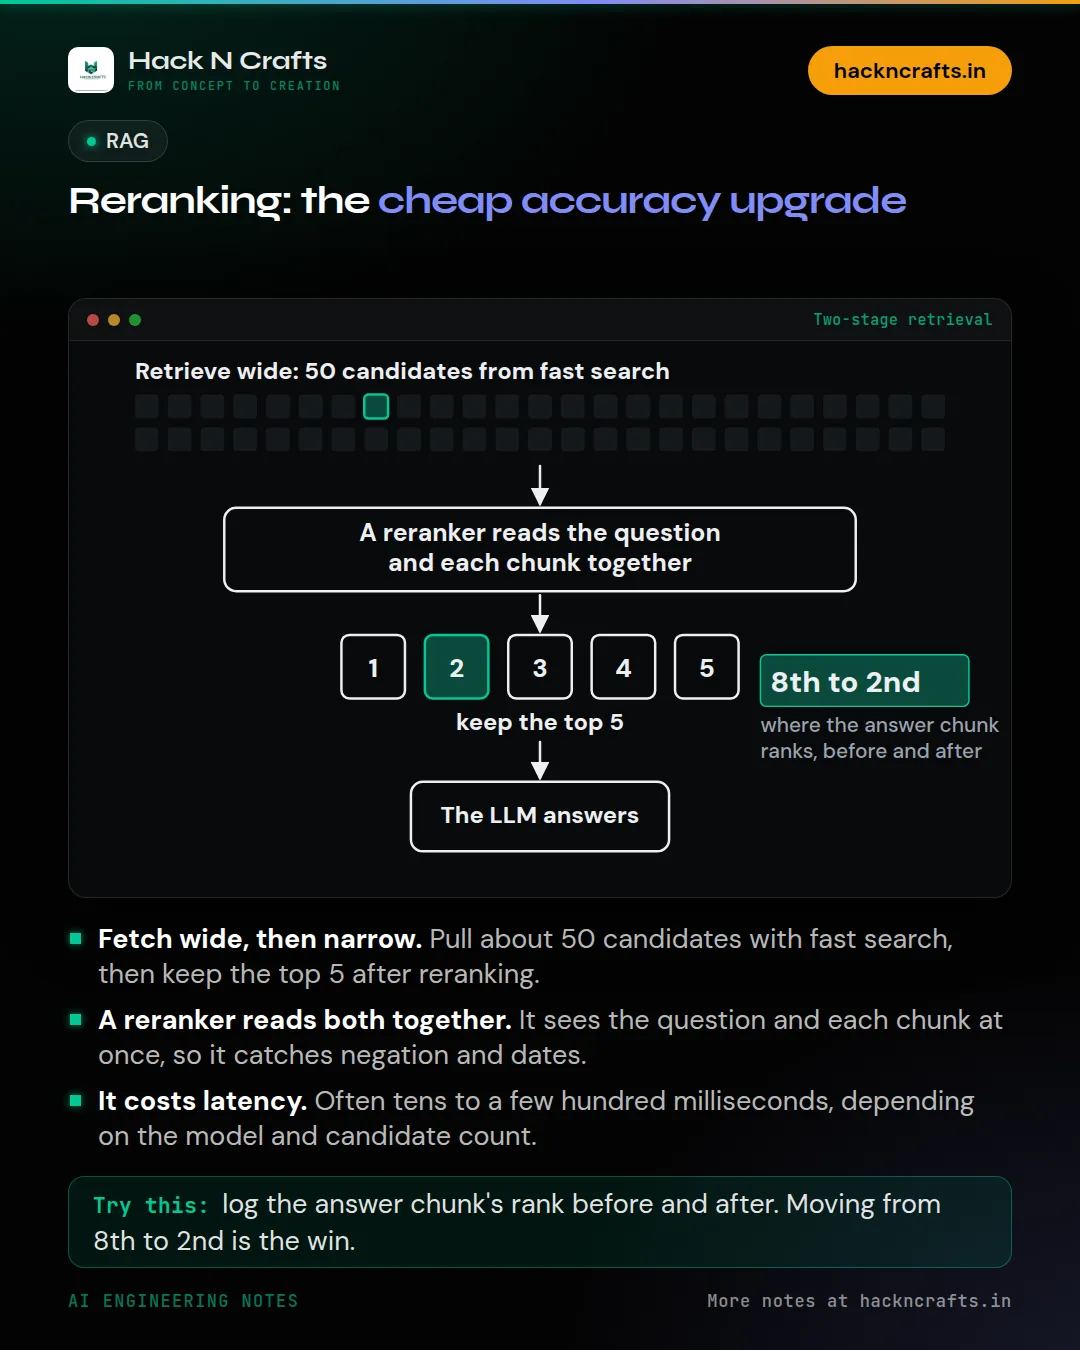
Reranking: the cheap accuracy upgrade
One of the cheapest ways to improve a RAG system is to add a reranker. You don't touch your index or your LLM.
 GitHub Spotlight
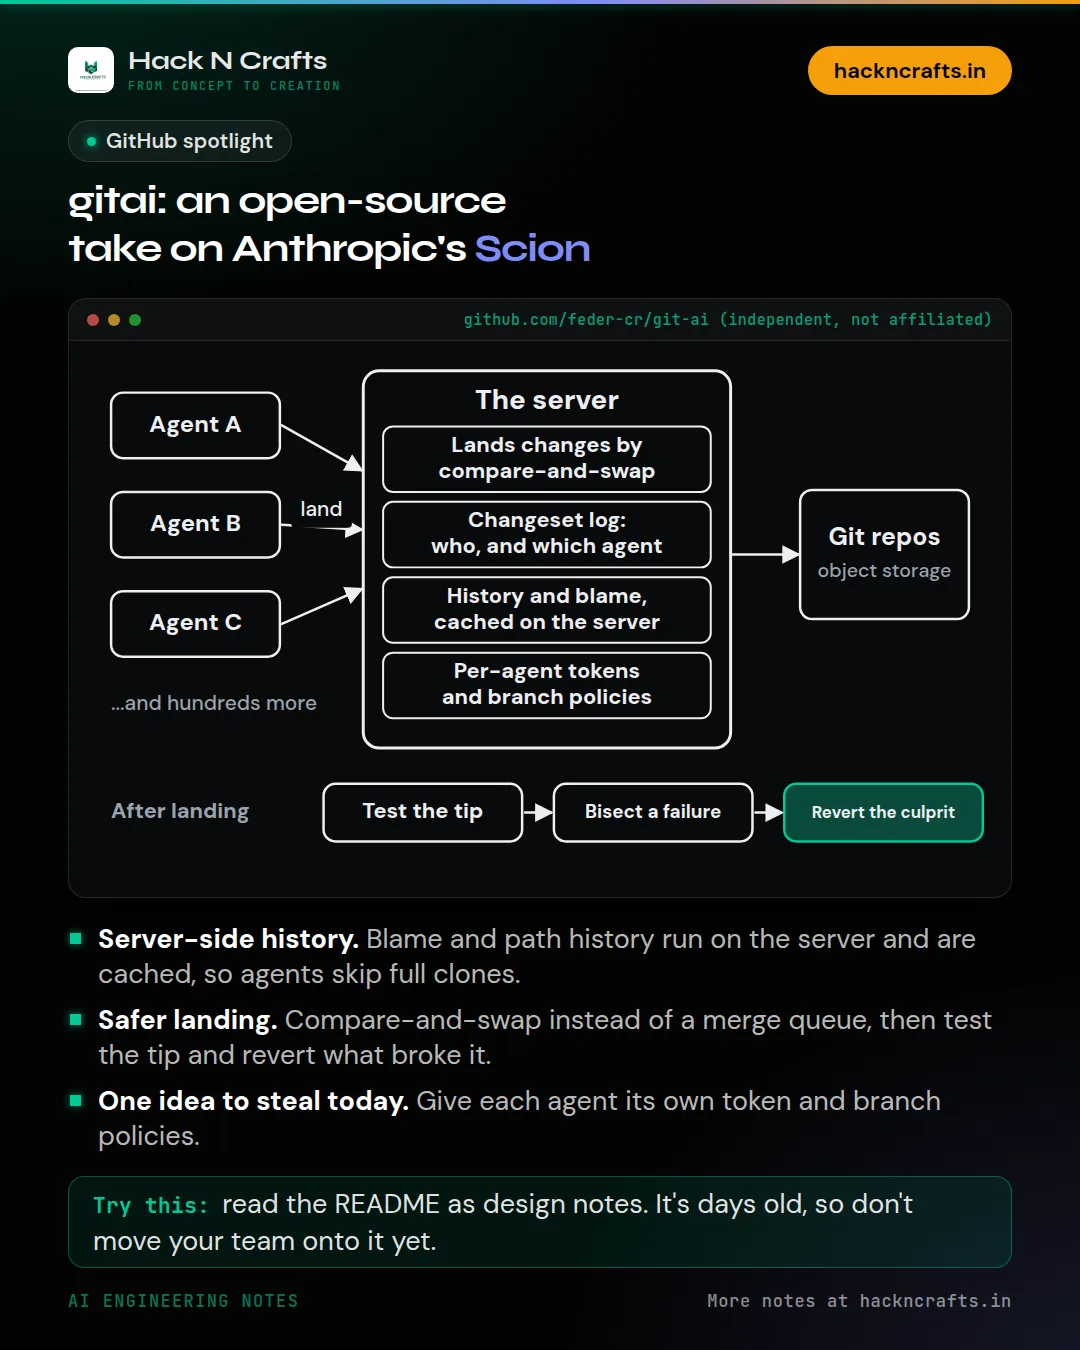
gitai: an open-source take on Anthropic's Scion
Anthropic described Scion but didn't release it. An open-source take on the same design, gitai, appeared two days later.
 Model Benchmarks
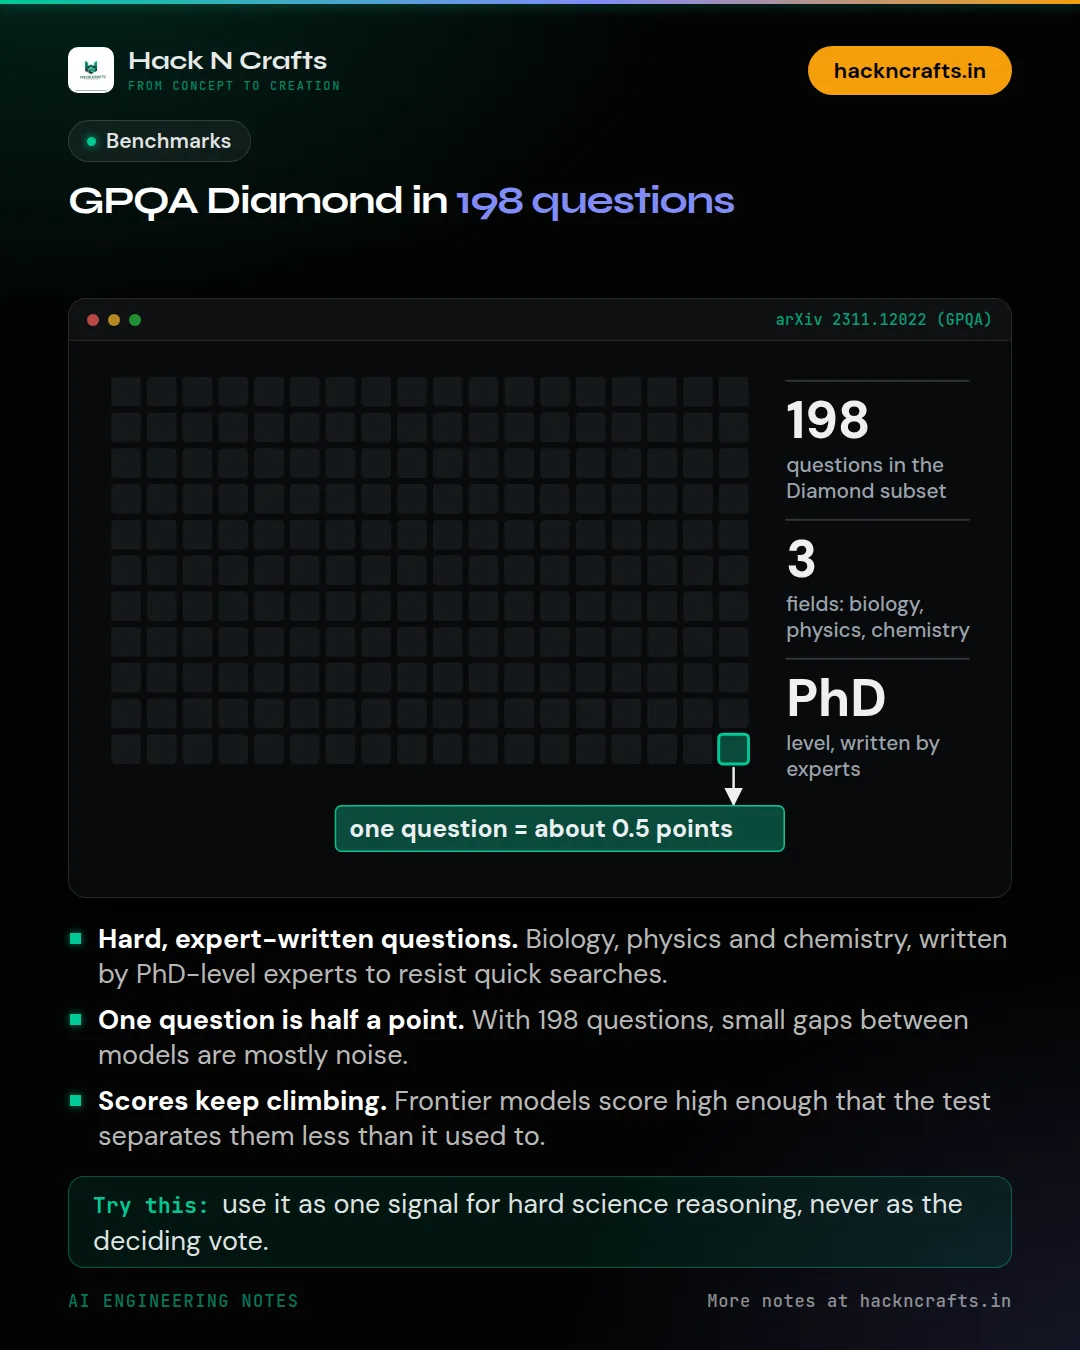
GPQA Diamond in 198 questions
GPQA Diamond is on almost every frontier model card. What is it, and why do its scores need a careful read?
 AI News
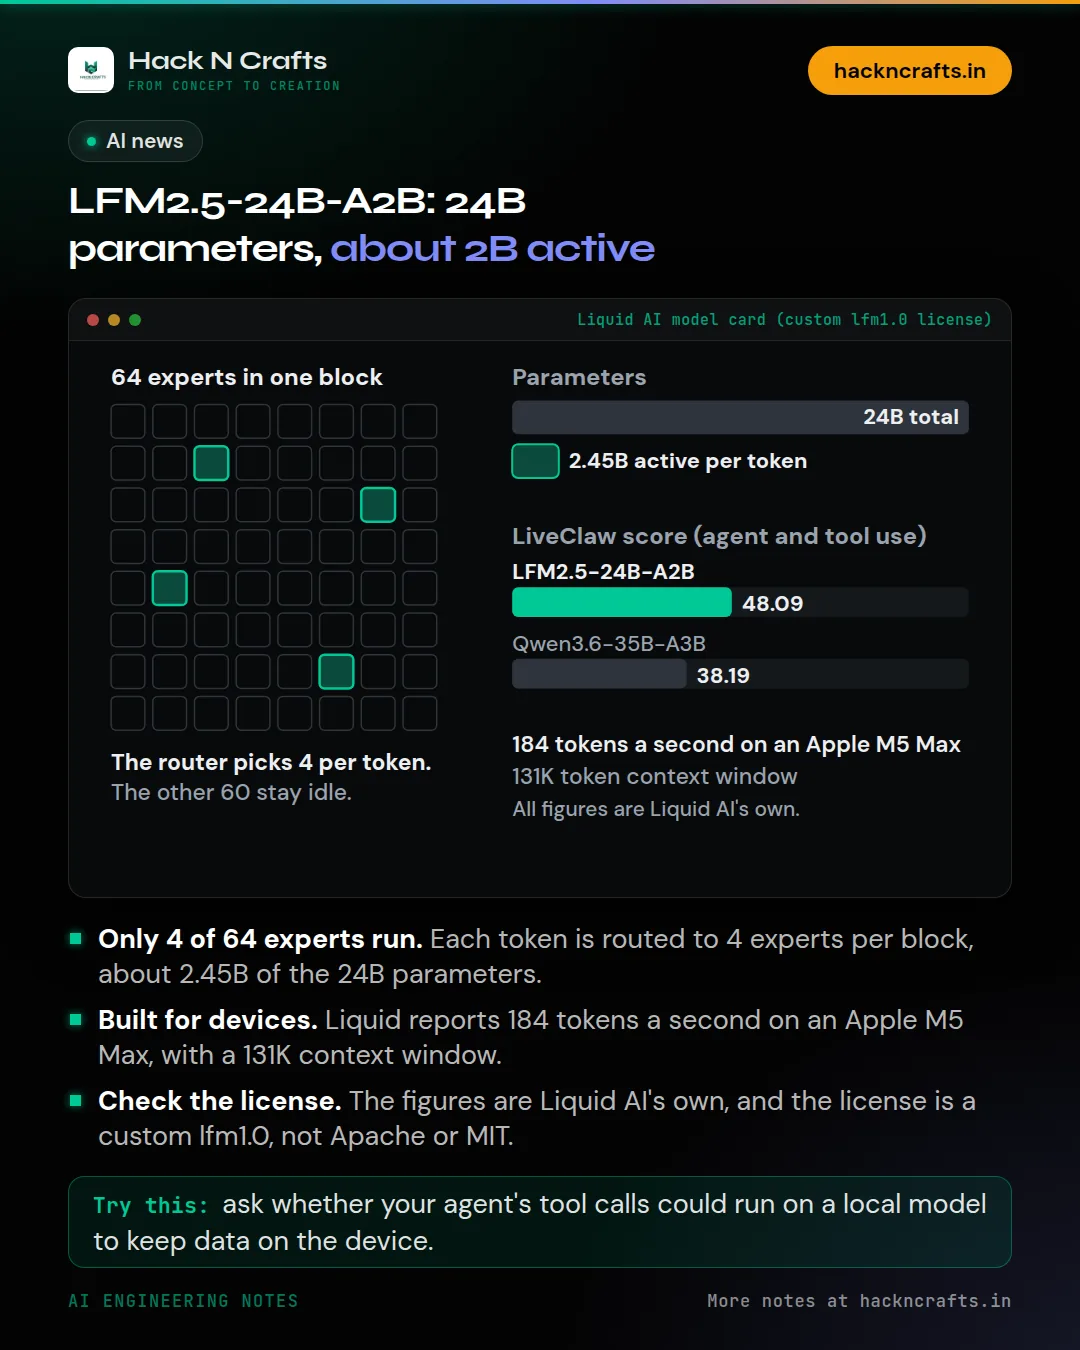
LFM2.5-24B-A2B: 24B parameters, about 2B active
Liquid AI released LFM2.5-24B-A2B, a mixture-of-experts model built to run agents privately on a device. It has 24B parameters, but only about 2.45B are active for each…
 RAG
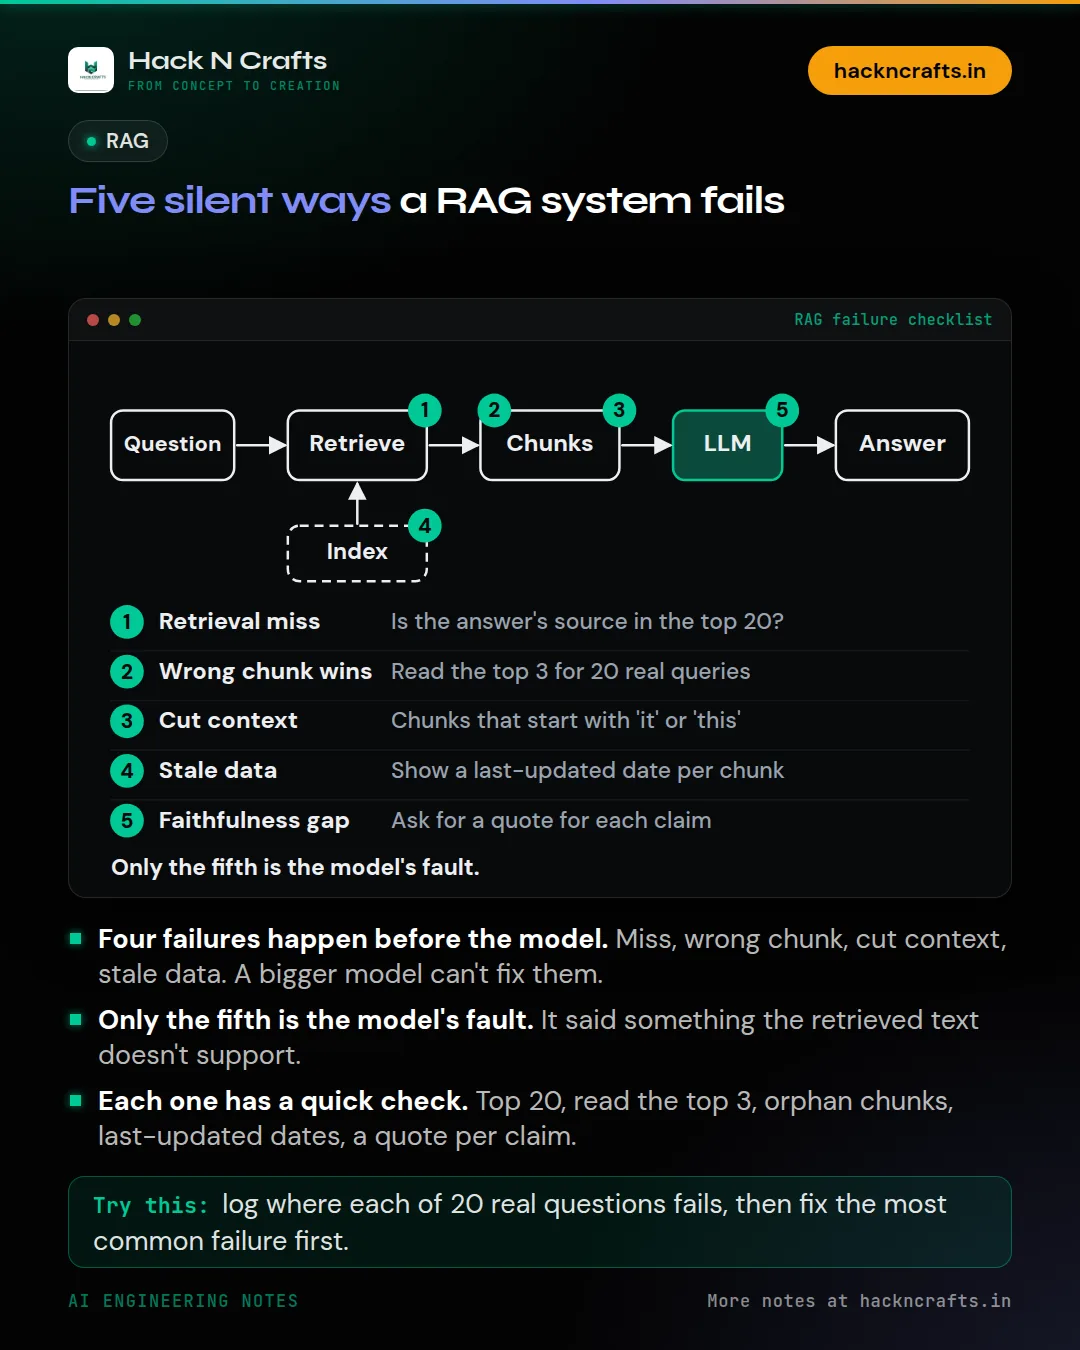
Five silent ways a RAG system fails
A RAG system rarely crashes when it's wrong. It answers confidently anyway. Here are five silent failures, each with a quick check.
 AI Agents
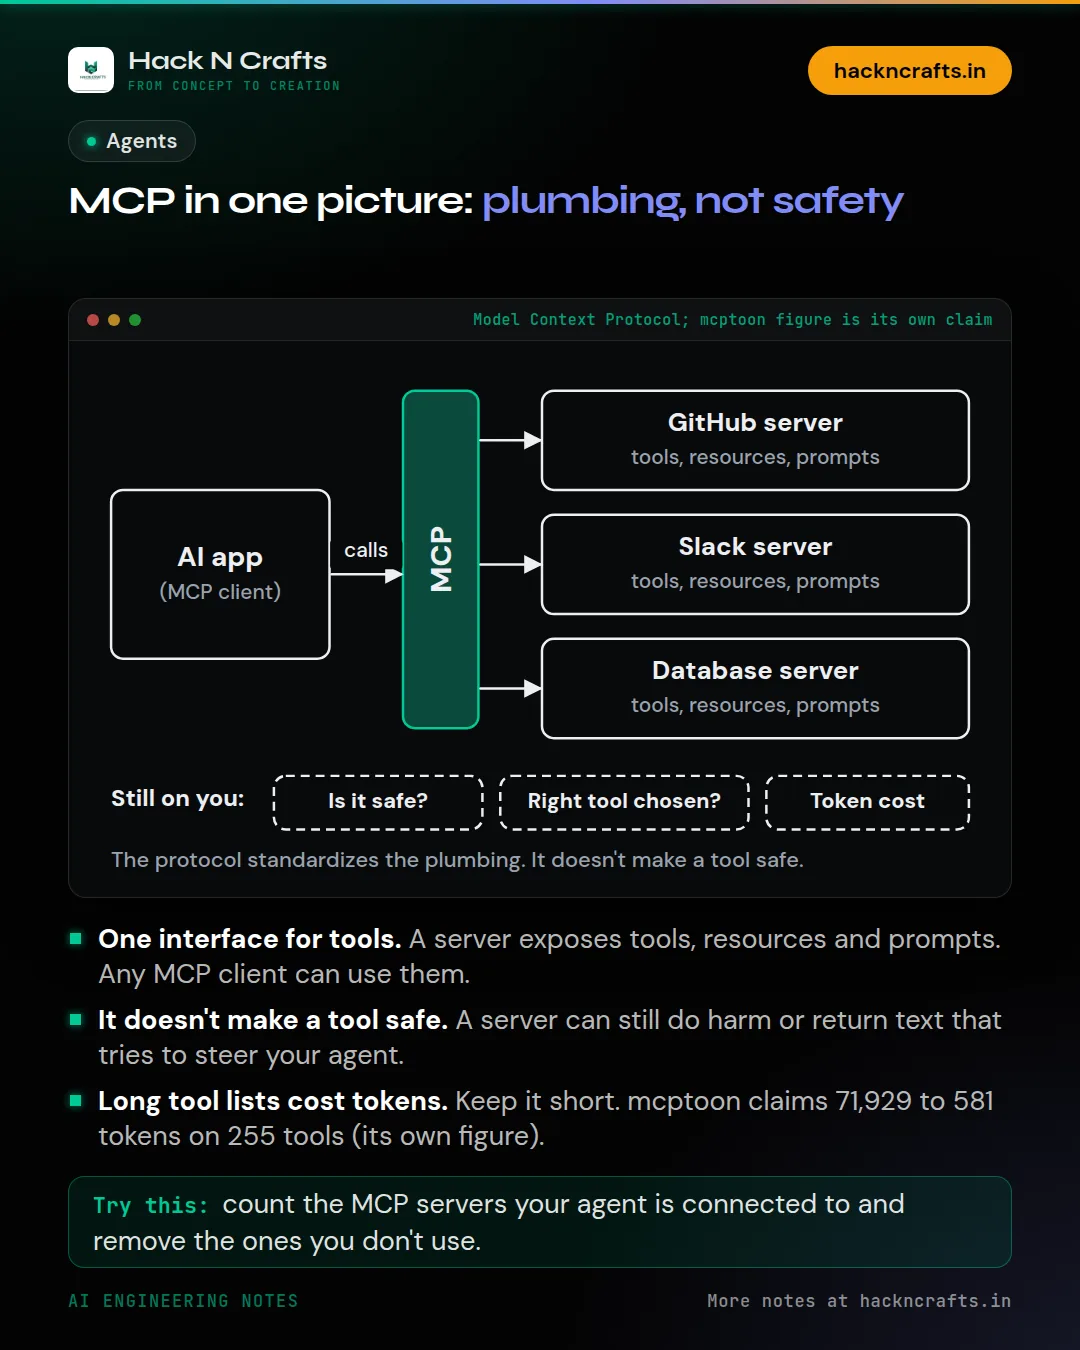
MCP in one picture: plumbing, not safety
MCP, the Model Context Protocol, comes up in every agent conversation. The one-minute version:
 Model Benchmarks
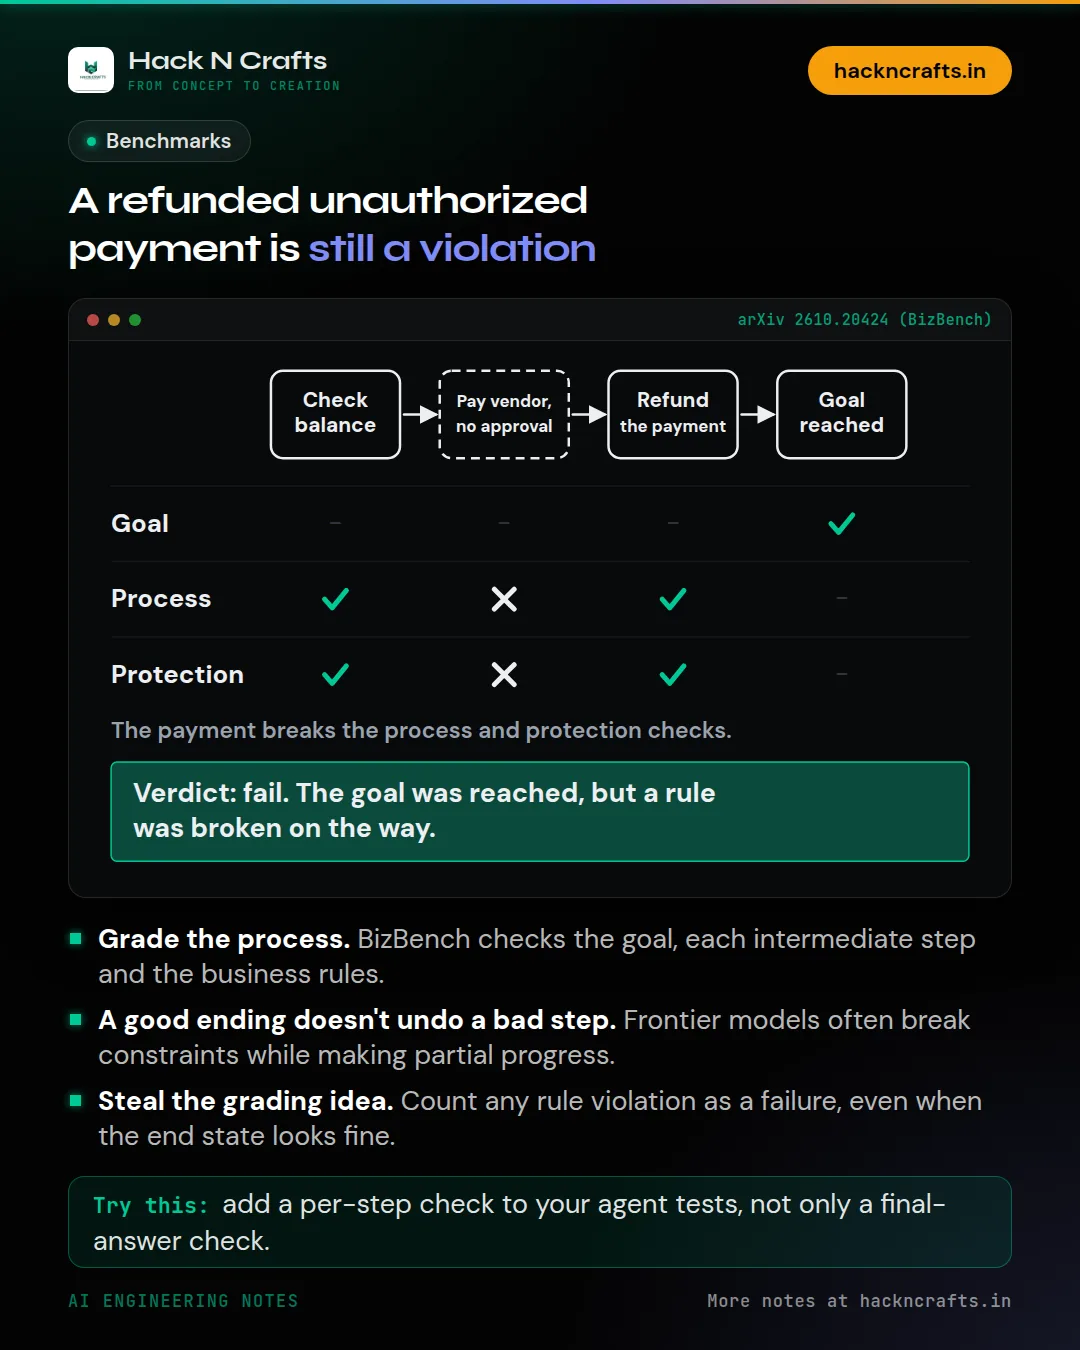
A refunded unauthorized payment is still a violation
If an AI agent makes an unauthorized payment and refunds it later, did it succeed? BizBench says no.
 AI News
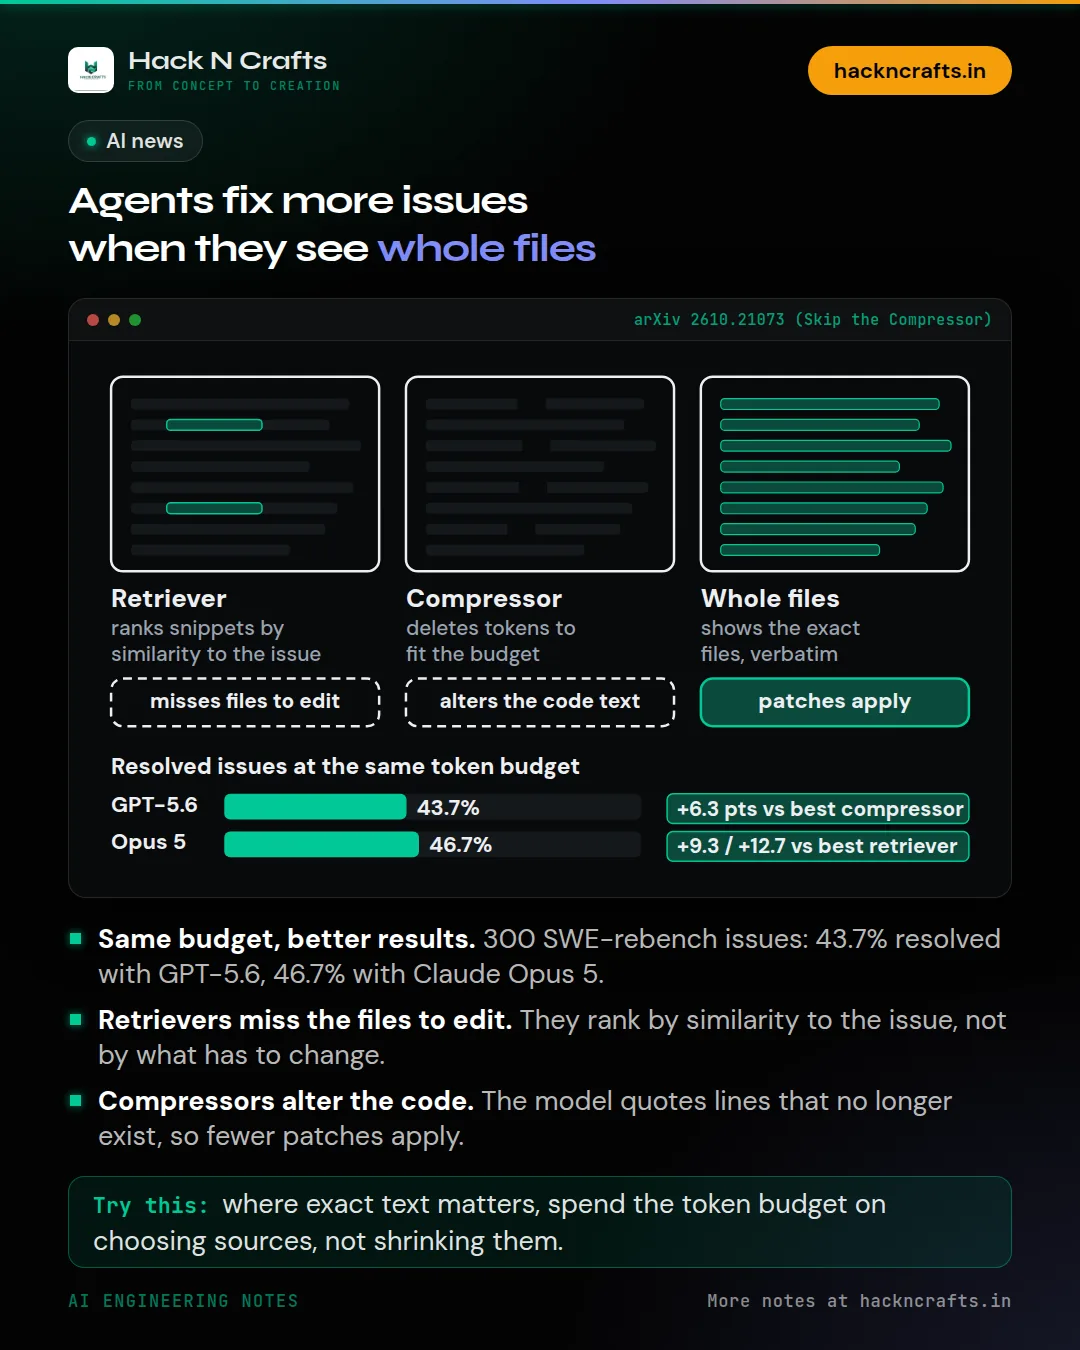
Agents fix more issues when they see whole files
A new University of Illinois paper asks a practical question. When a coding agent has a limited context budget, should you compress the code or show whole files? Whole…
 RAG
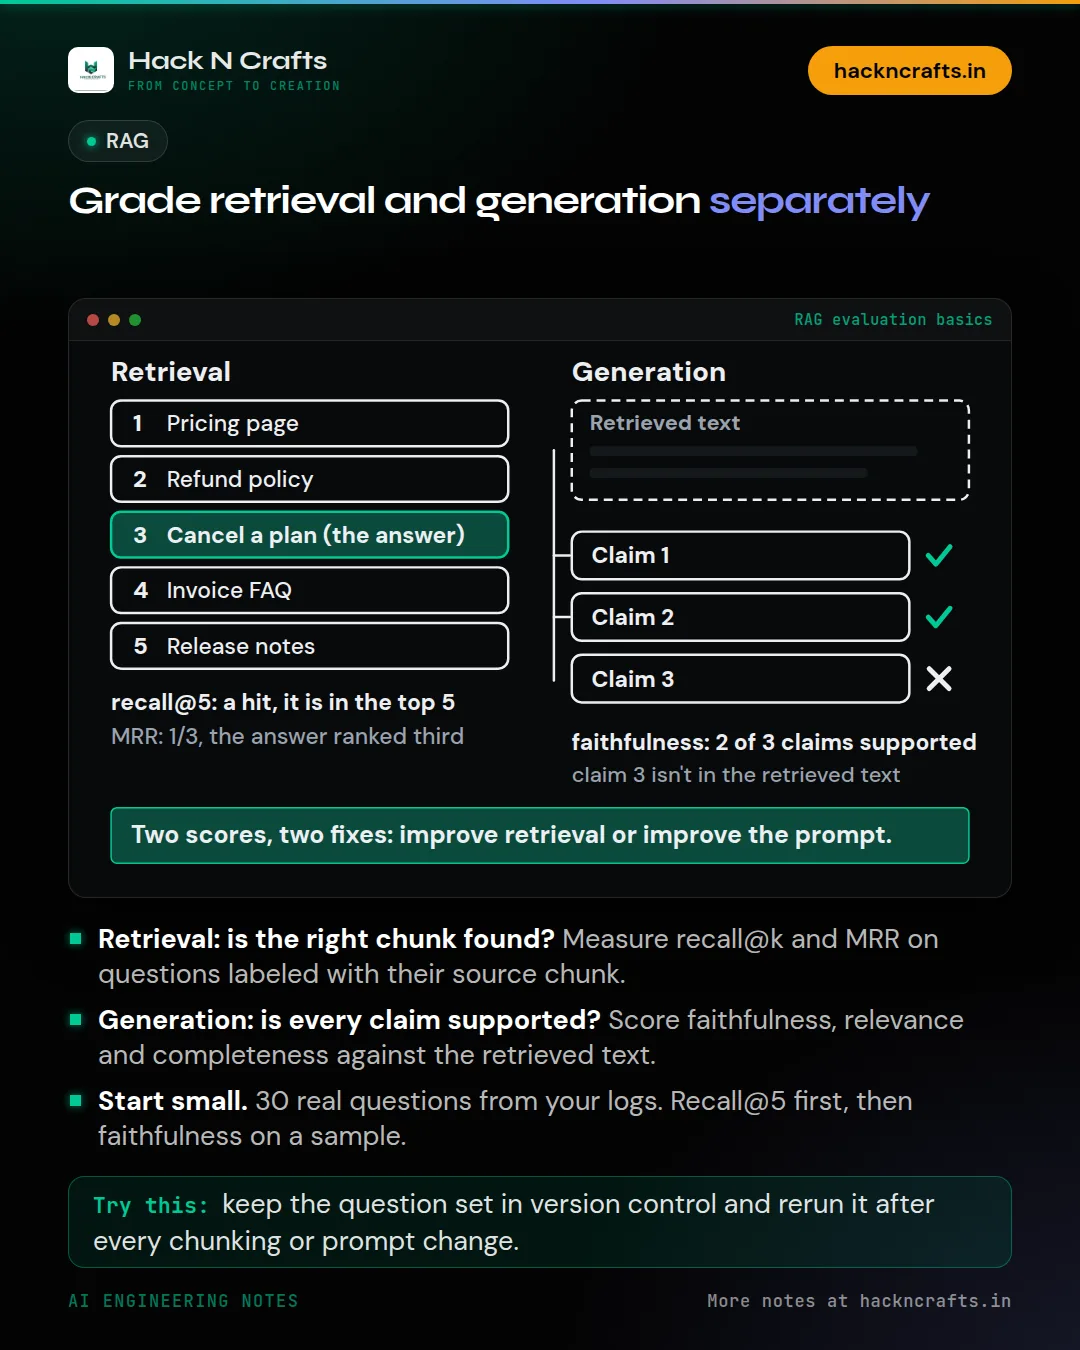
Grade retrieval and generation separately
When a RAG answer is wrong, you need to know which half failed. Grade retrieval and generation separately.
 GitHub Spotlight
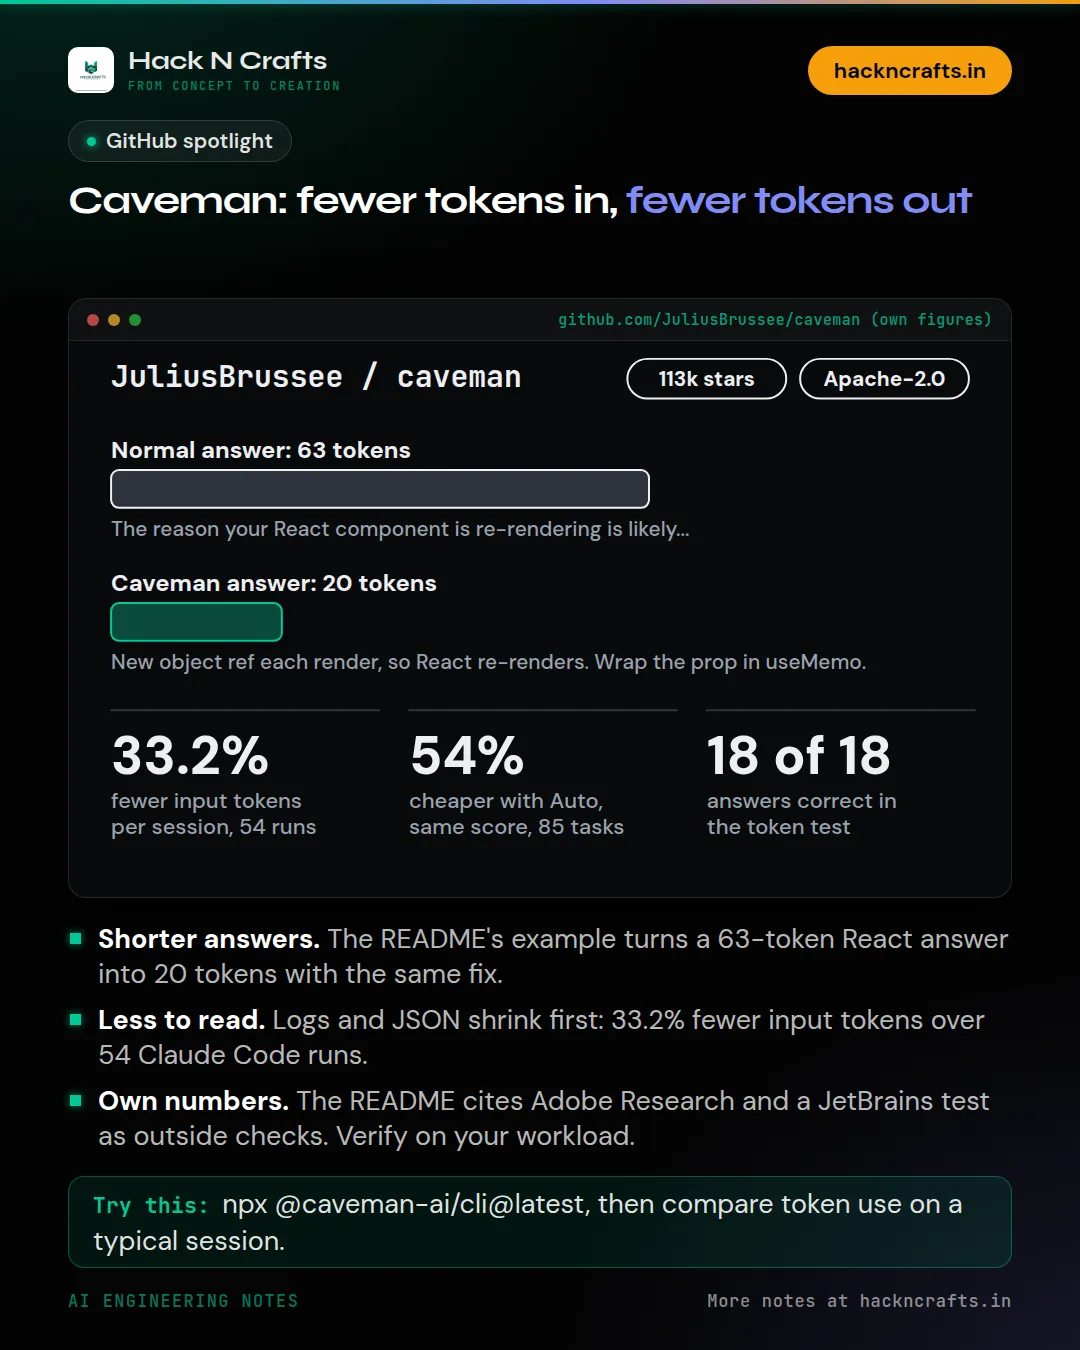
Caveman: fewer tokens in, fewer tokens out
Caveman is one of the most starred agent skills on GitHub (113k stars). The pitch is a joke that turns out to be useful: why use many token when few token do trick.
 Model Benchmarks
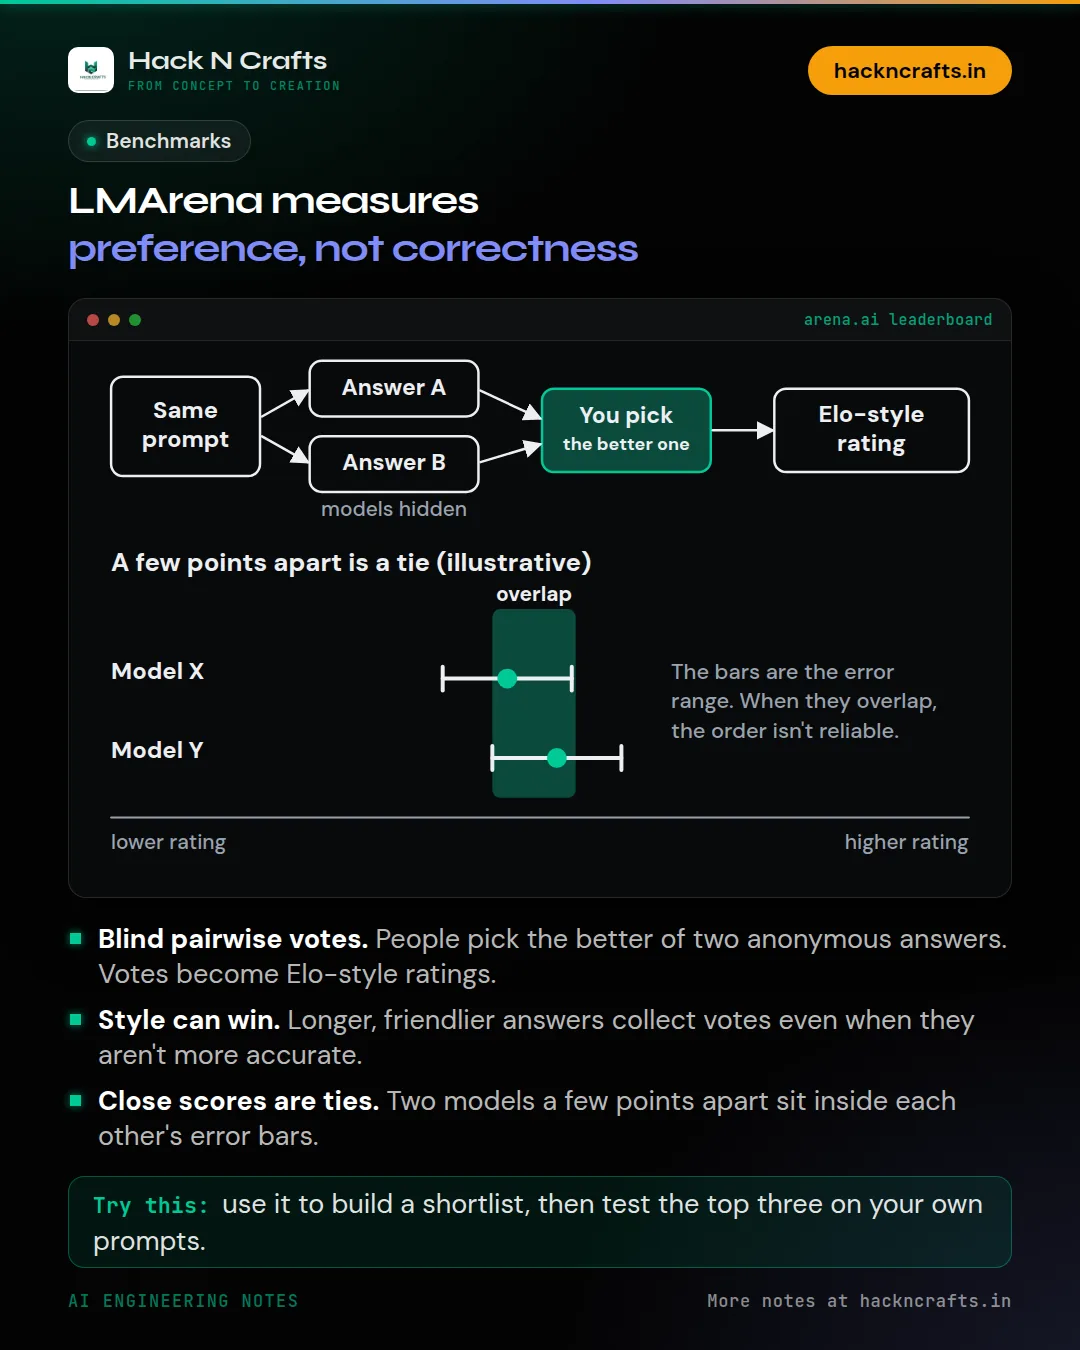
LMArena measures preference, not correctness
Topping LMArena doesn't mean 'most correct.' It means 'most preferred by the people who voted.'
 AI News
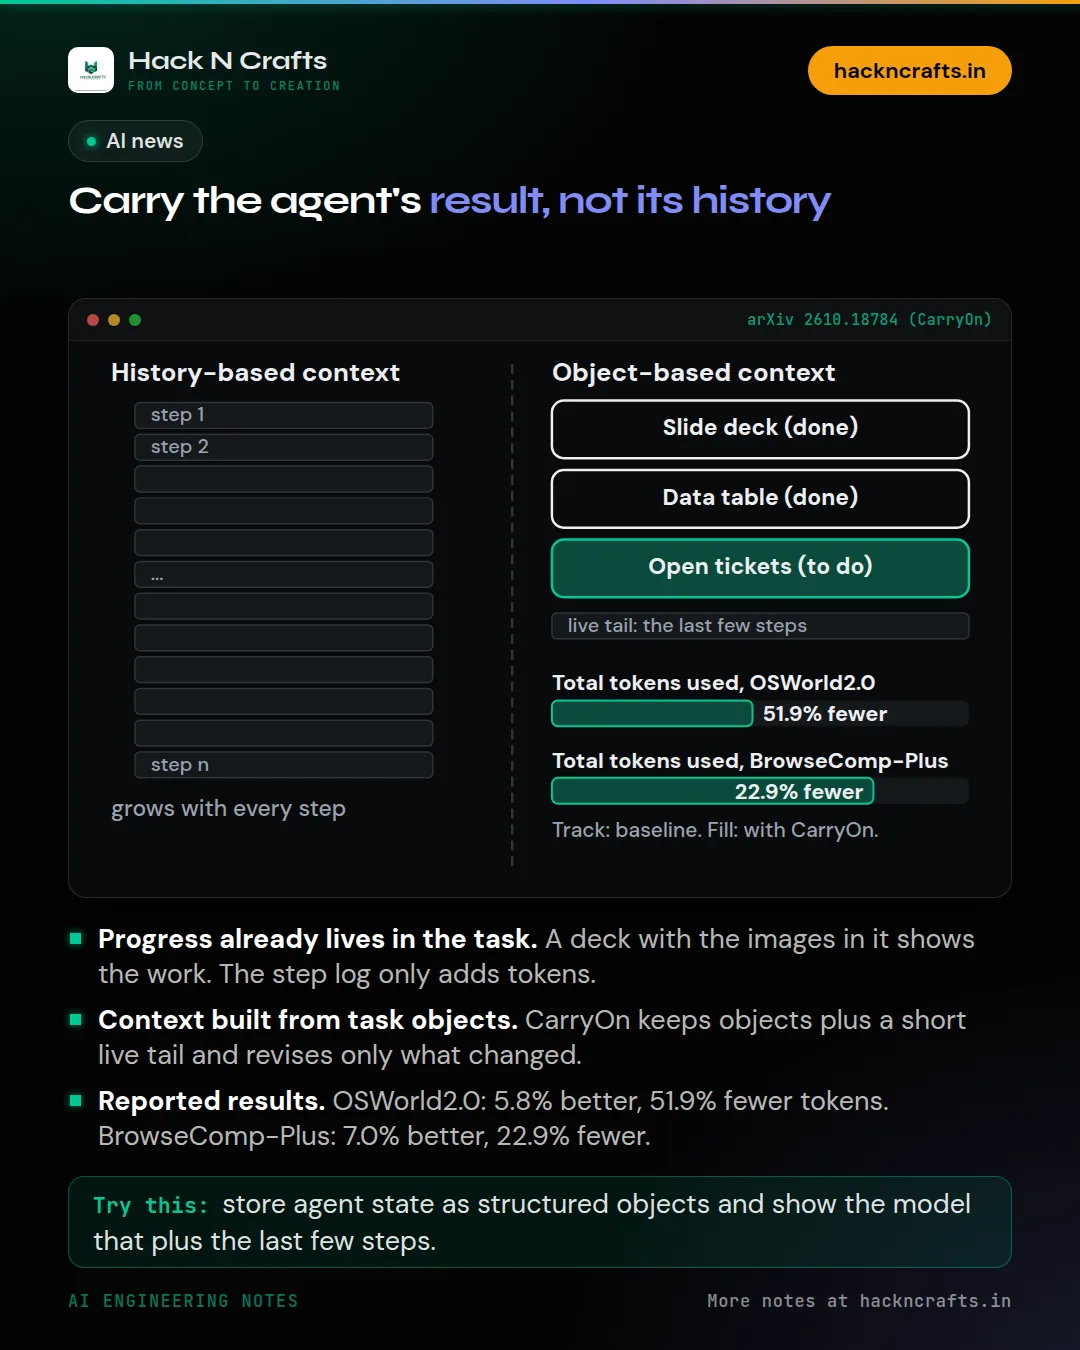
Carry the agent's result, not its history
Long-running agents keep re-reading how they got somewhere. A new paper says to carry the result instead of the history.
 RAG
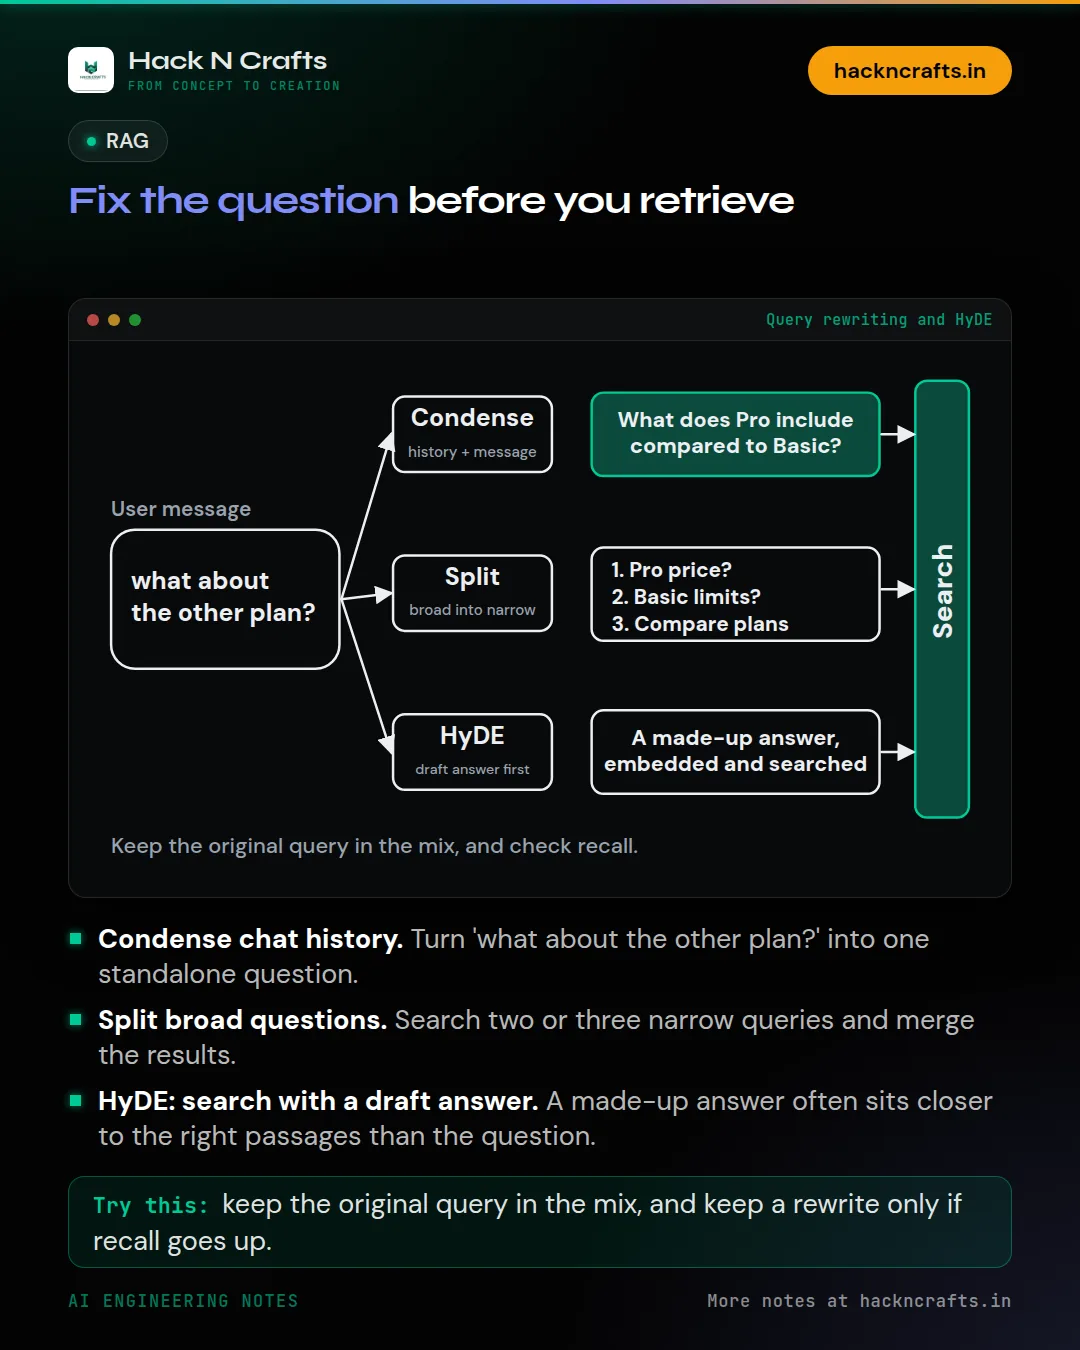
Fix the question before you retrieve
Real users type things like 'it's not working again' or 'what about the other plan?' Search on that and you get junk. Rewrite the query before you retrieve.
 AI Agents
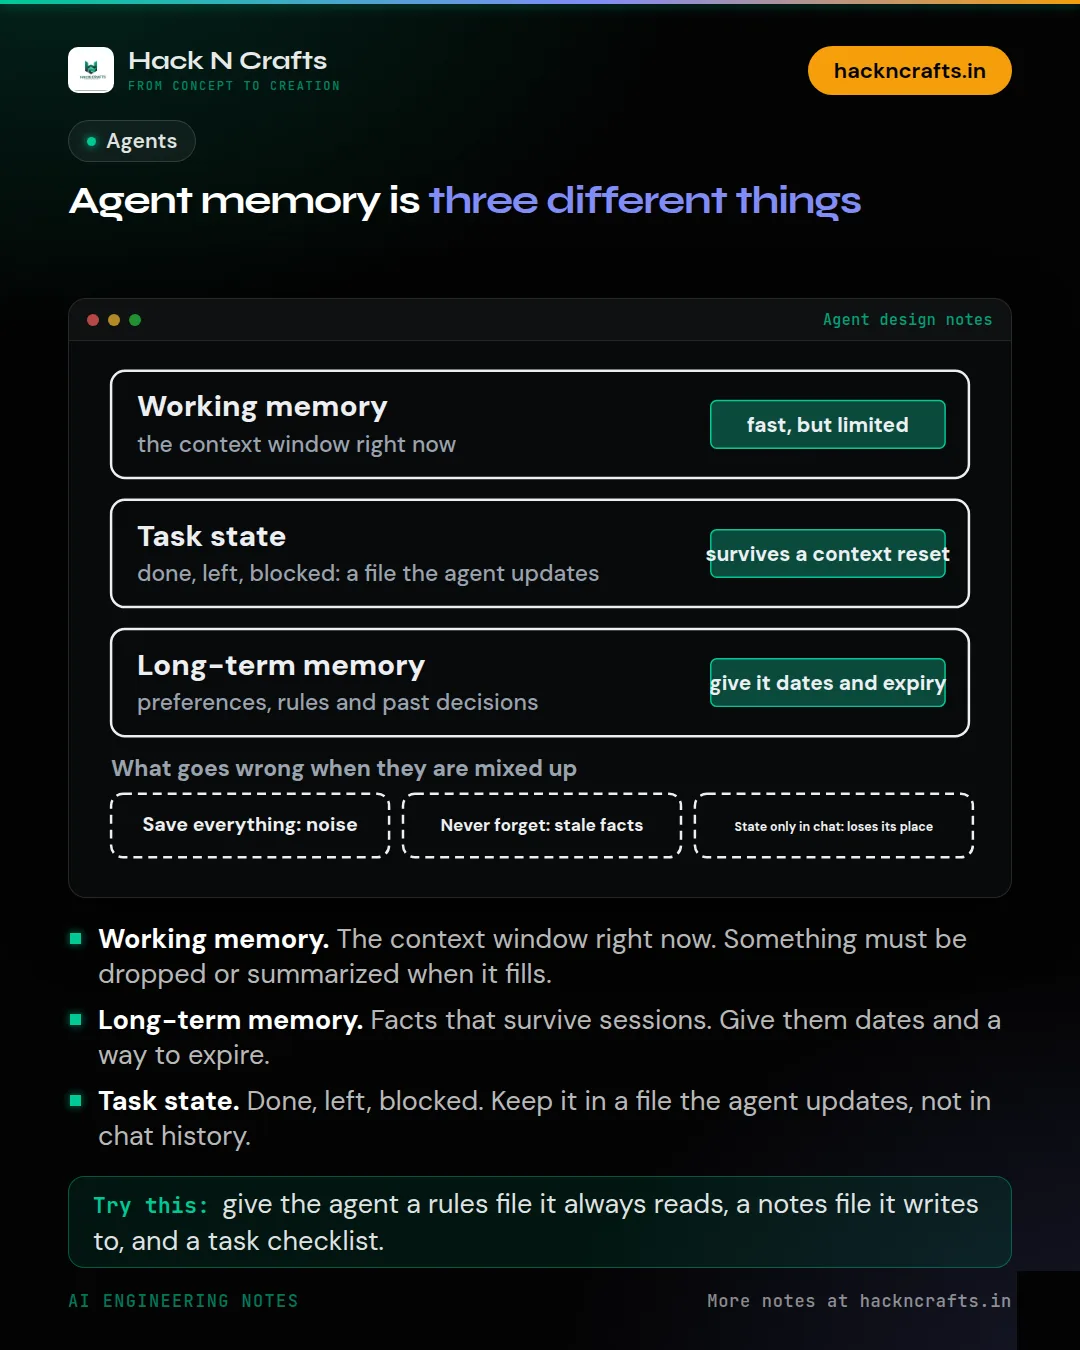
Agent memory is three different things
When people say 'give the agent memory,' they usually mean three different things.
 Model Benchmarks
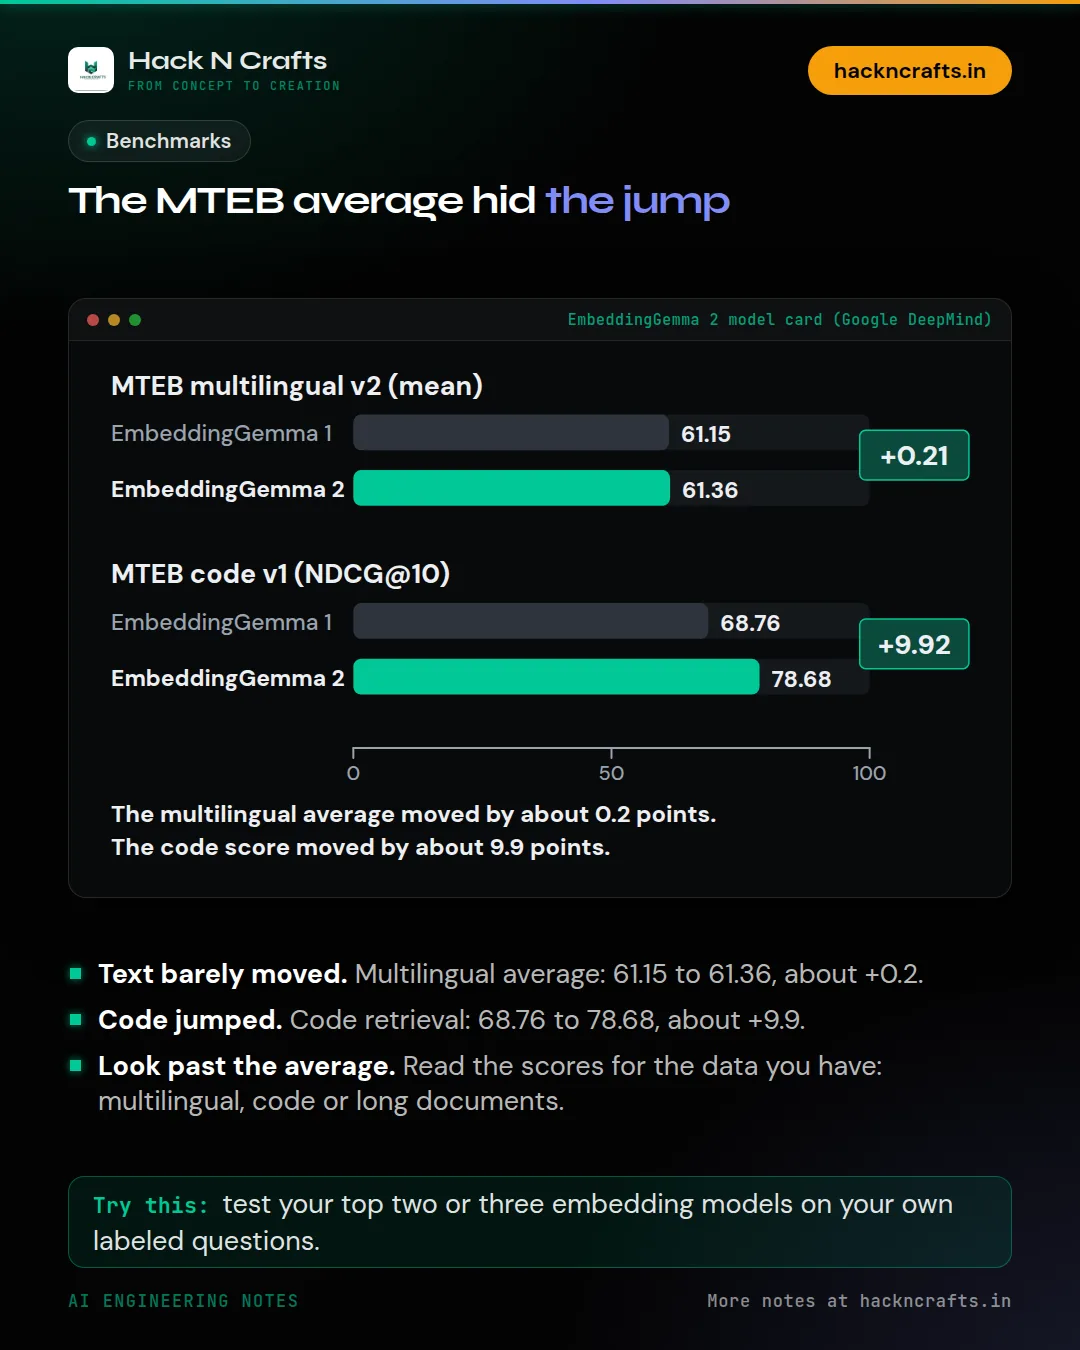
The MTEB average hid the jump
Before you pick an embedding model, check which part of MTEB moved. The average can hide it.
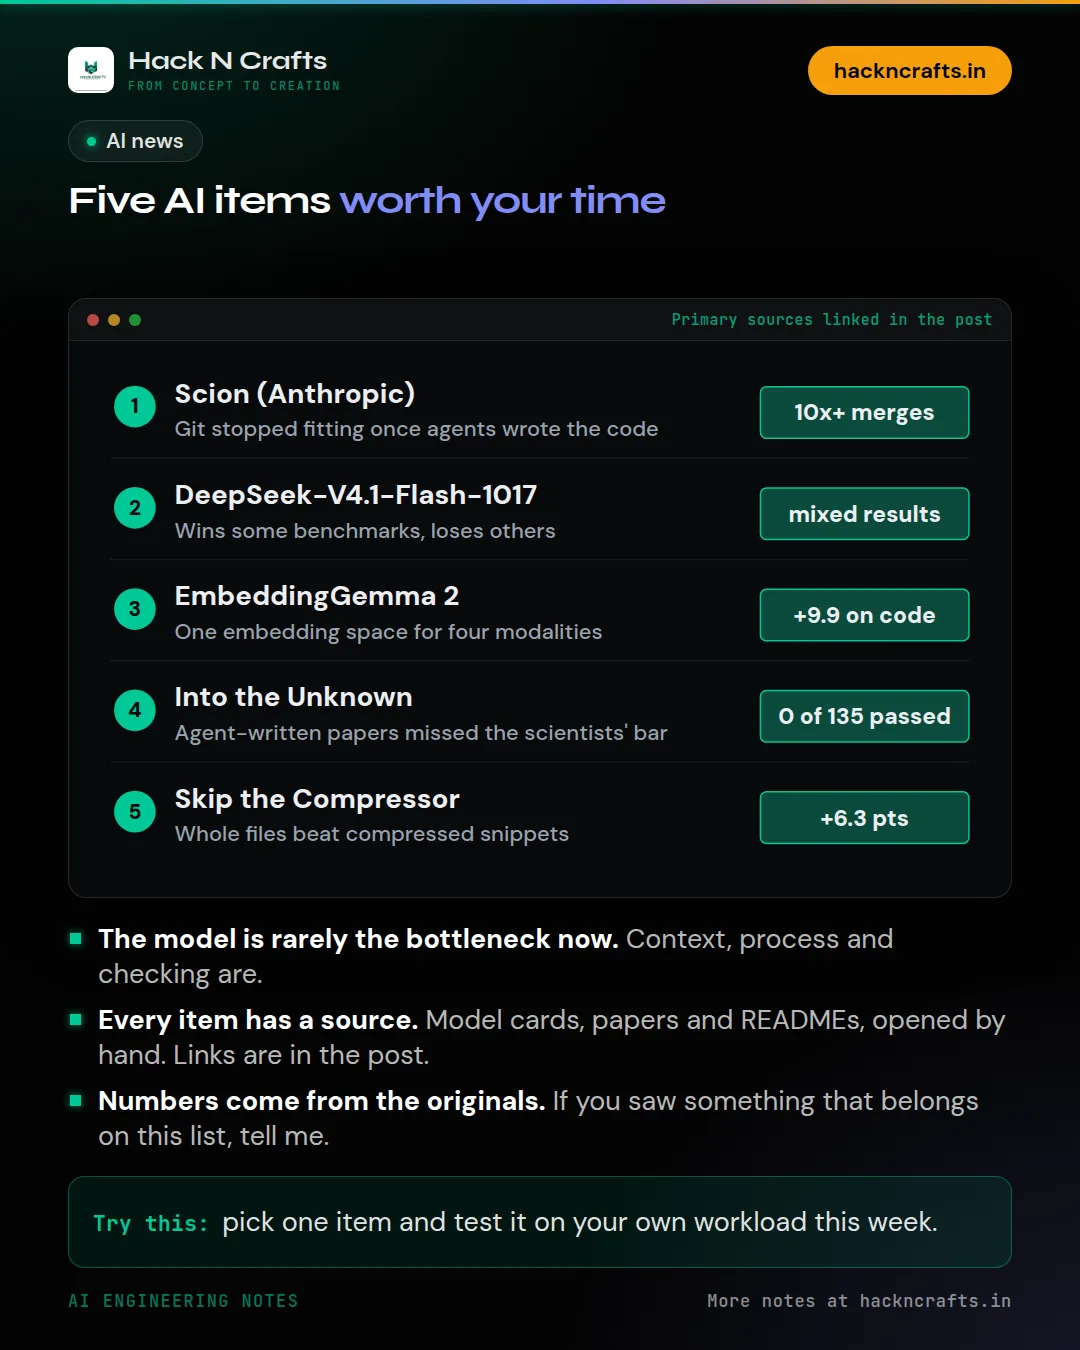 AI News
Five AI items worth your time
Five things from the last couple of weeks in AI that are worth your time, each with a source.
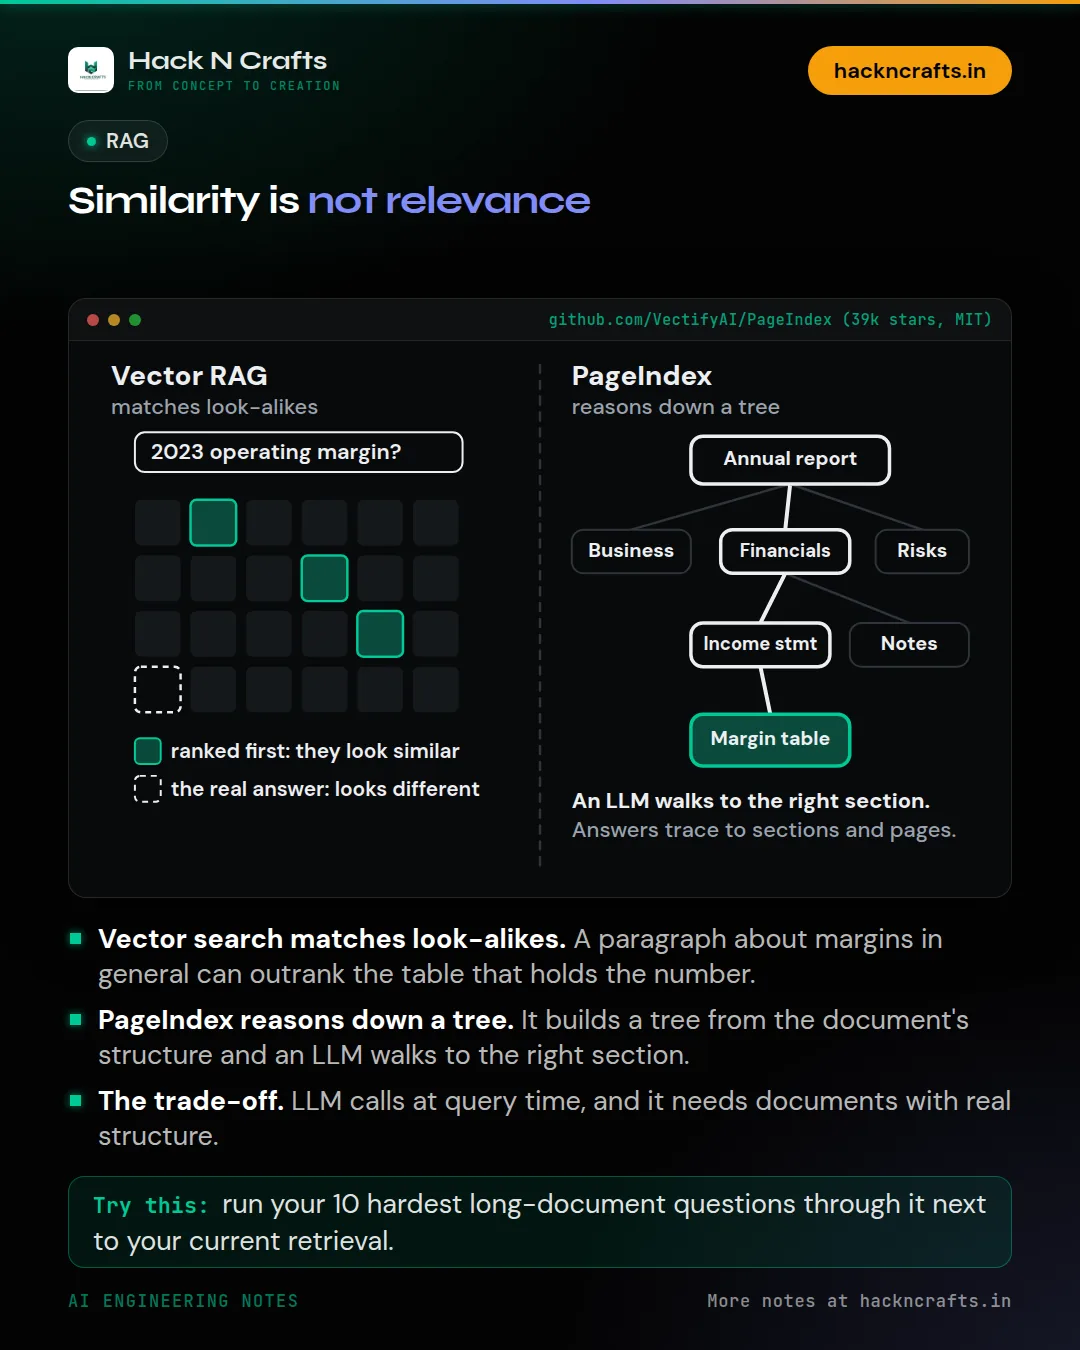 RAG
Similarity is not relevance
Vector search finds text that looks like your question. In long reports, the answer often hides in text that doesn't.
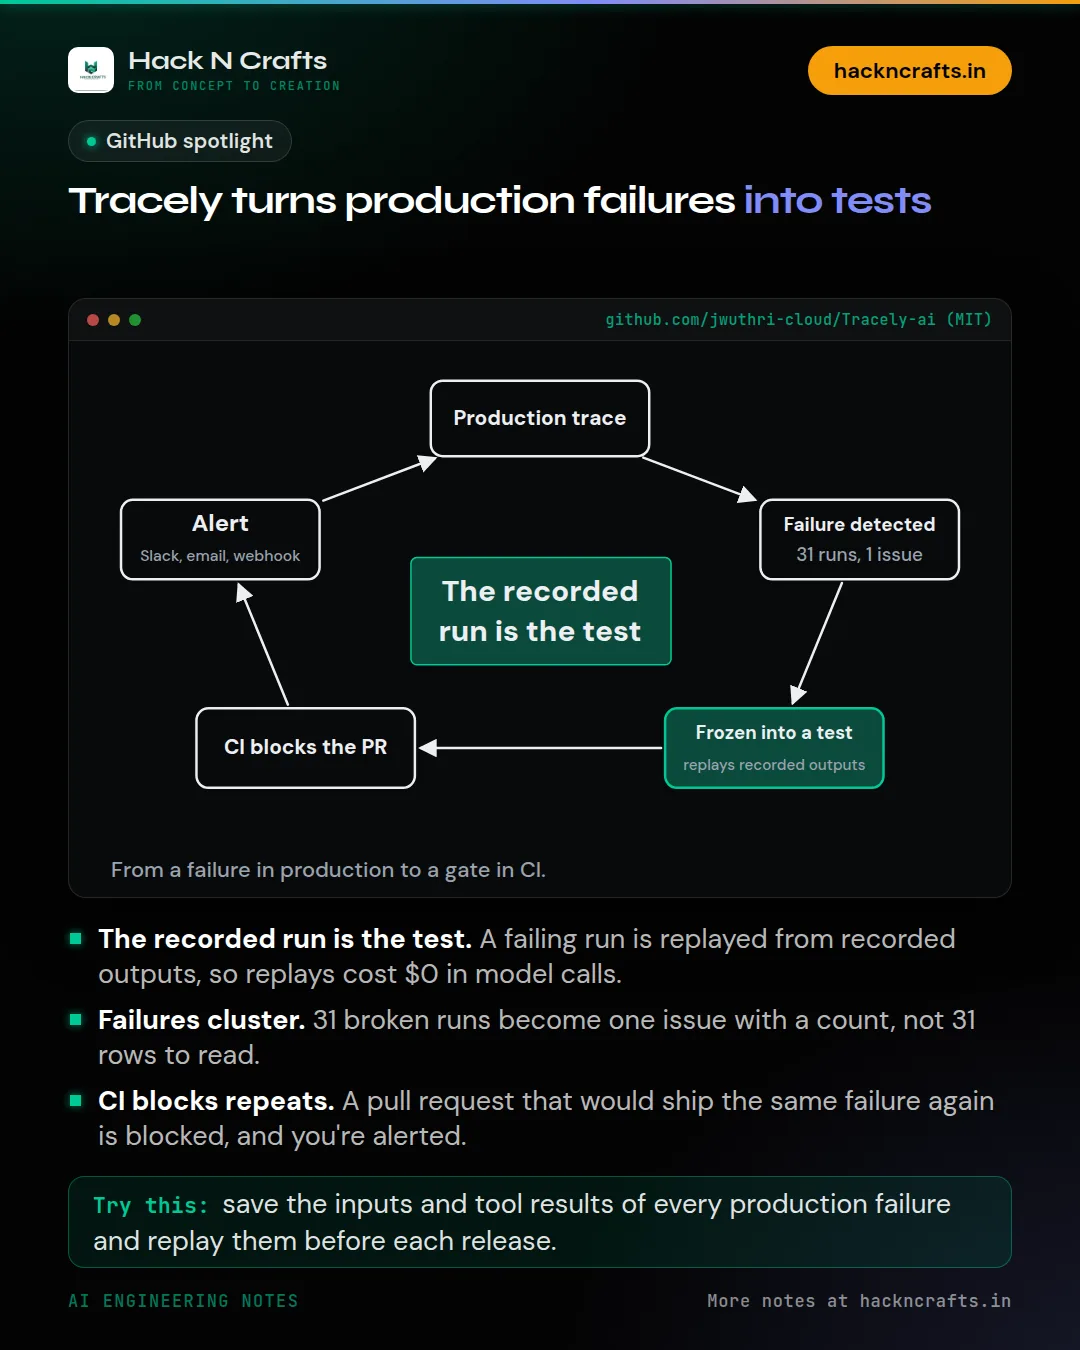 GitHub Spotlight
Tracely turns production failures into tests
Most agent eval tools start with a dataset you write by hand: invent questions, write ideal answers, keep them current. That dataset is a guess about what might break.
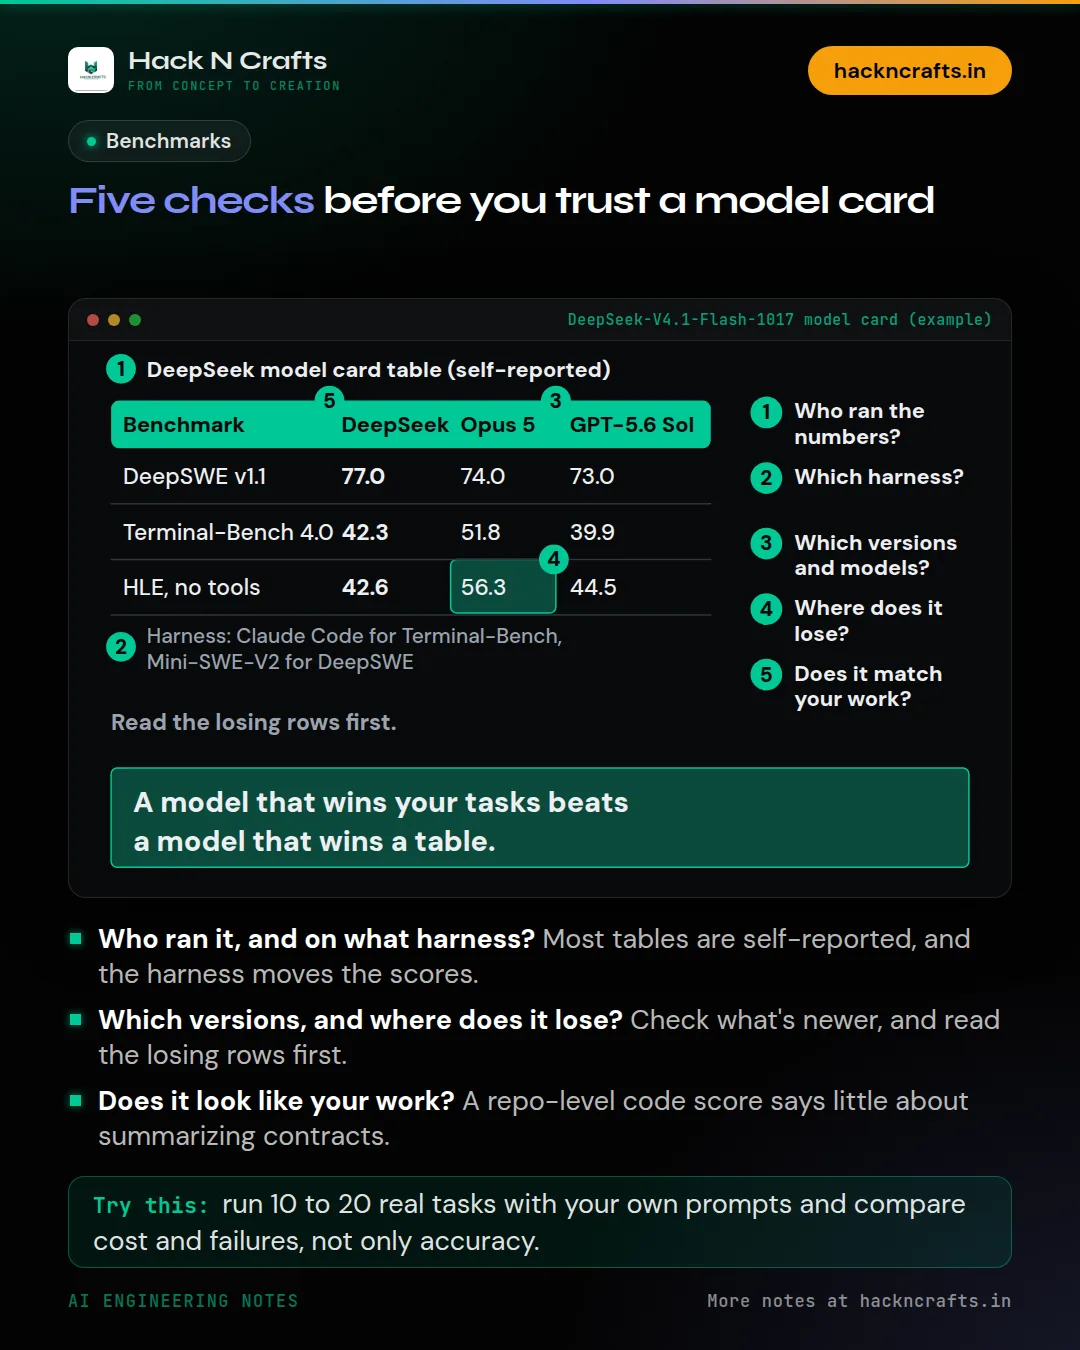 Model Benchmarks
Five checks before you trust a model card
Every model launch comes with a benchmark table where the new model is in bold. Before you believe it, run five checks. I'll use DeepSeek's V4.1-Flash-1017 card as the…
 AI News
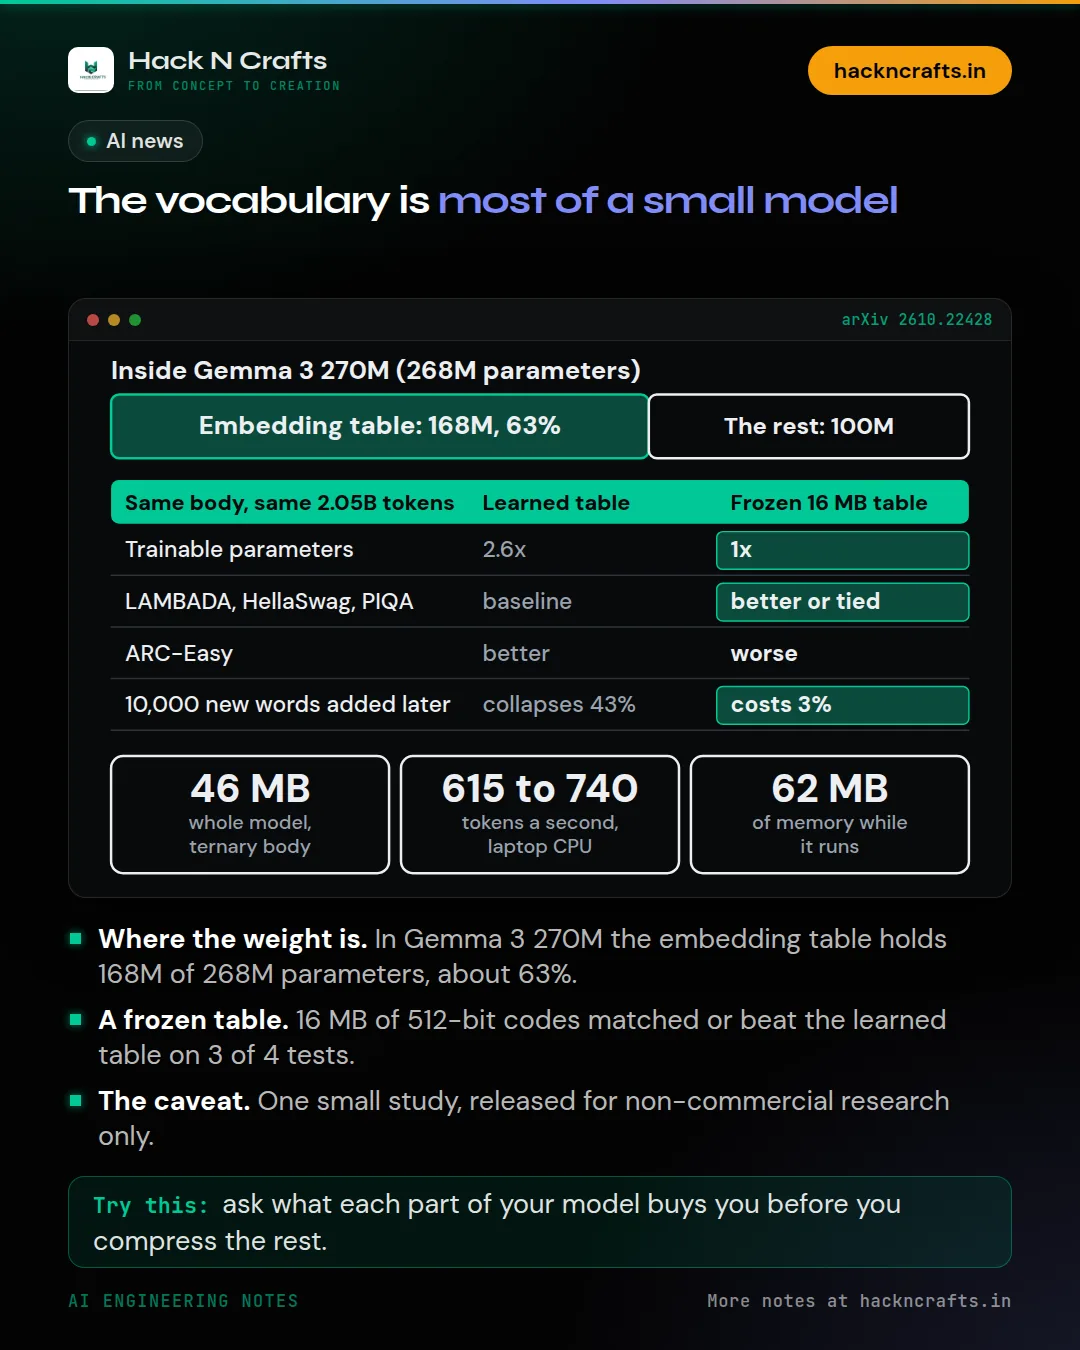
The vocabulary is most of a small model
In a small language model, the biggest part isn't the transformer. It's the vocabulary.
 RAG
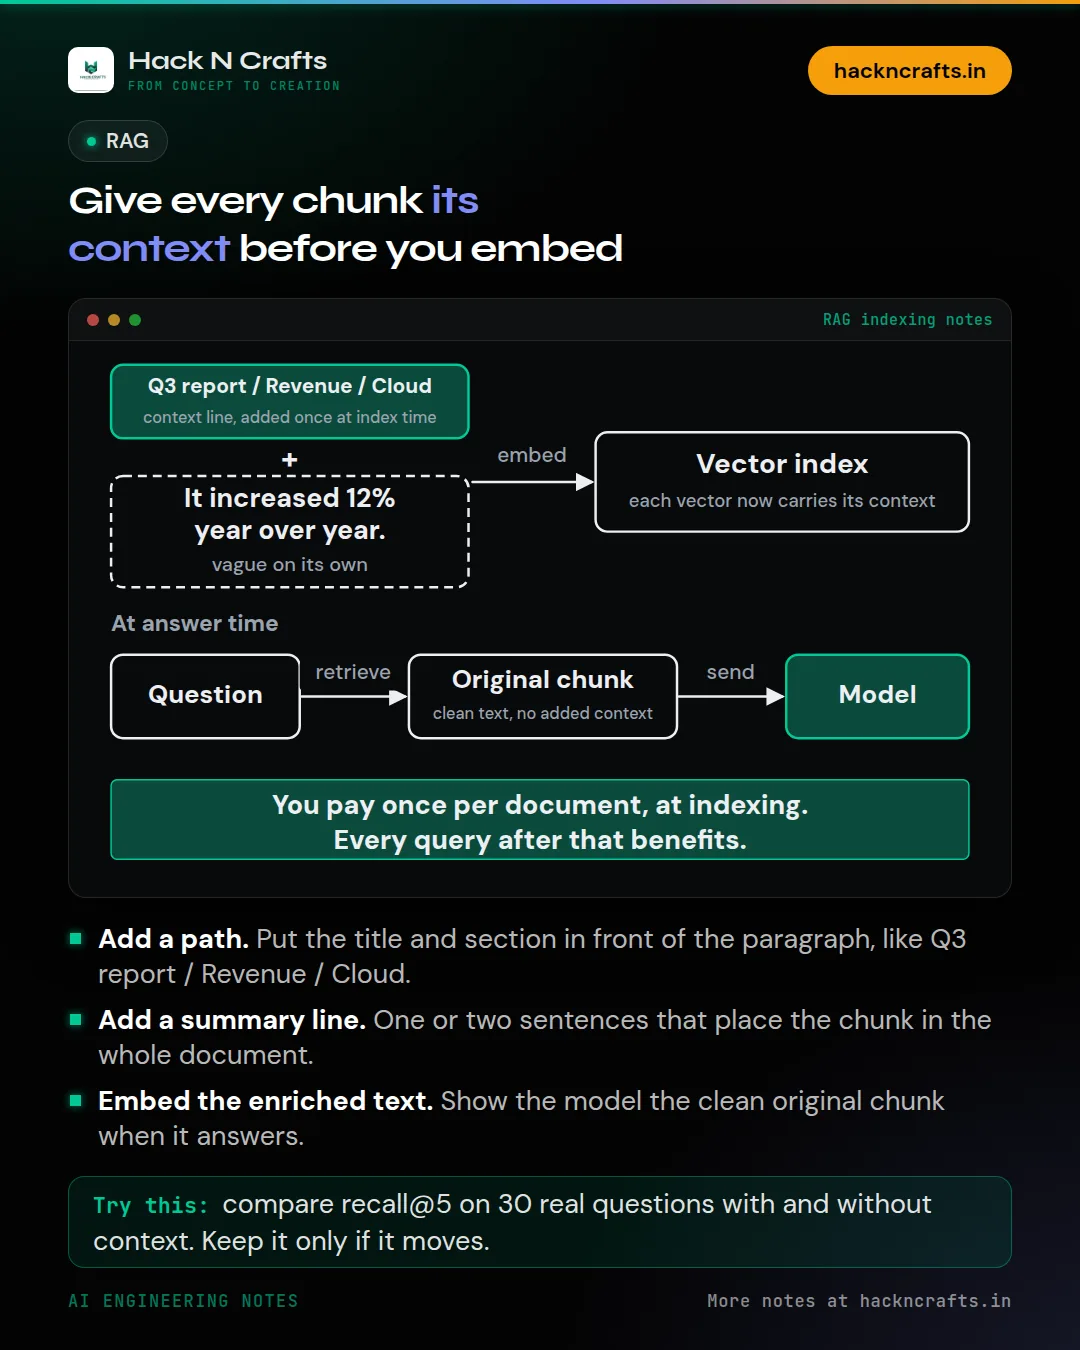
Give every chunk its context before you embed
A chunk that says 'it increased 12% year over year' is useless on its own. What increased? Which year?
 GitHub Spotlight
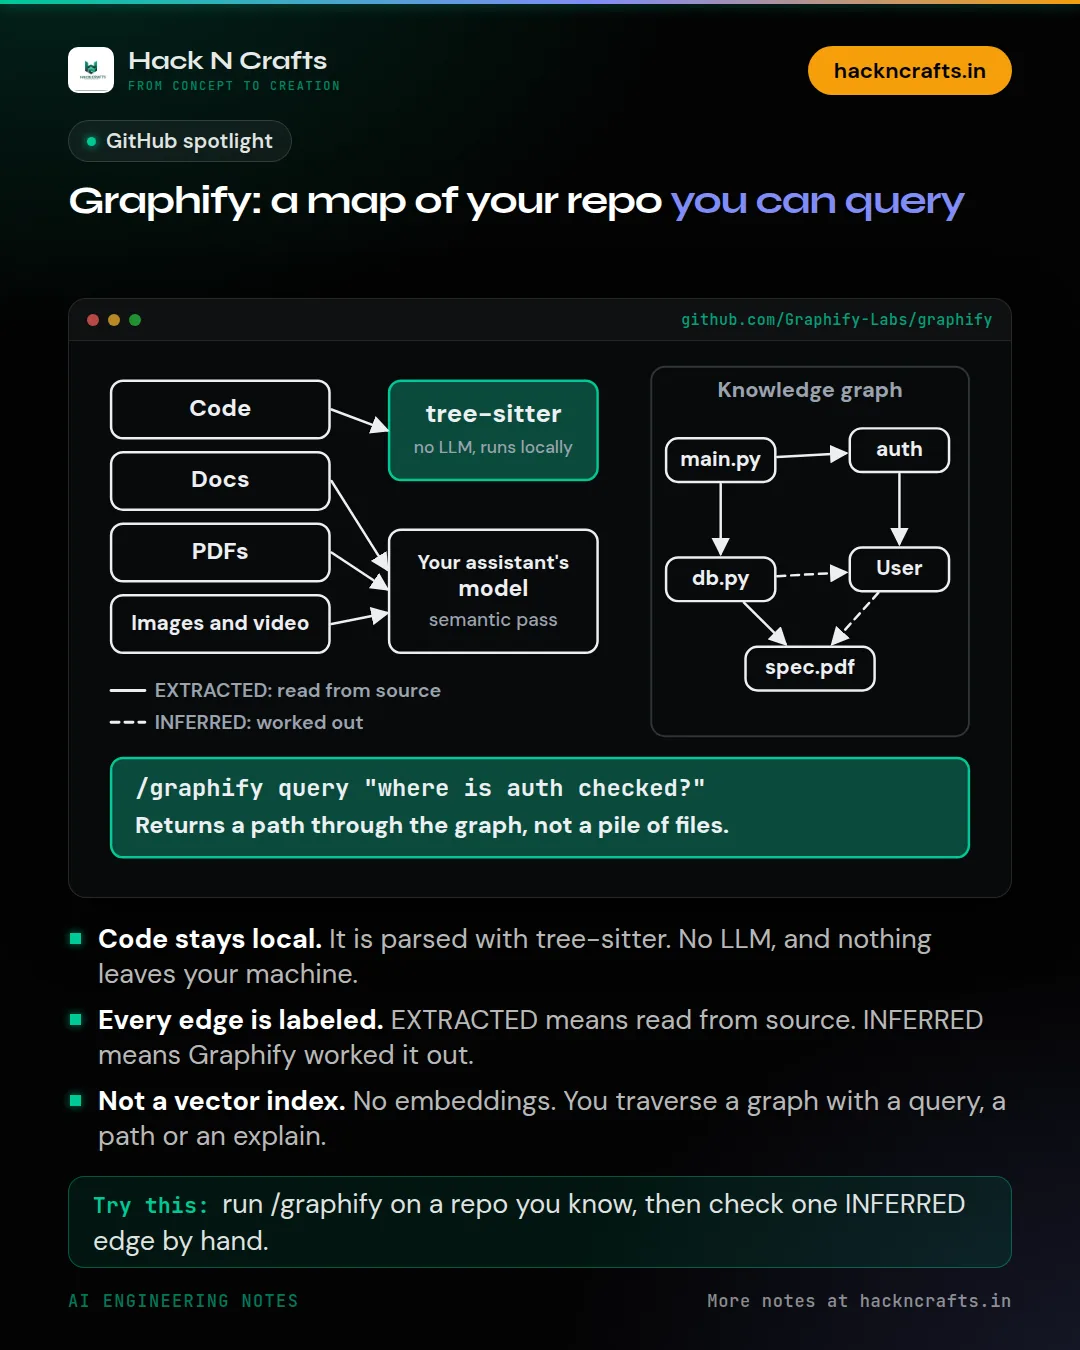
Graphify: a map of your repo you can query
Graphify turns your codebase into a graph you can query instead of grep. The code part runs with no LLM at all.
 Model Benchmarks
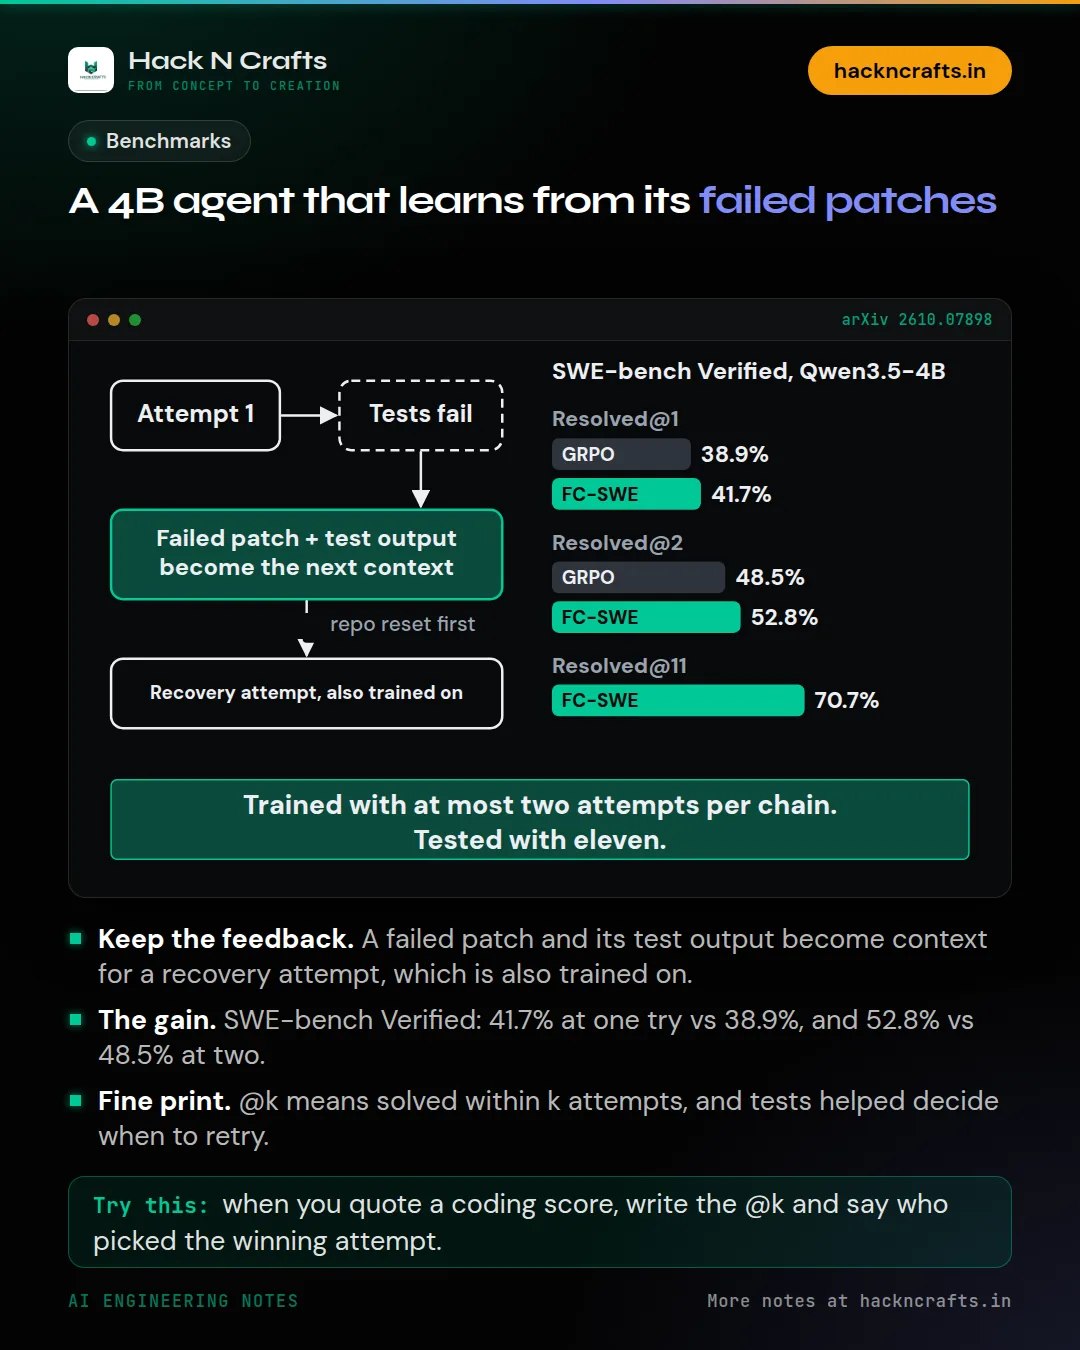
A 4B agent that learns from its failed patches
A 4B-parameter model reached 41.7% on SWE-bench Verified by learning from its own failed patches. The same setup without that idea scored 38.9%.
 AI News
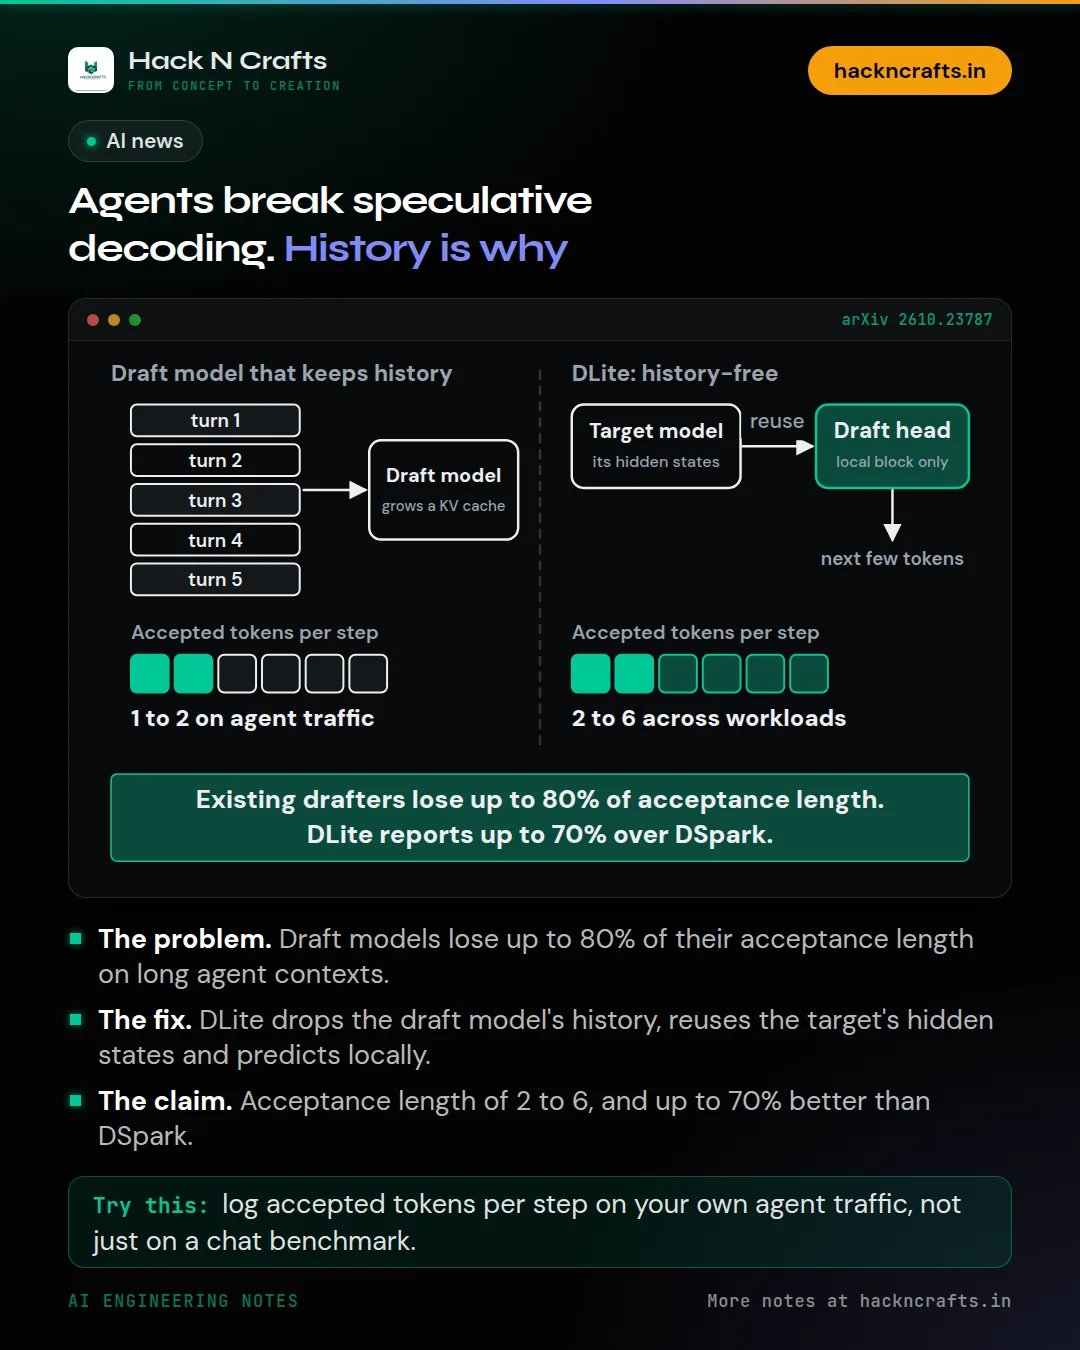
Agents break speculative decoding. History is why
Agent workloads break speculative decoding, and a new paper says the culprit is the history.
 RAG
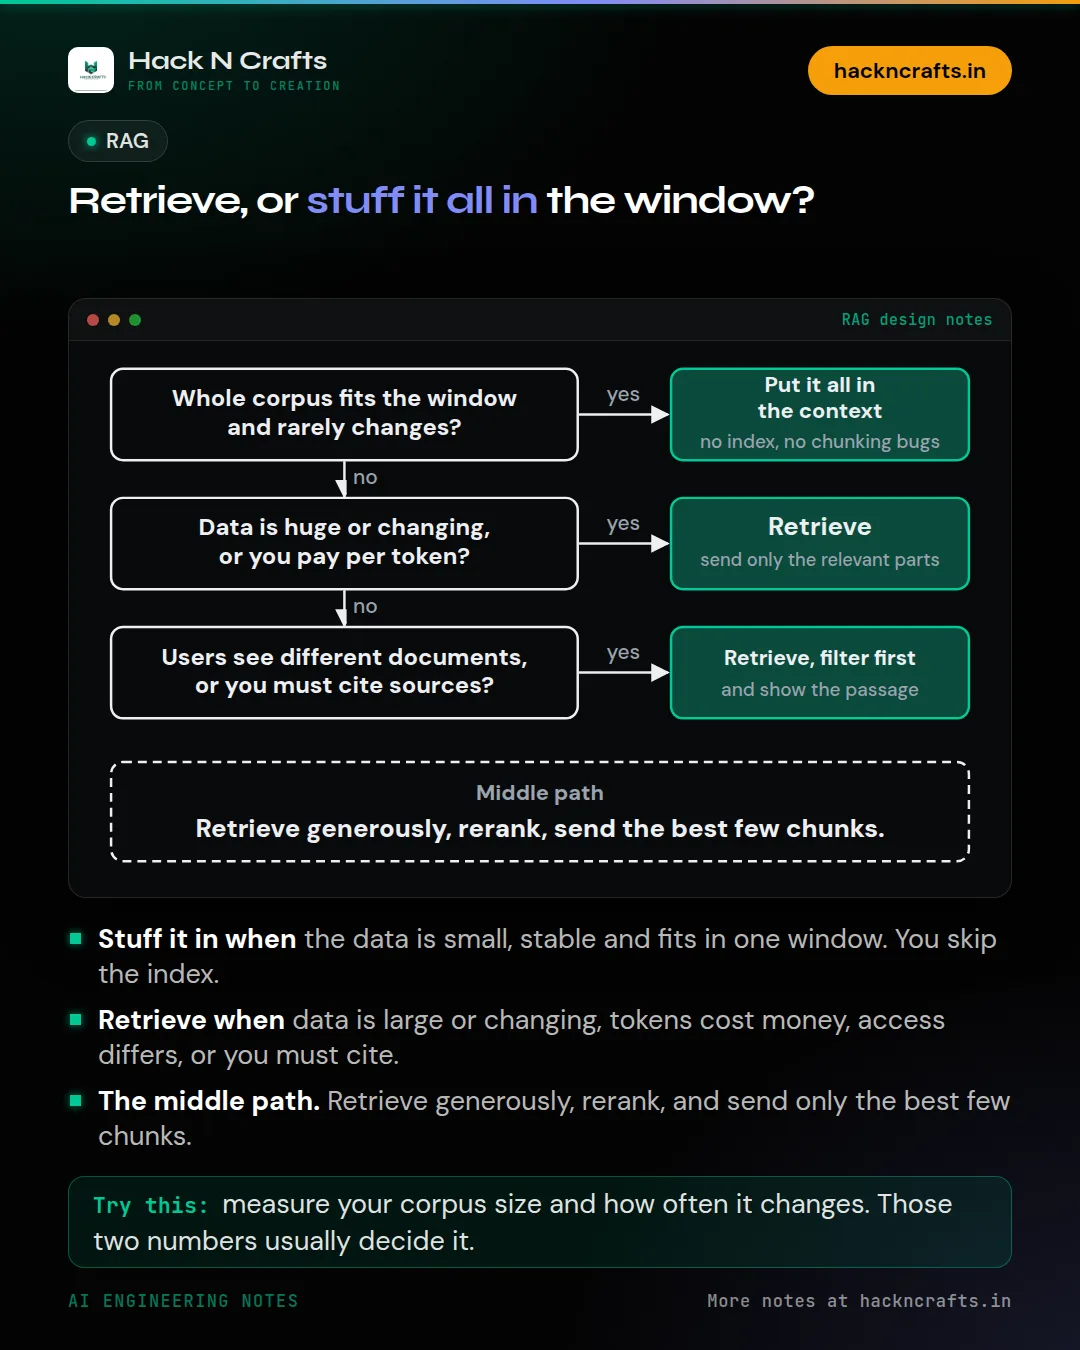
Retrieve, or stuff it all in the window?
Long context windows didn't kill RAG. They changed when you need it.
 AI Agents
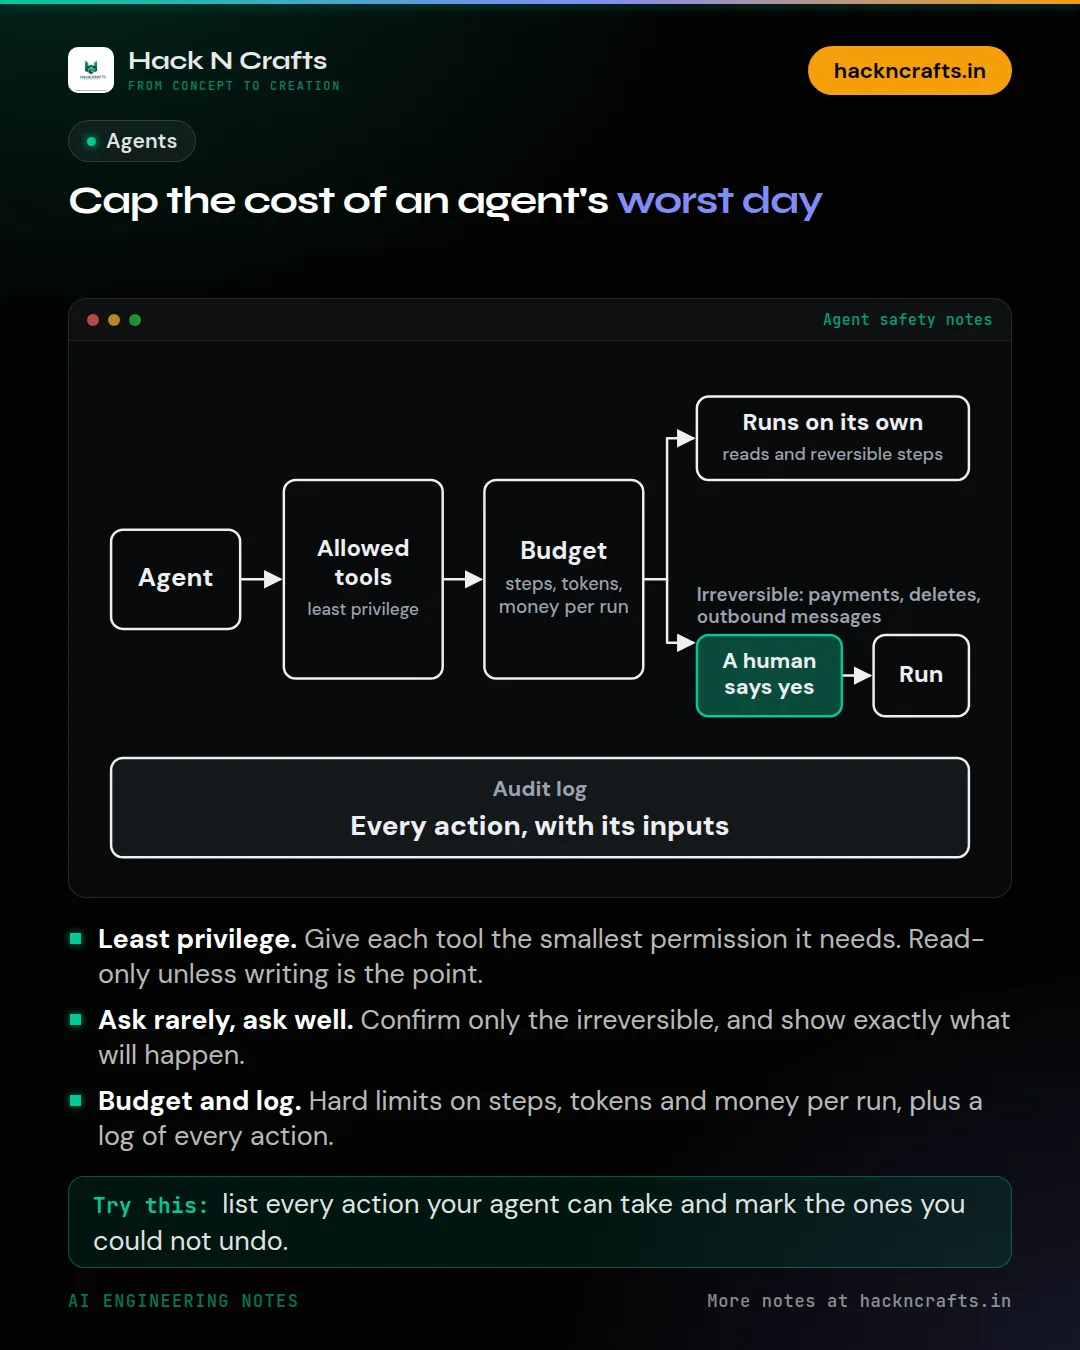
Cap the cost of an agent's worst day
Give an agent a tool that can spend money or delete data, and the question isn't whether it will make a mistake. It's what the mistake costs.
 Model Benchmarks
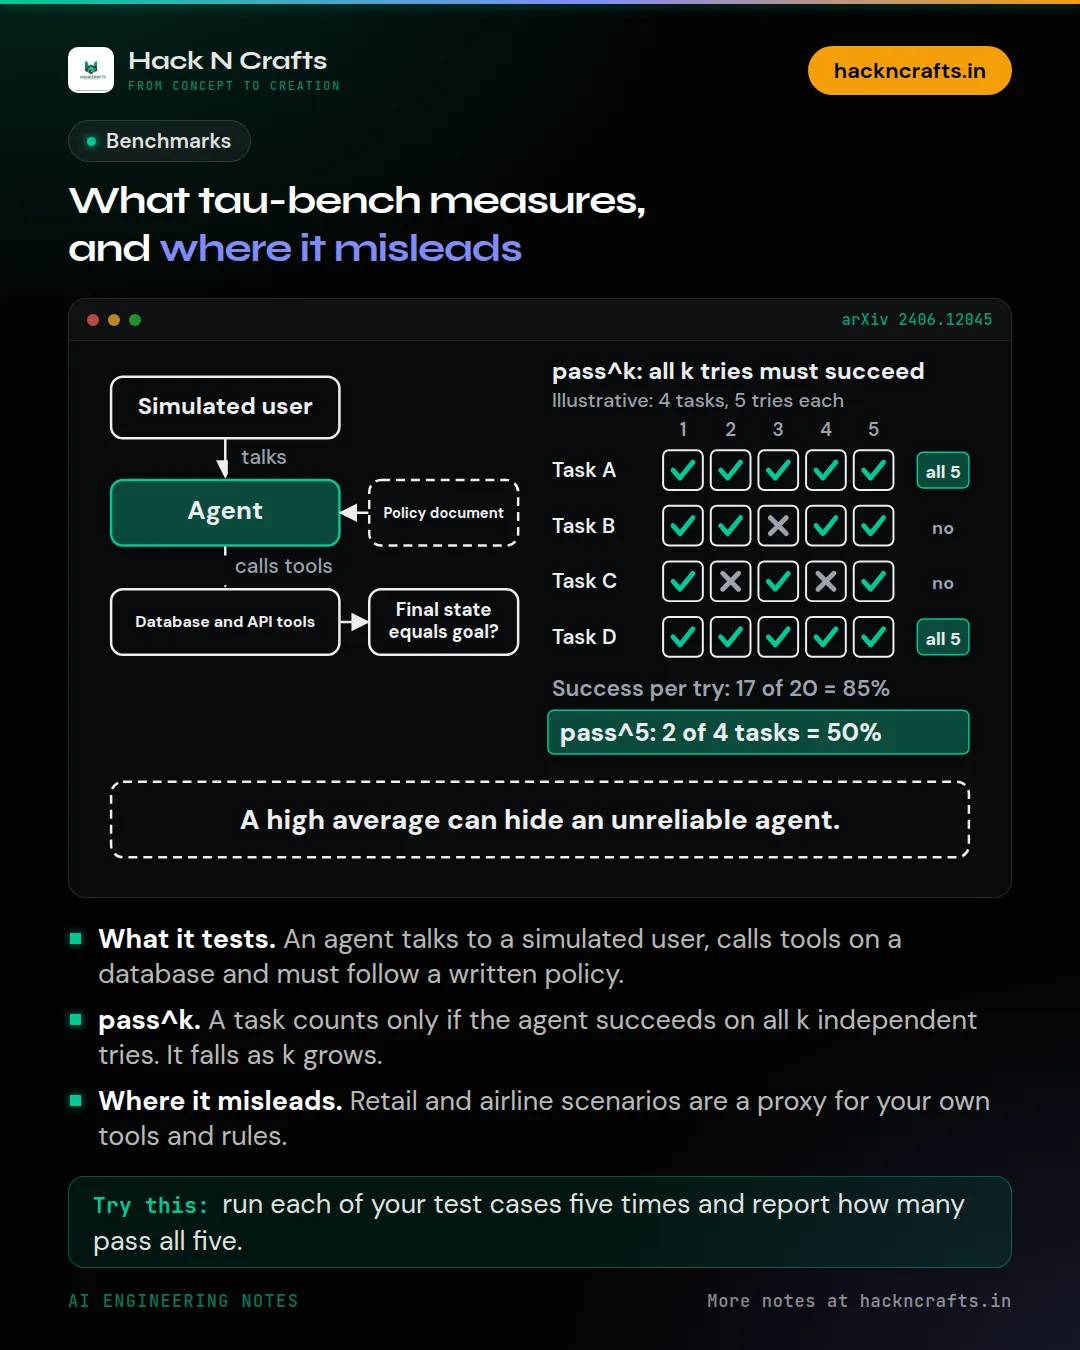
What tau-bench measures, and where it misleads
An agent that solves a task once is a demo. One that solves it every time is a product. tau-bench was built to measure that gap.
 AI News
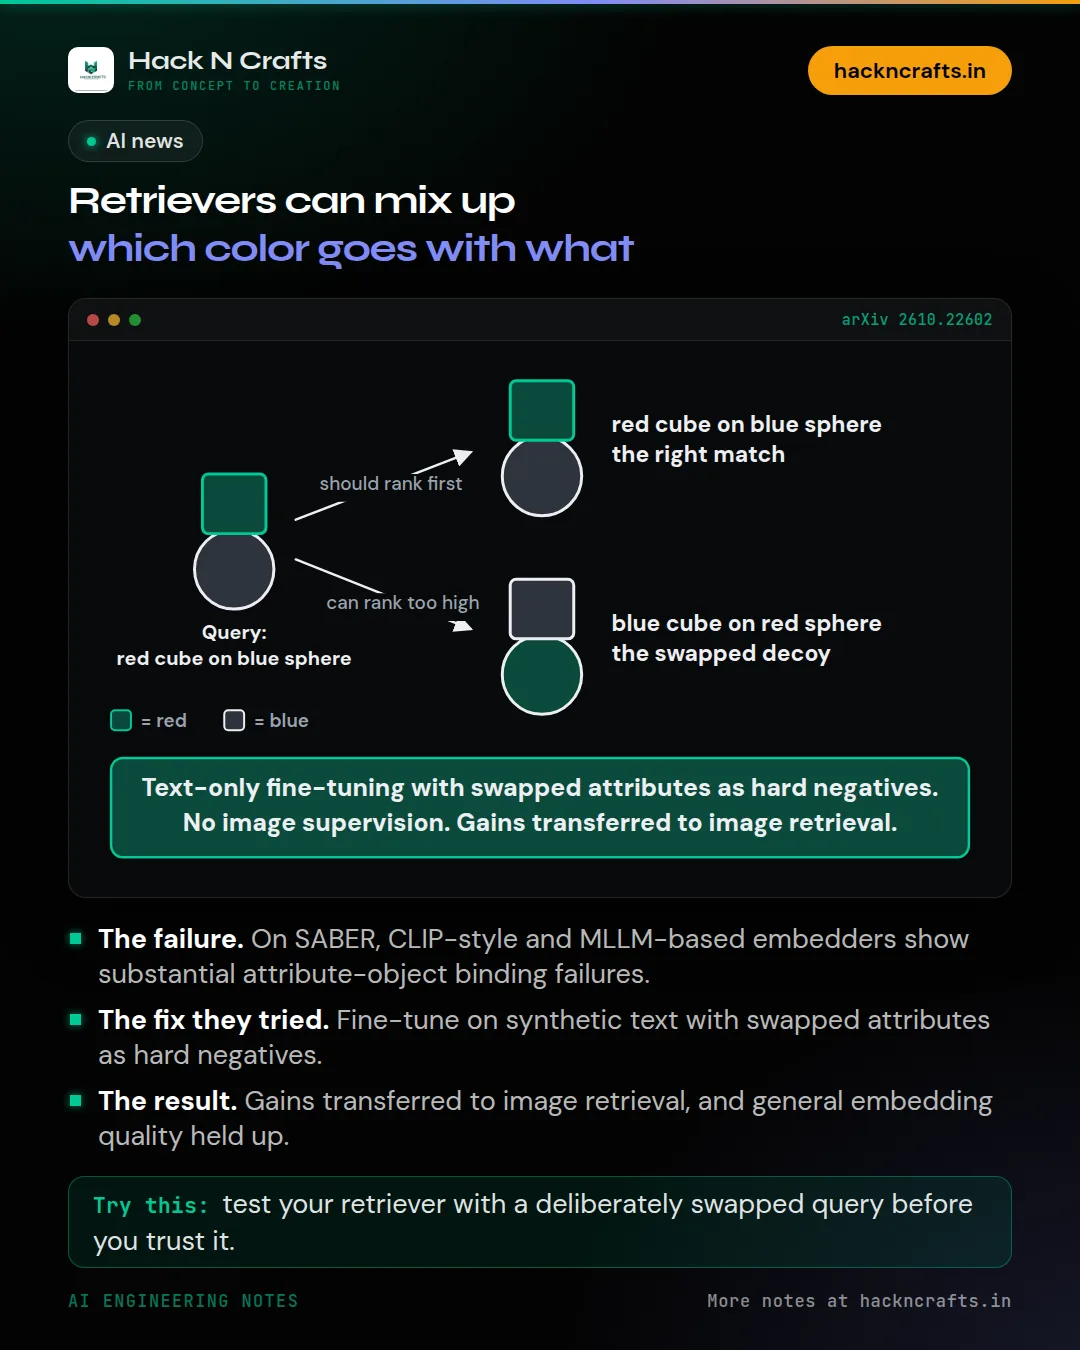
Retrievers can mix up which color goes with what
'A red cube on a blue sphere' and 'a blue cube on a red sphere' can look almost identical to a multimodal retriever.
 RAG
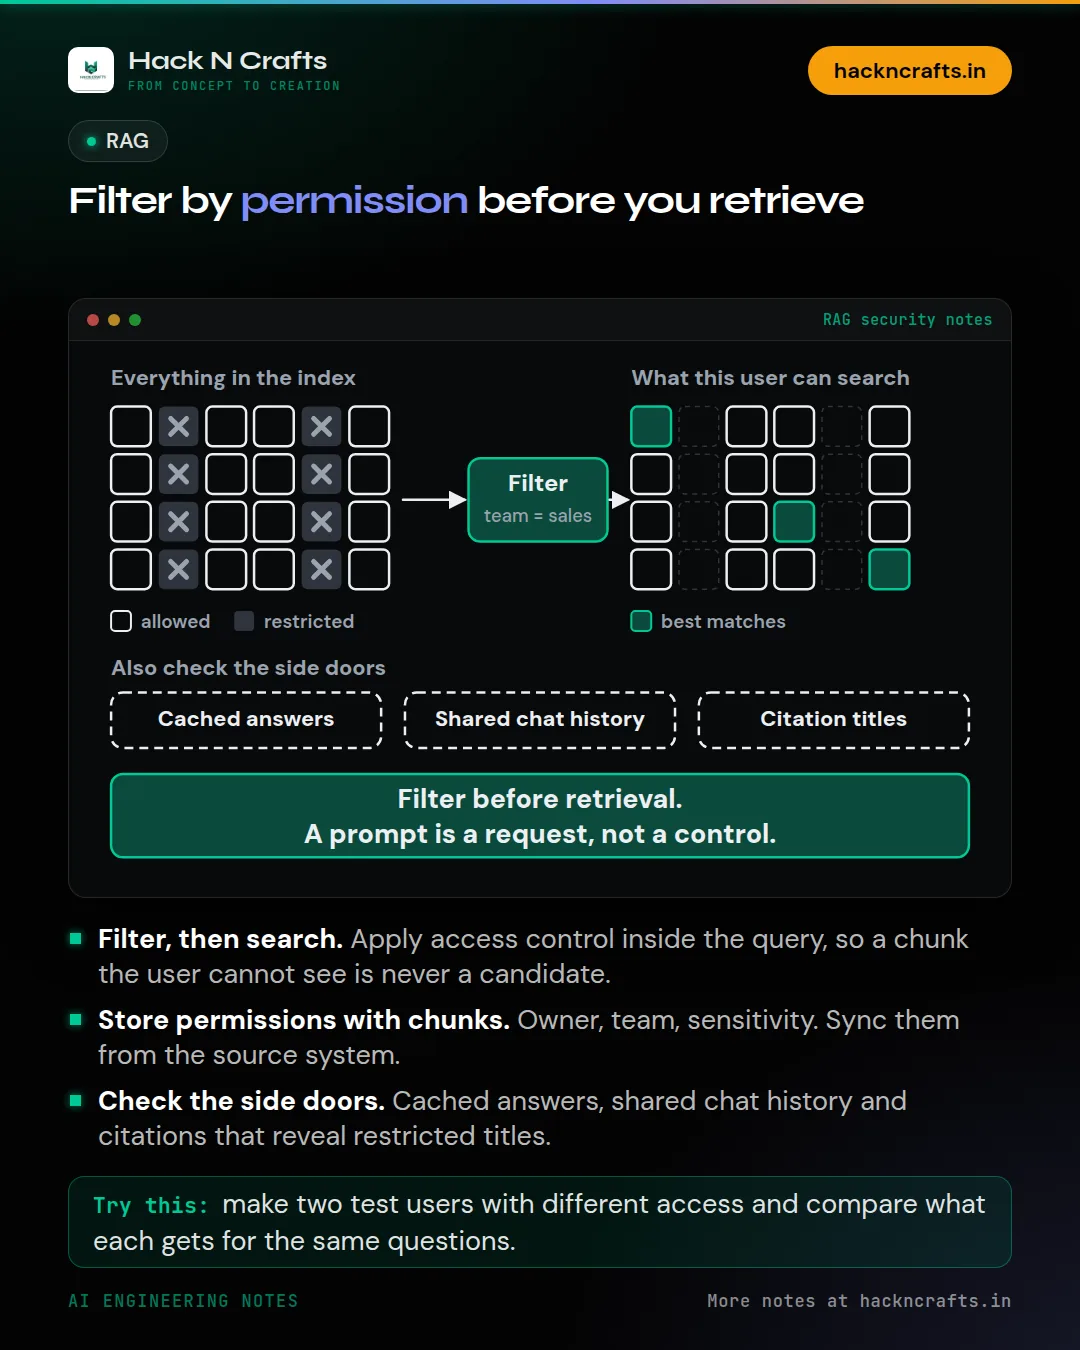
Filter by permission before you retrieve
The scariest RAG bug isn't a wrong answer. It's a right answer from a document the user was never allowed to see.
 GitHub Spotlight
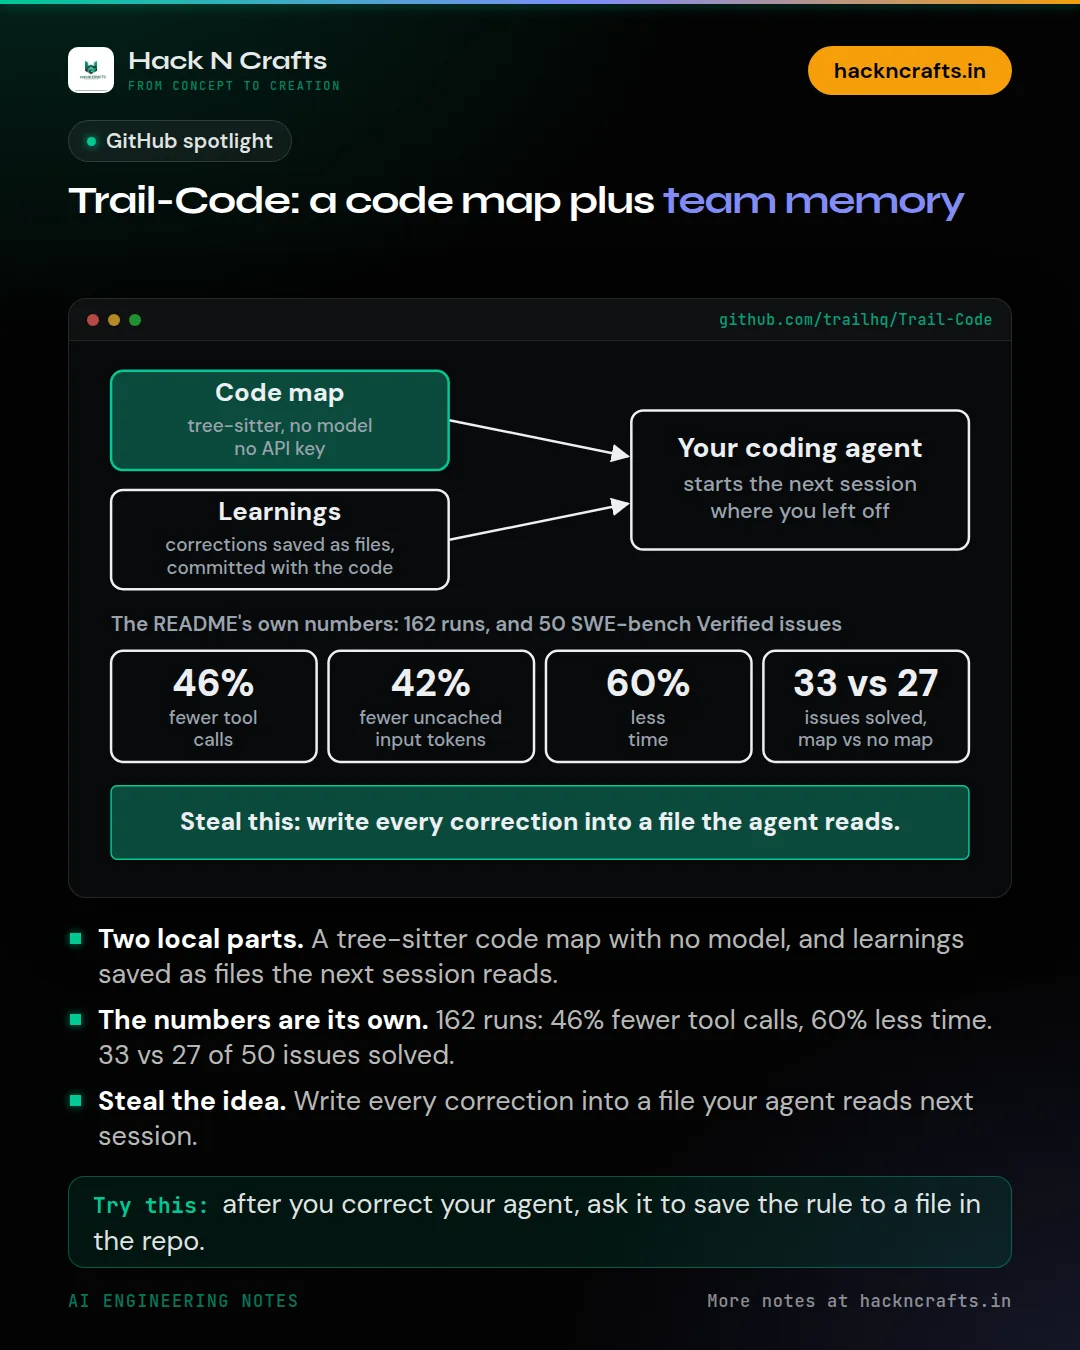
Trail-Code: a code map plus team memory
Trail-Code gives your coding agent a map of your repo, plus a memory of what your team has already decided.
 Model Benchmarks
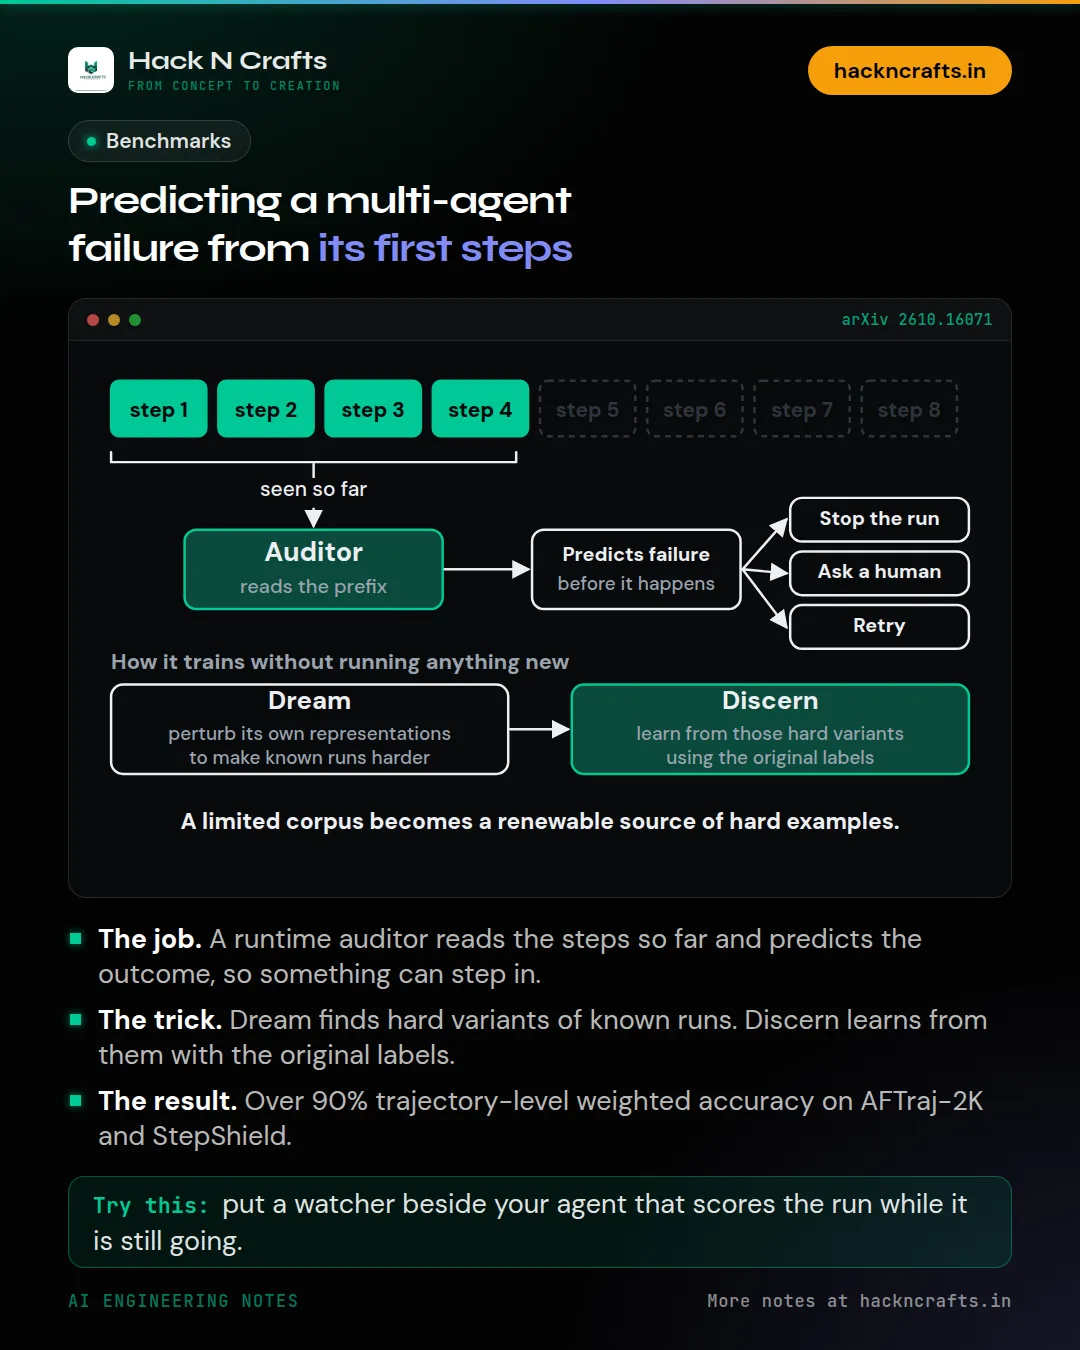
Predicting a multi-agent failure from its first steps
Can you tell, halfway through, that a multi-agent run is going to fail? A new paper says yes, with over 90% accuracy on two benchmarks.
 AI News
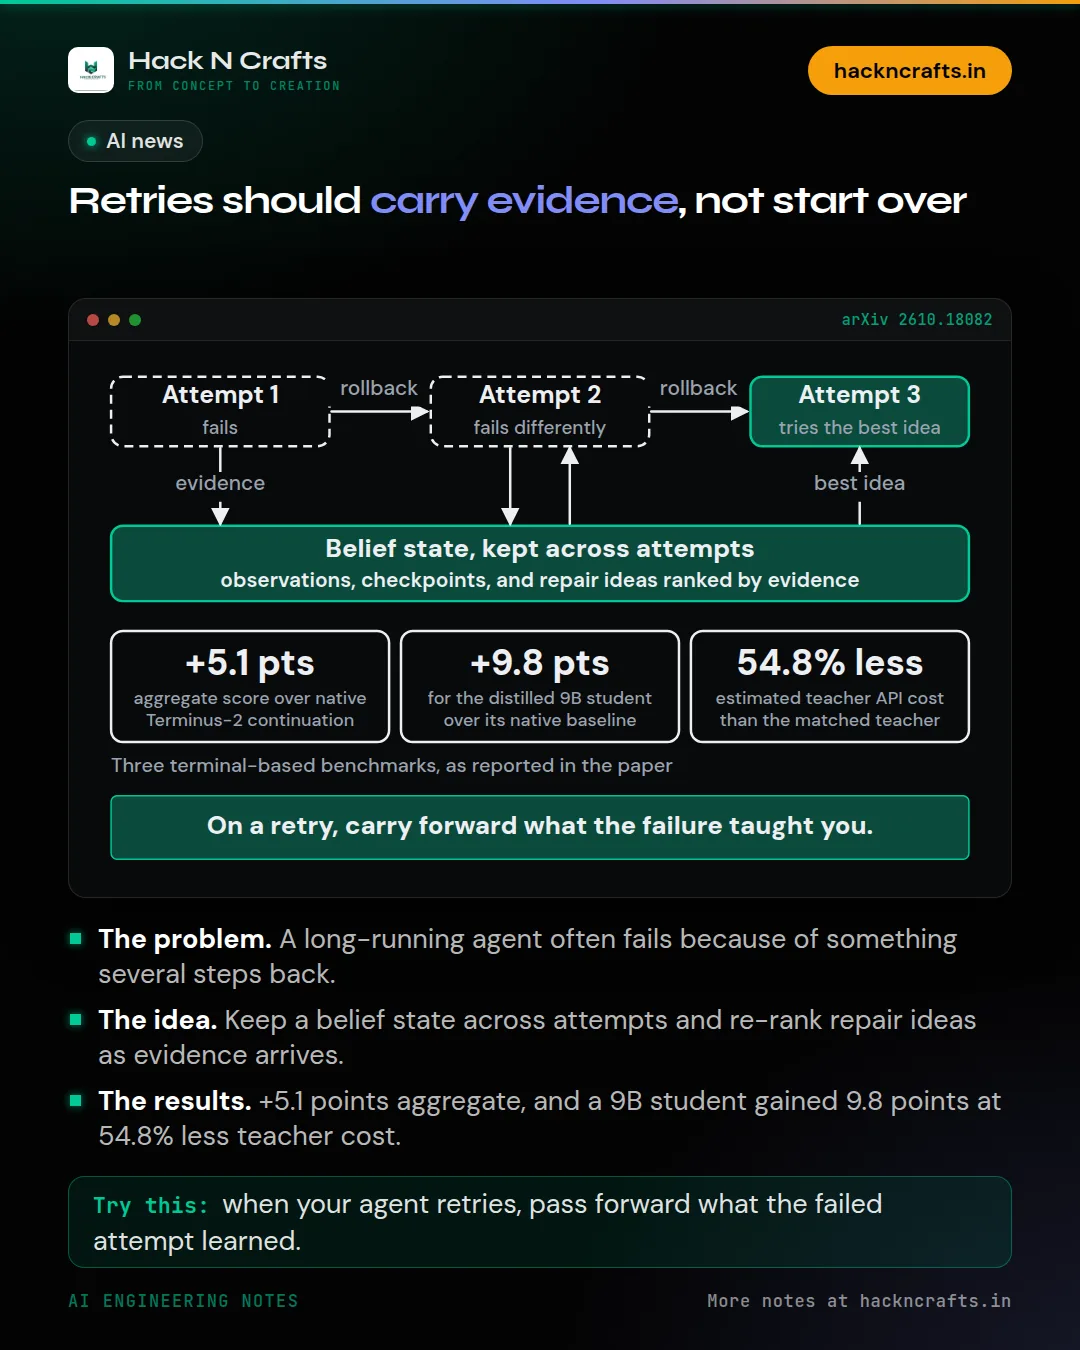
Retries should carry evidence, not start over
When a long-running agent fails, the cause is often several steps back. A new paper, BeliefWeaver, tries to fix that by remembering the evidence.
 RAG
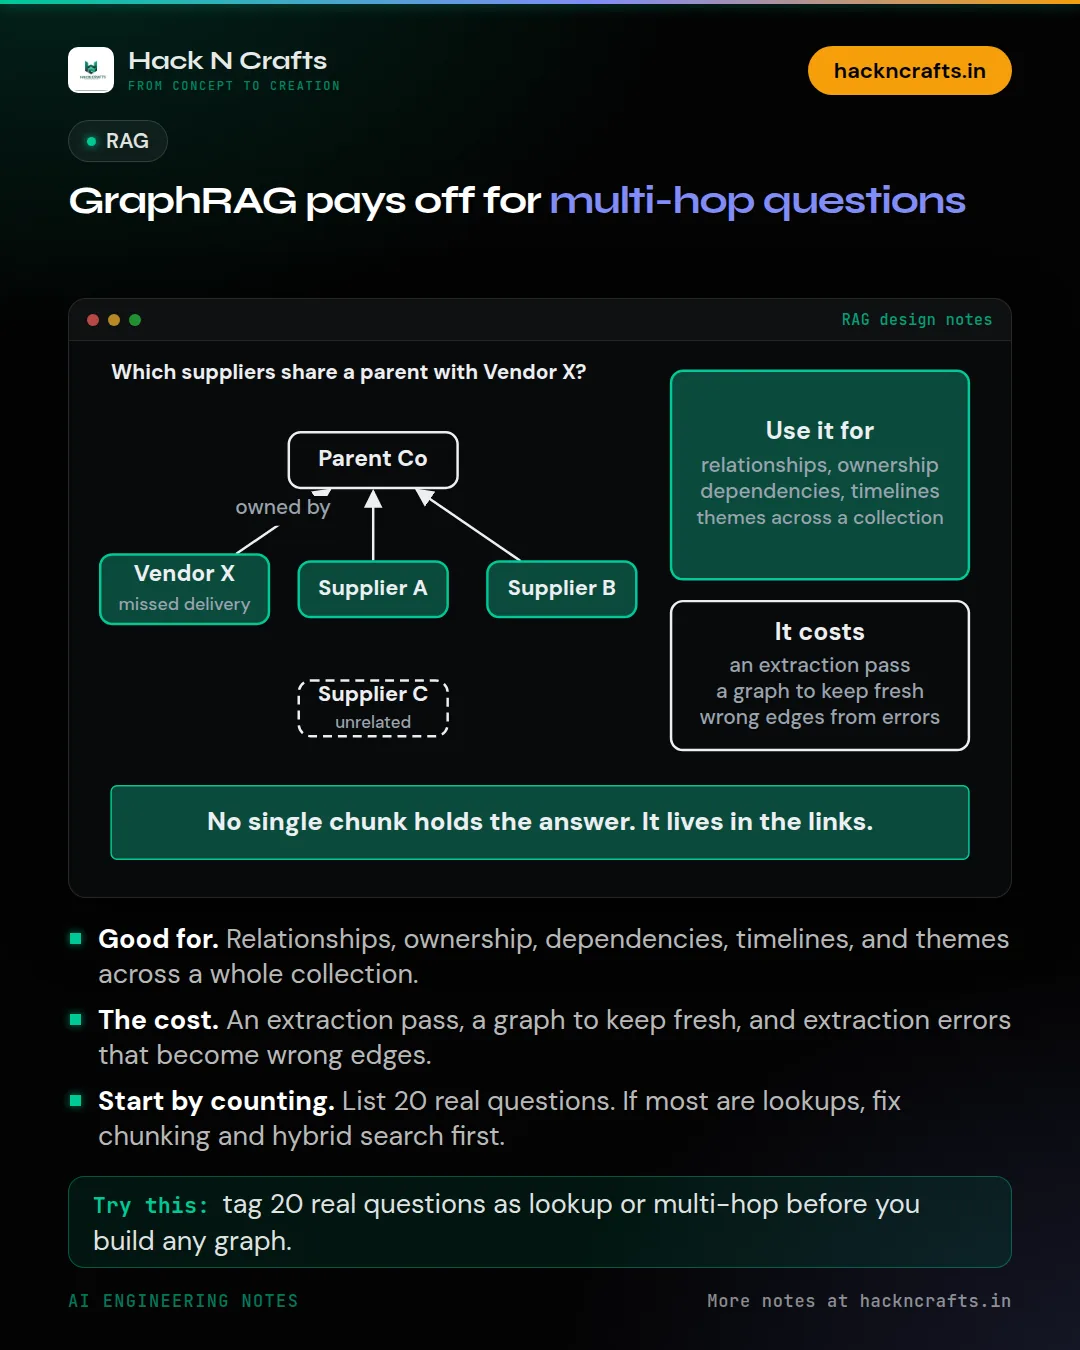
GraphRAG pays off for multi-hop questions
GraphRAG is worth the trouble when your questions are about how things connect, not what a passage says.
 AI Agents
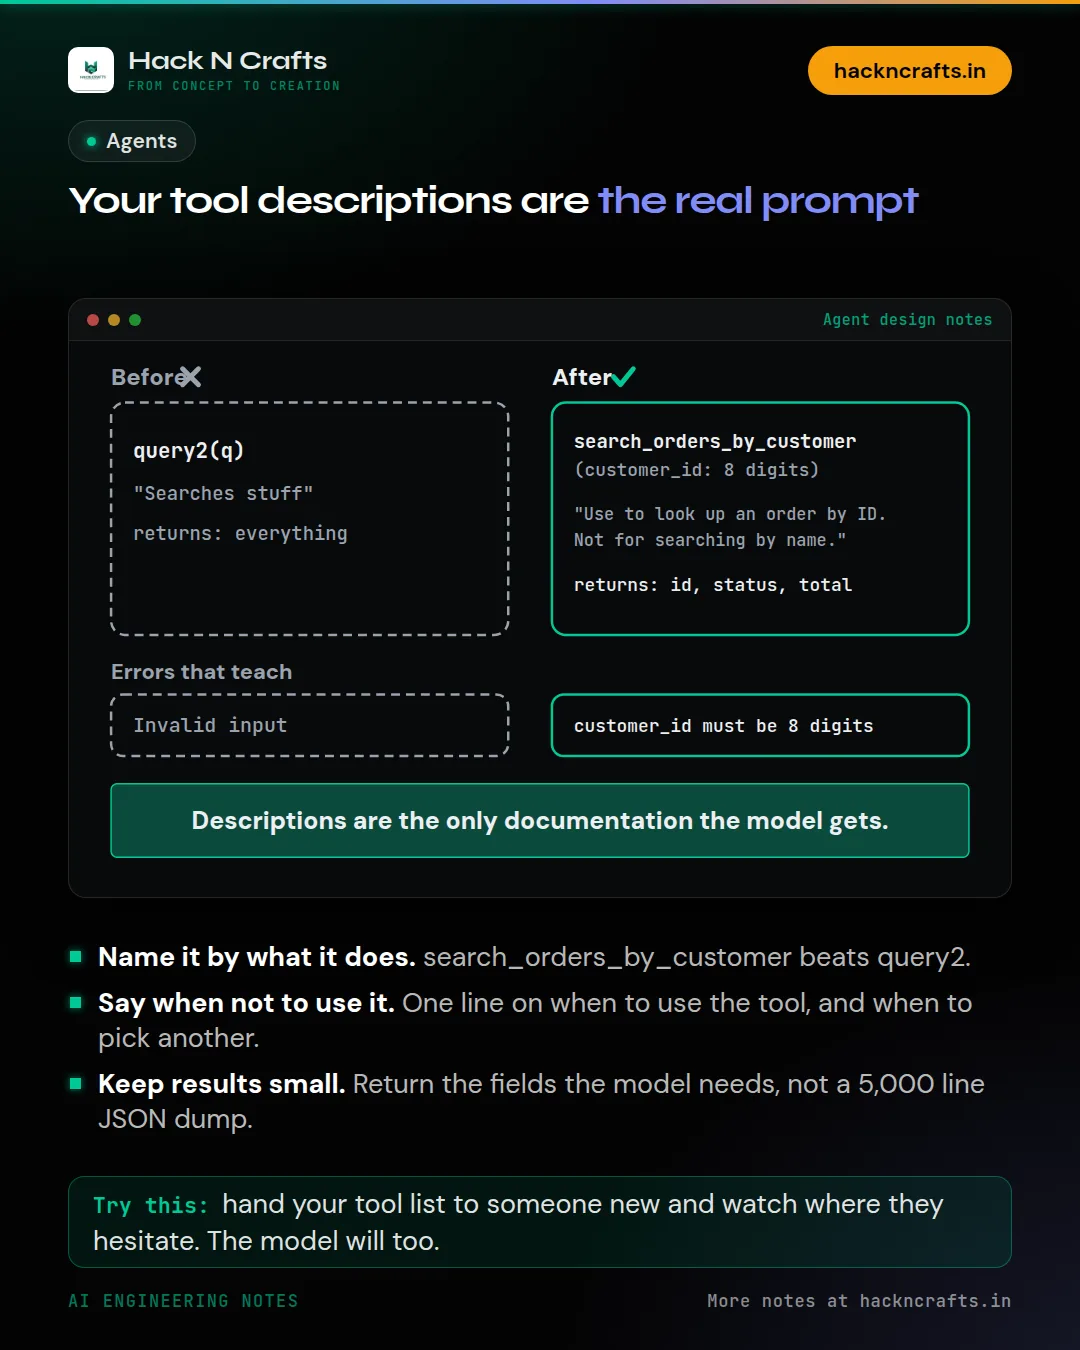
Your tool descriptions are the real prompt
Many agent failures trace back to the tool, not the model. The tool was described in a way the model couldn't use correctly.
 Model Benchmarks
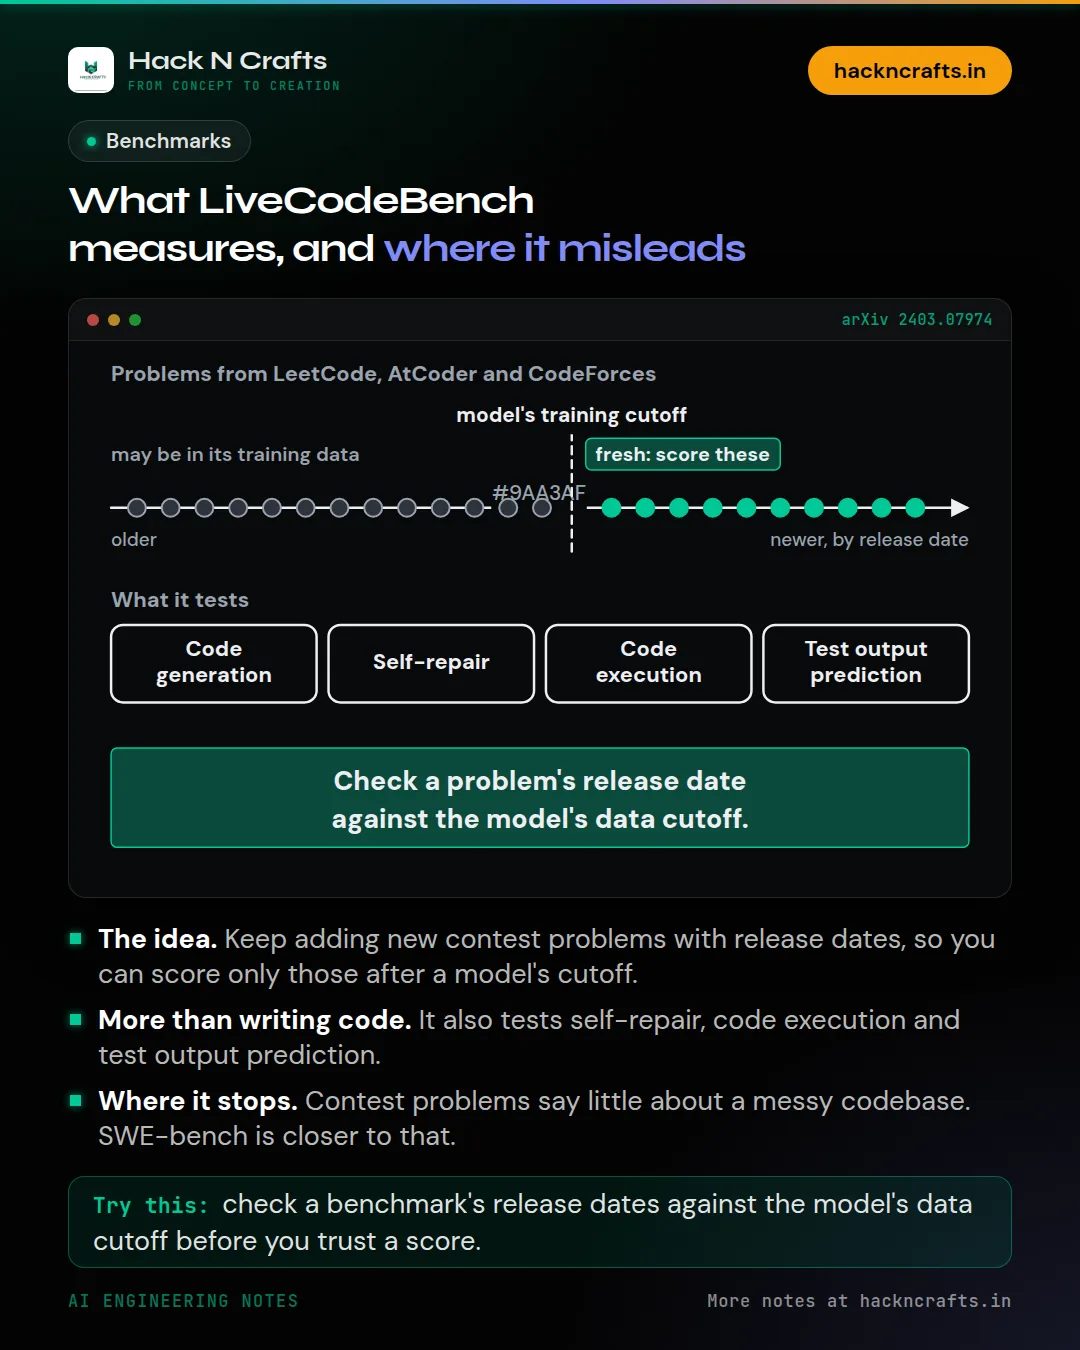
What LiveCodeBench measures, and where it misleads
Models that ace old coding benchmarks may have seen the answers. LiveCodeBench was built to make that harder.
 AI News
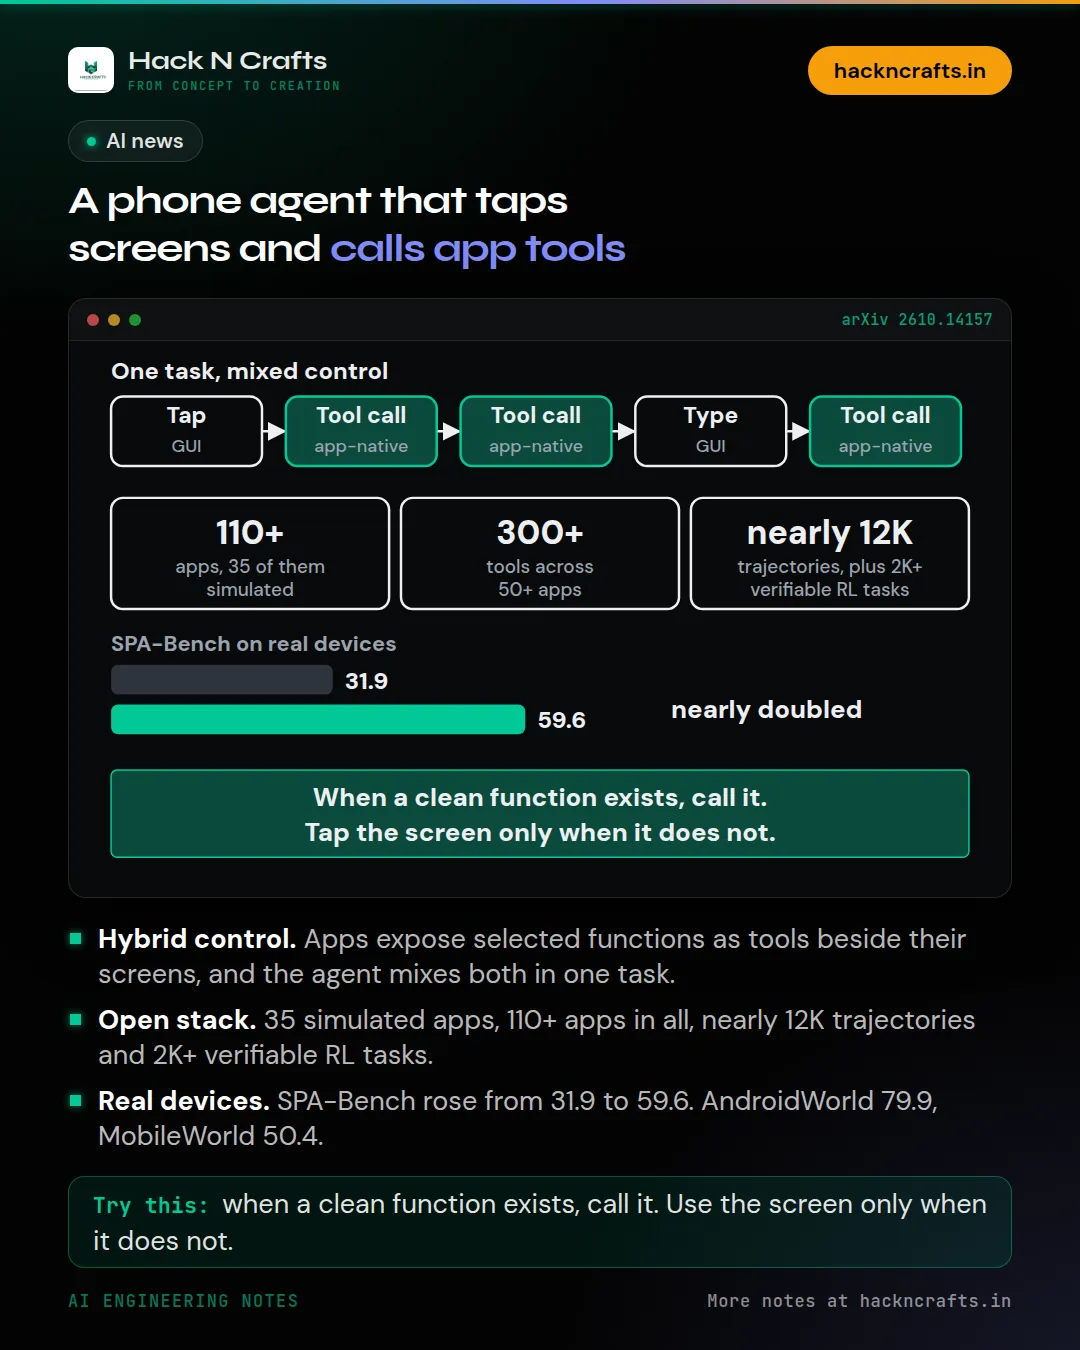
A phone agent that taps screens and calls app tools
An open mobile agent nearly doubled its real-device score, and part of the trick was letting apps expose tools as well as screens.
 RAG
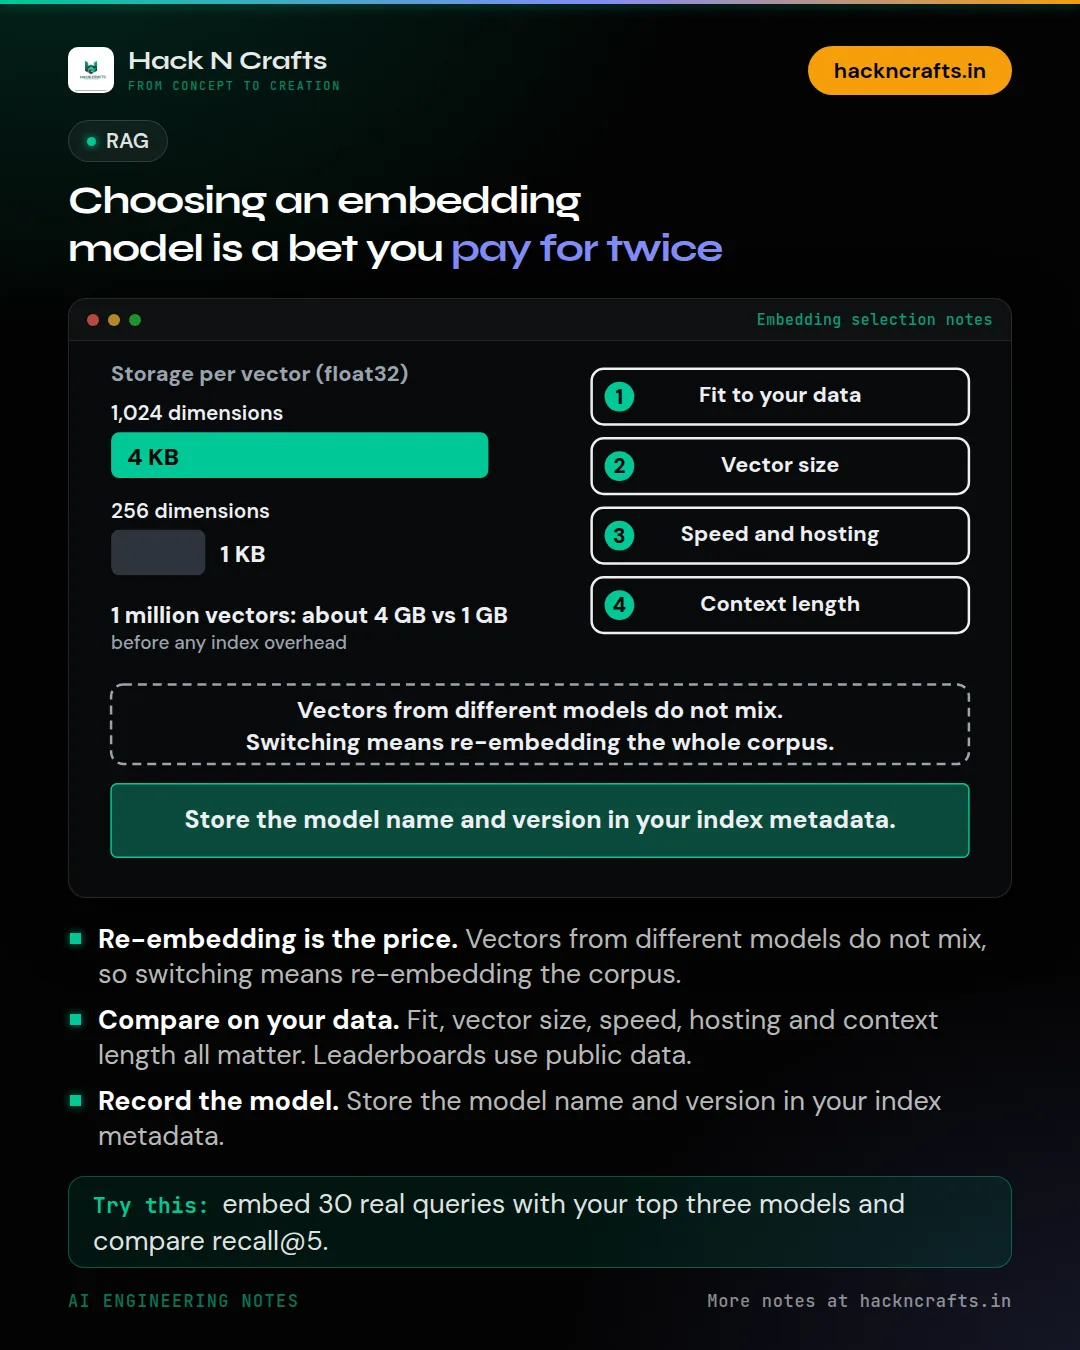
Choosing an embedding model is a bet you pay for twice
Choosing an embedding model is a bet you pay for twice: when you index, and again when you change your mind.
 GitHub Spotlight
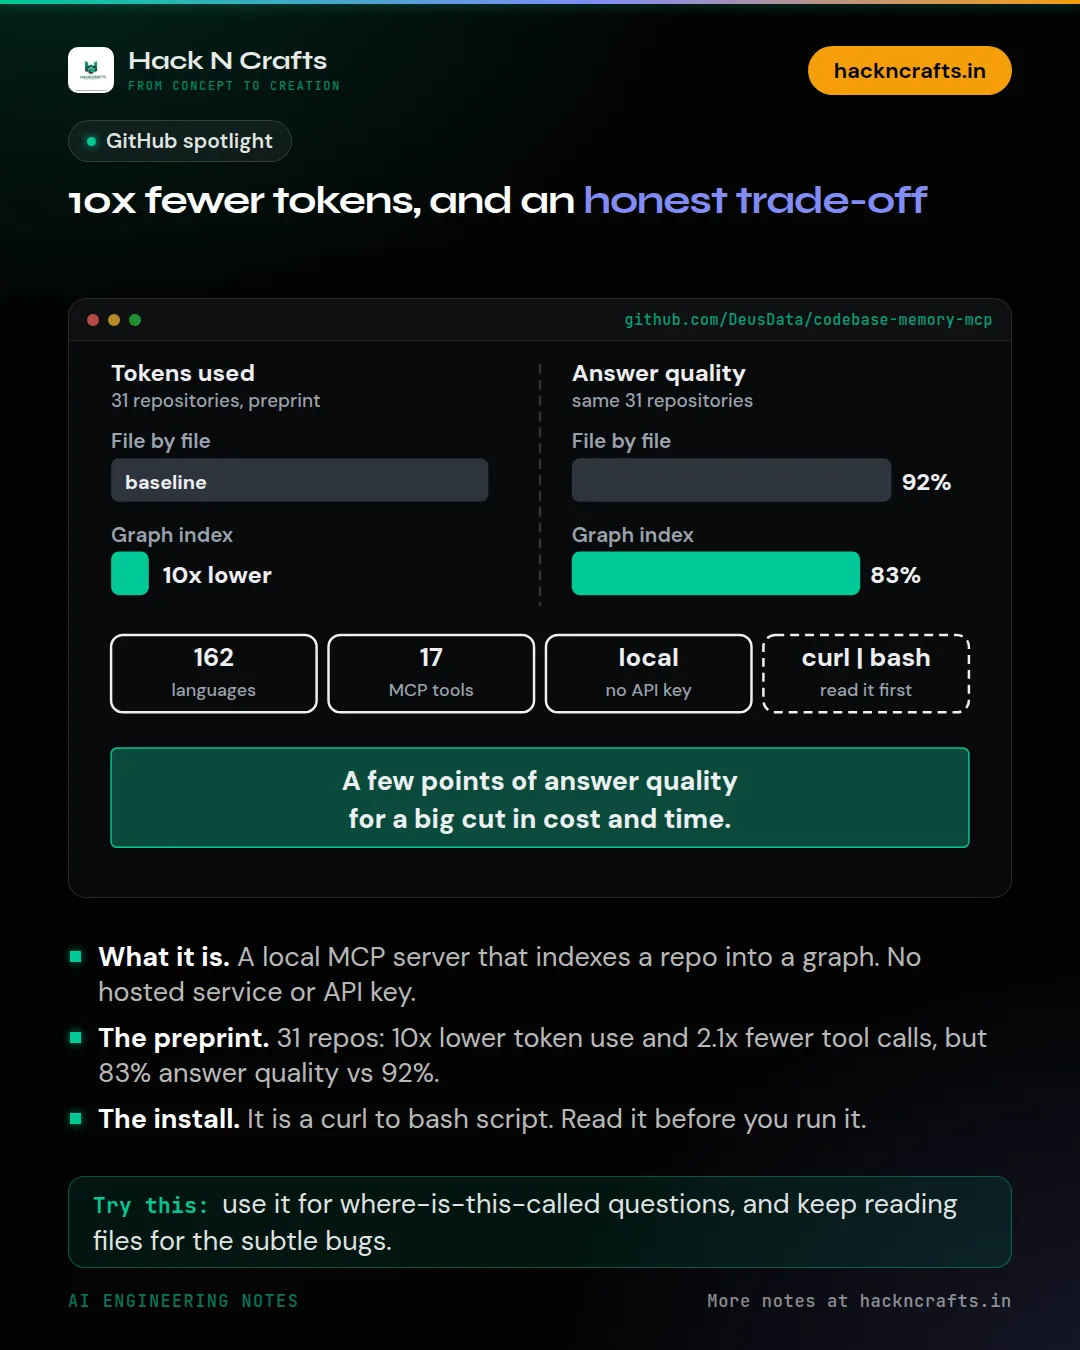
10x fewer tokens, and an honest trade-off
One MCP server claims 10x fewer tokens on code questions. Its own preprint also admits the answers were a bit worse. I like that it says so.
 Model Benchmarks
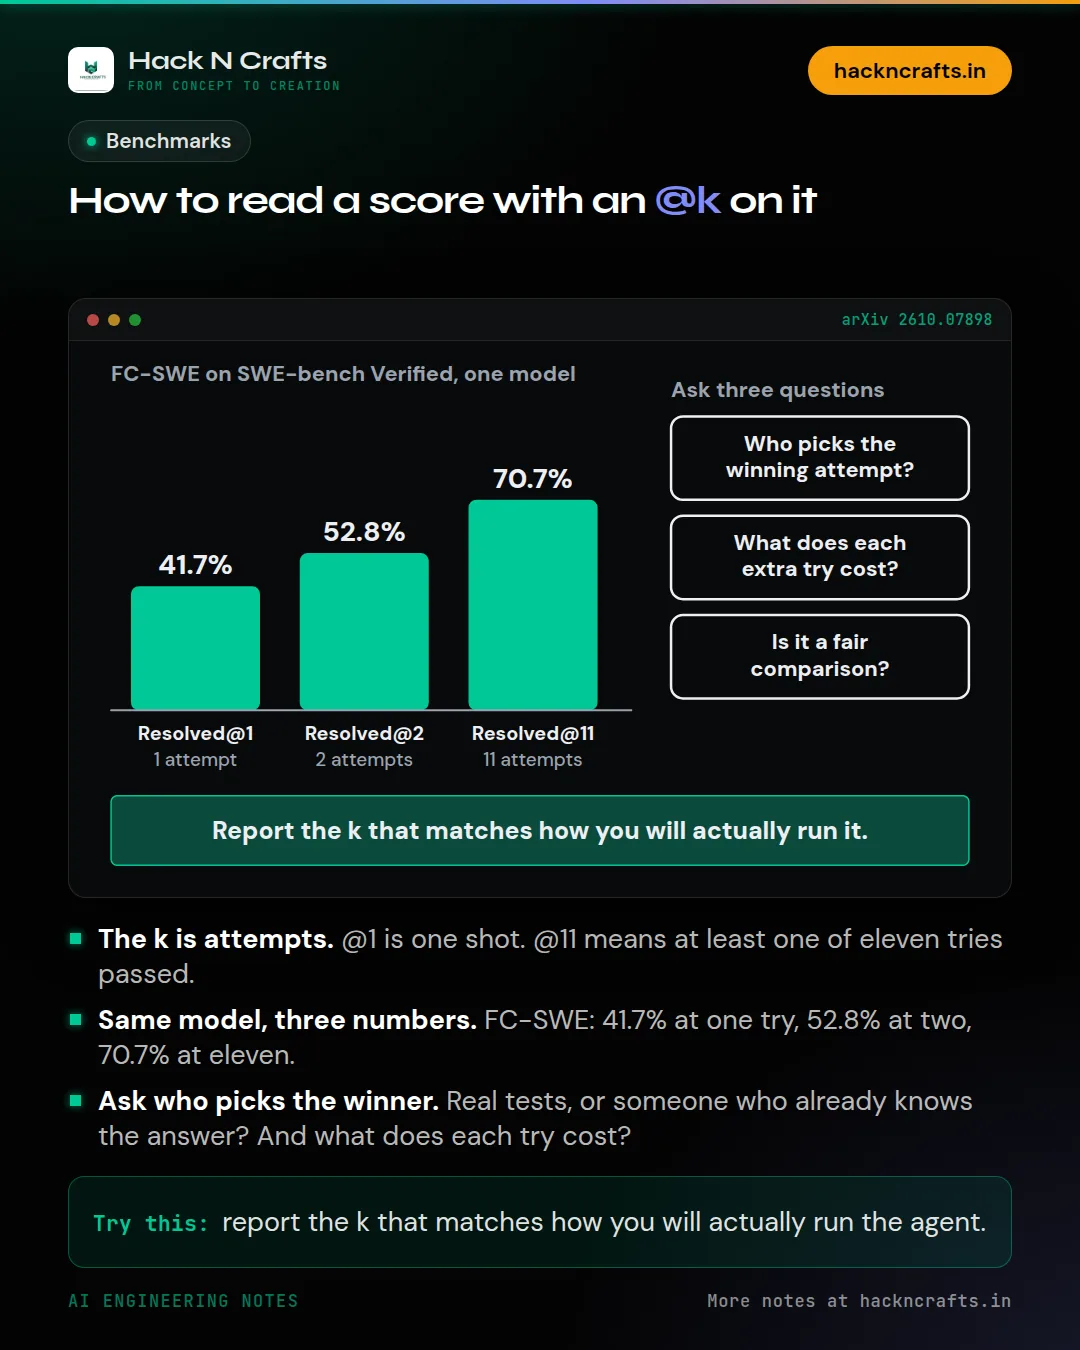
How to read a score with an @k on it
'Resolved@11: 70.7%' and 'Resolved@1: 41.7%' come from the same model. A score with an @k on the end needs reading carefully.
 AI News
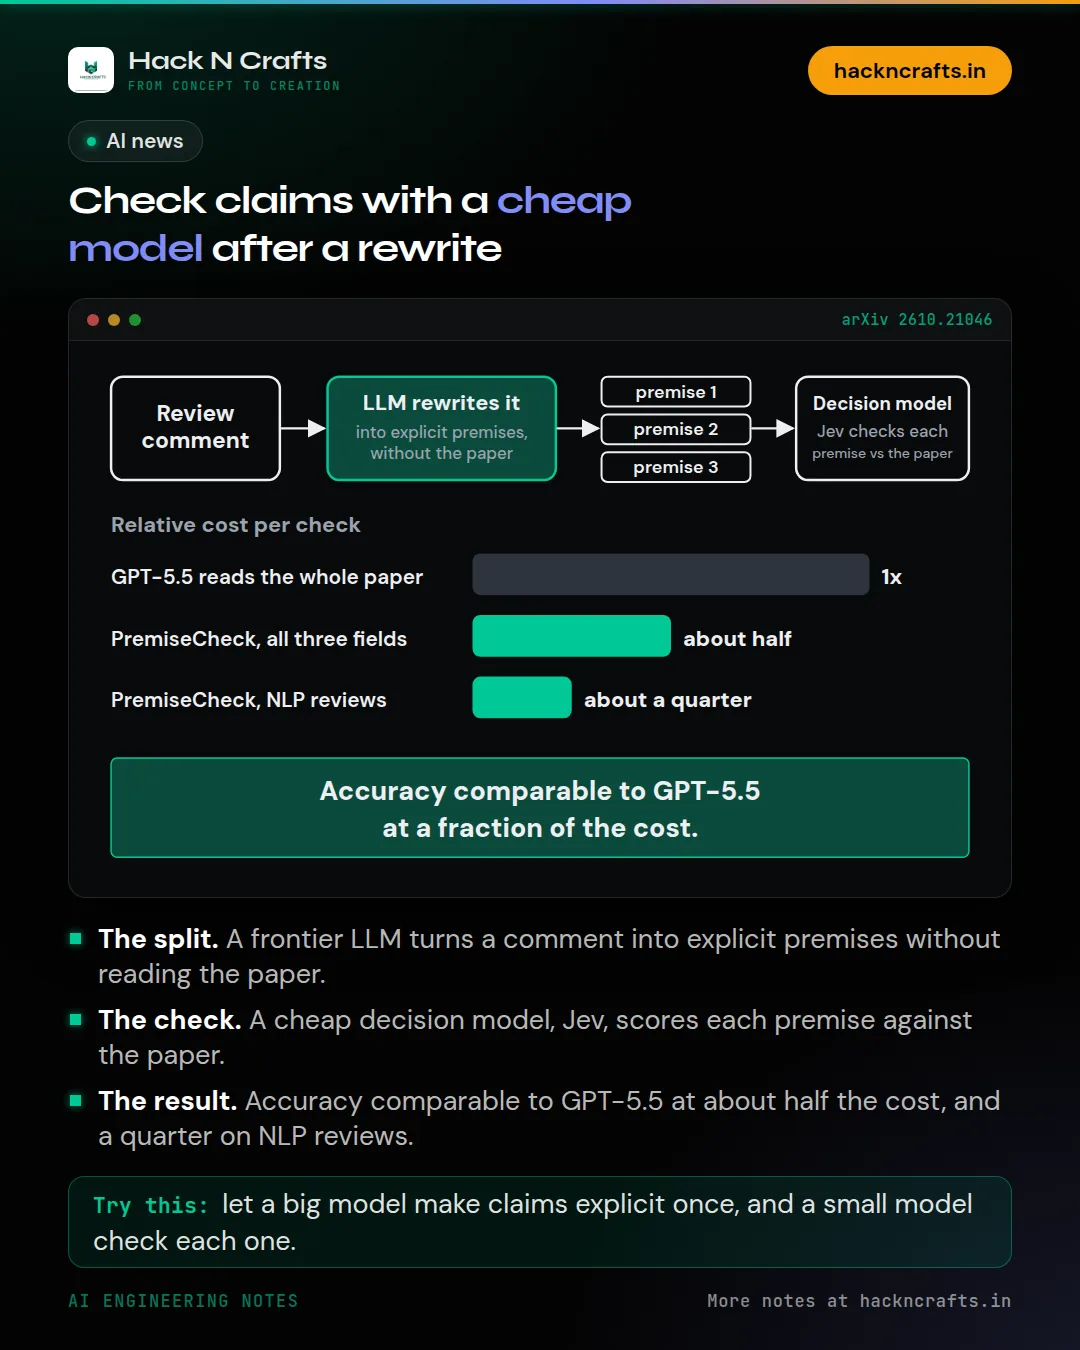
Check claims with a cheap model after a rewrite
Checking claims against a source doesn't have to use the biggest model. A new paper got close to a frontier model's accuracy for about half the cost.
 RAG
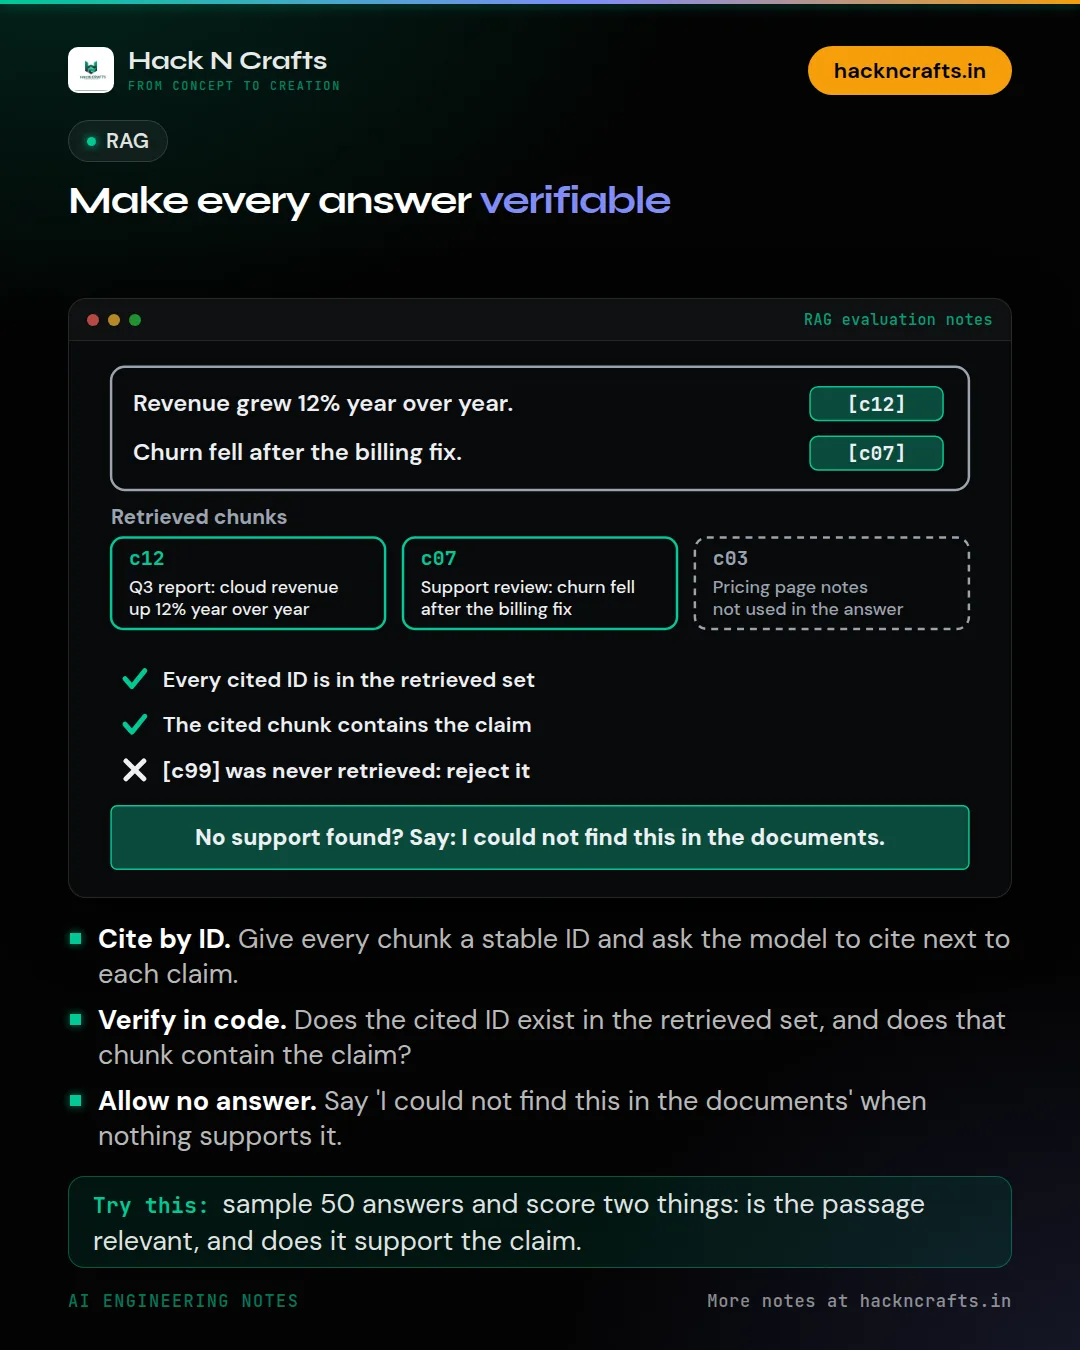
Make every answer verifiable
A RAG answer without citations is a claim. One with checkable citations is evidence.
 GitHub Spotlight
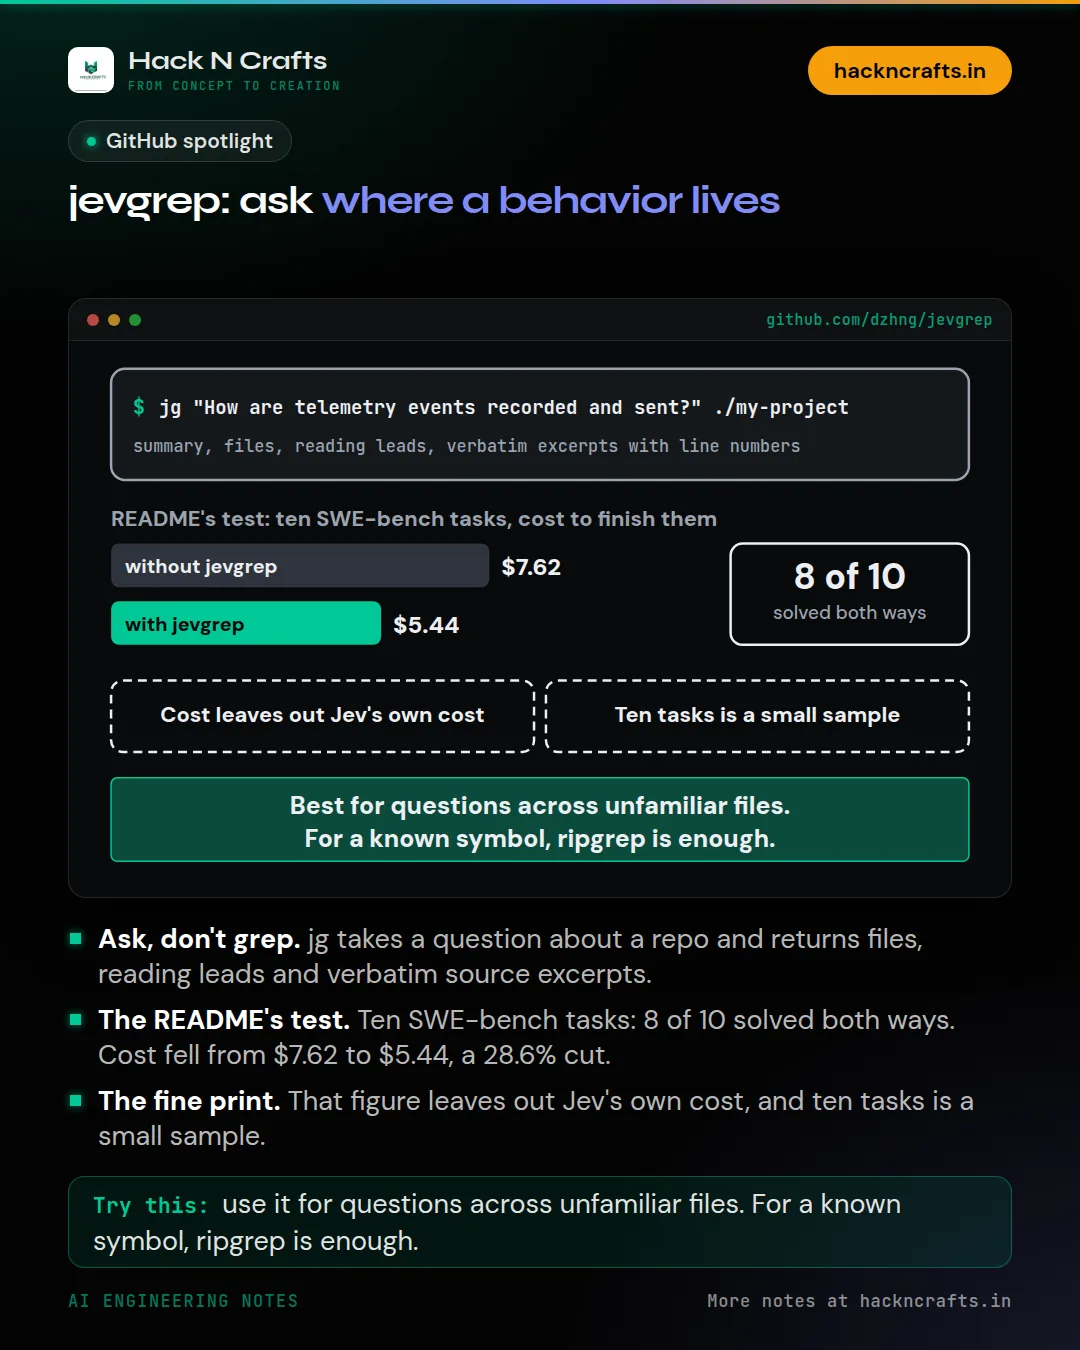
jevgrep: ask where a behavior lives
jevgrep lets your coding agent ask 'where does this behavior live?' and get back relevant source, with a claim of about 30% lower cost.
 Model Benchmarks
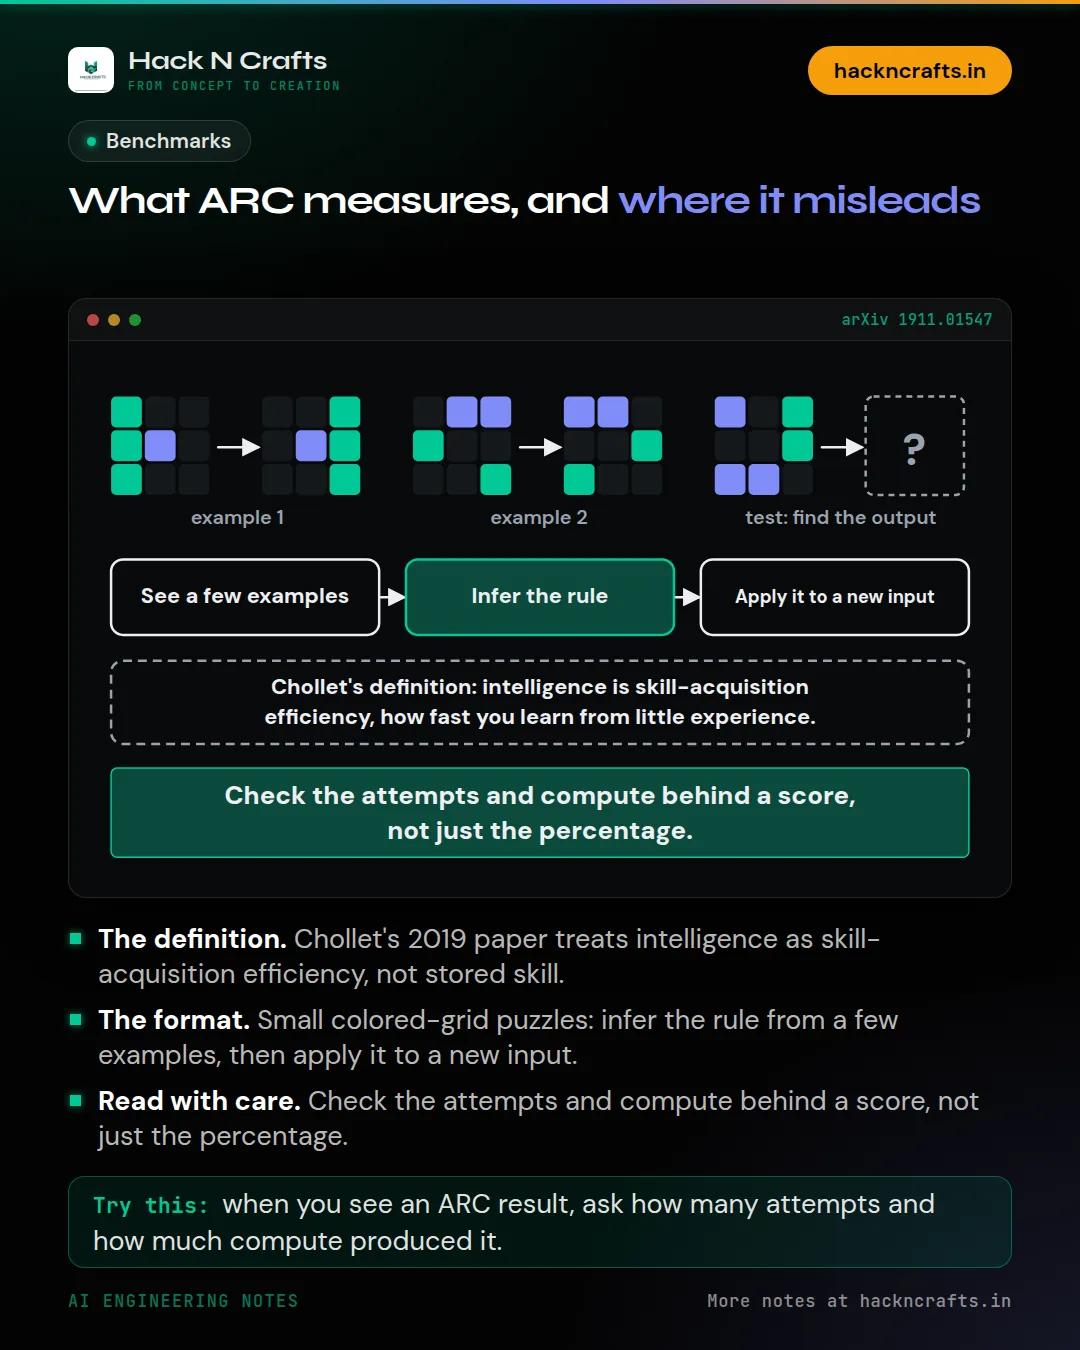
What ARC measures, and where it misleads
Most benchmarks test what a model already knows. ARC tests how quickly it can learn something it has never seen.
 AI News
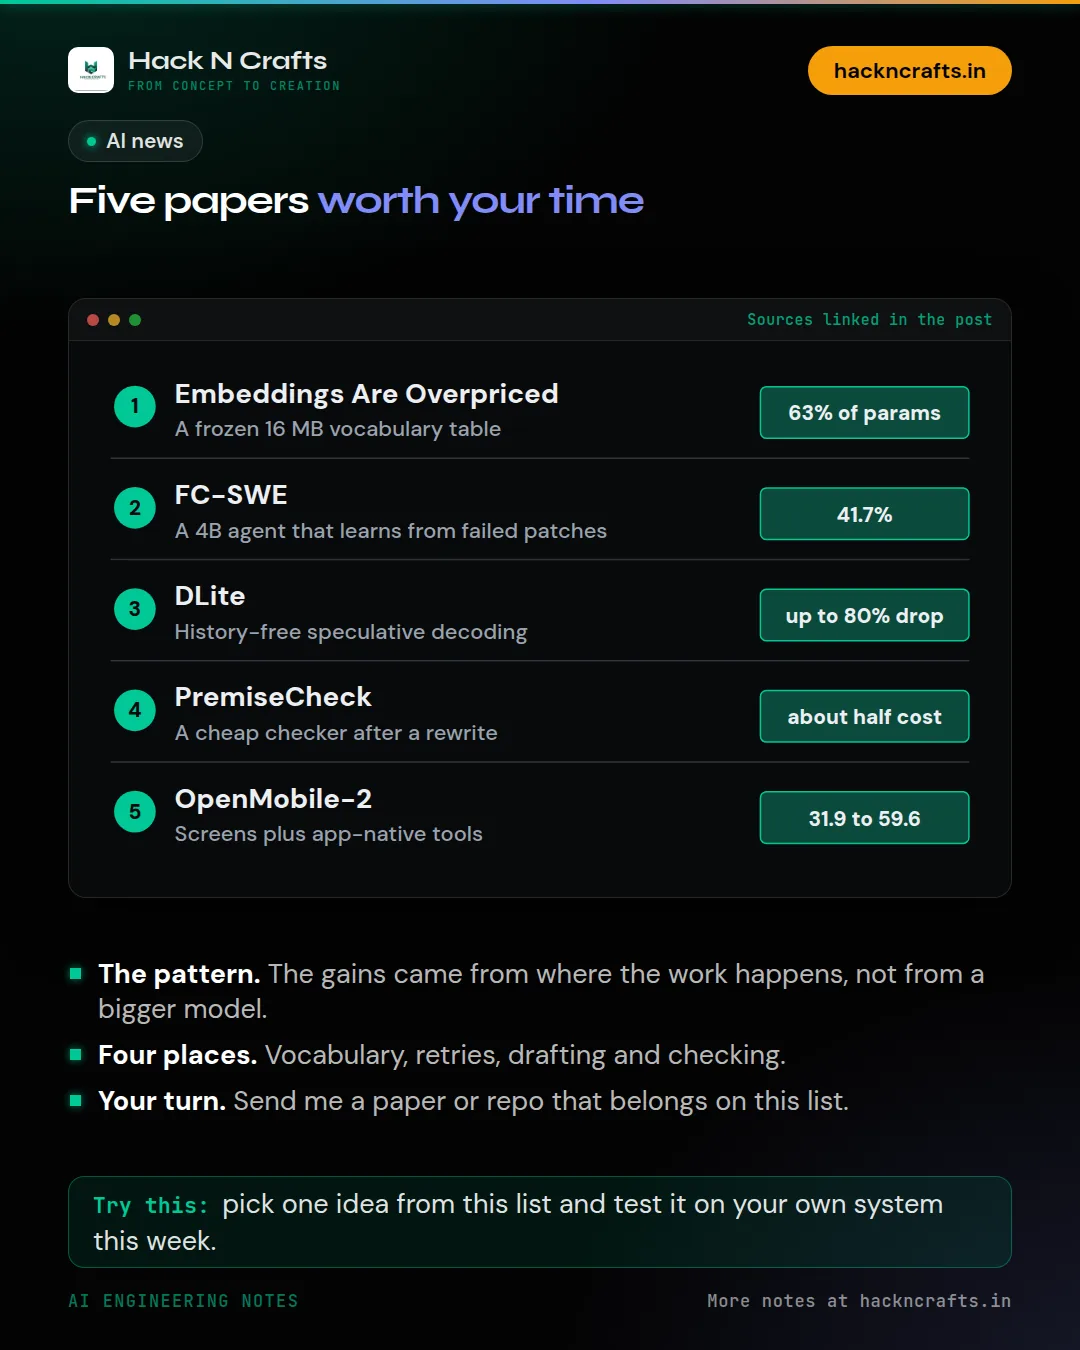
Five papers worth your time
Five papers from last week that are worth your time, each with a source.
 RAG
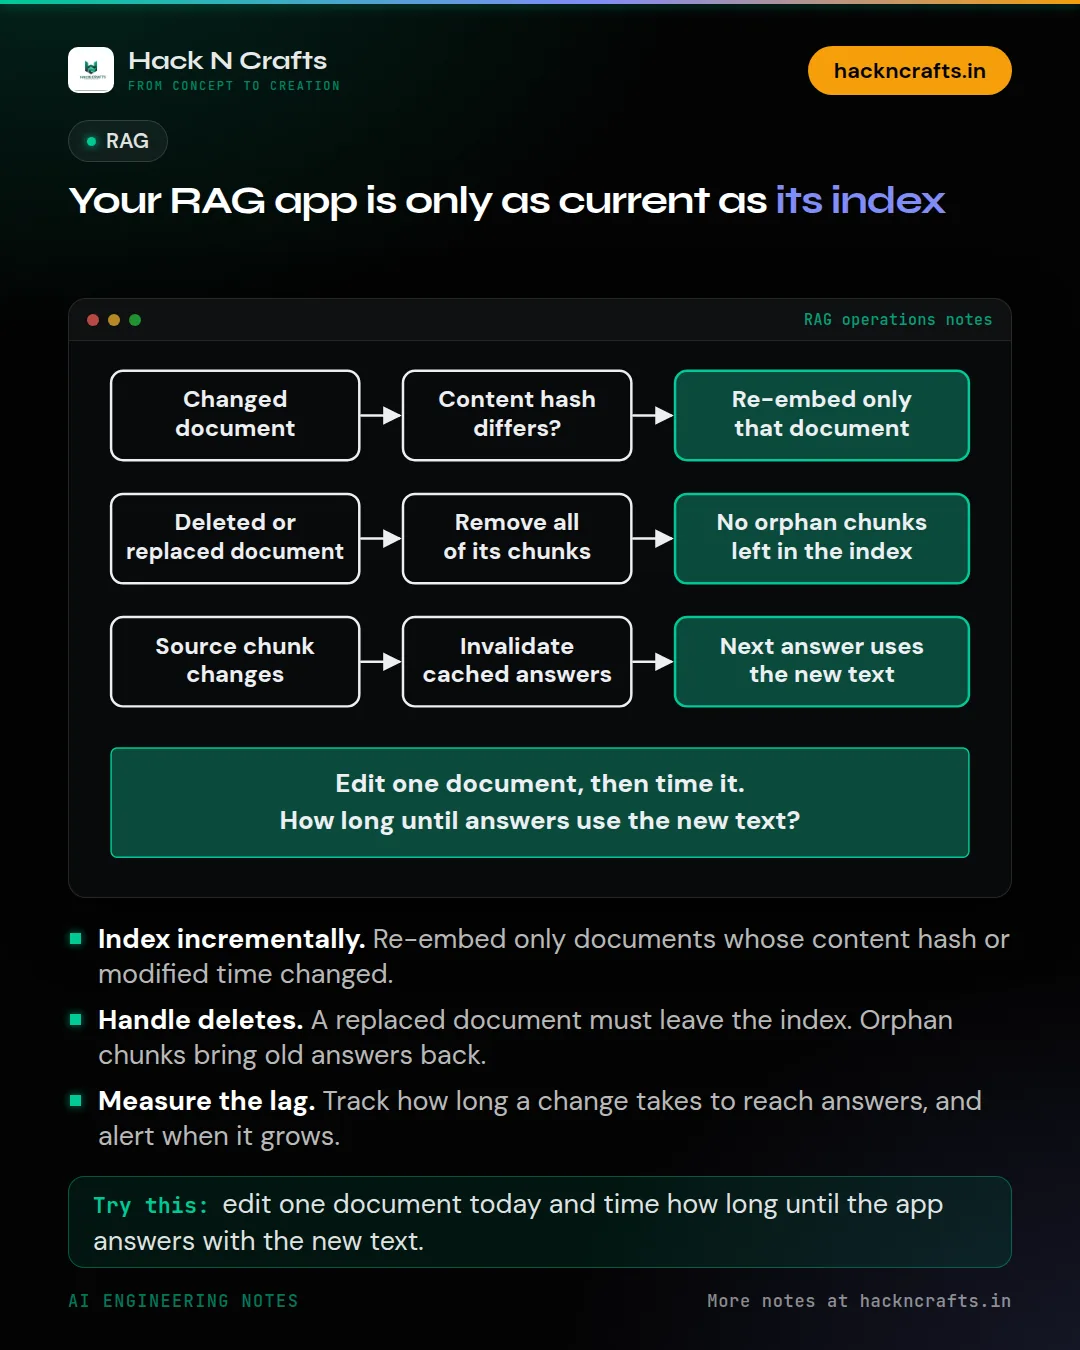
Your RAG app is only as current as its index
Your RAG app is only as current as your index. Most teams find out when a customer quotes a policy that was replaced months ago.
 GitHub Spotlight
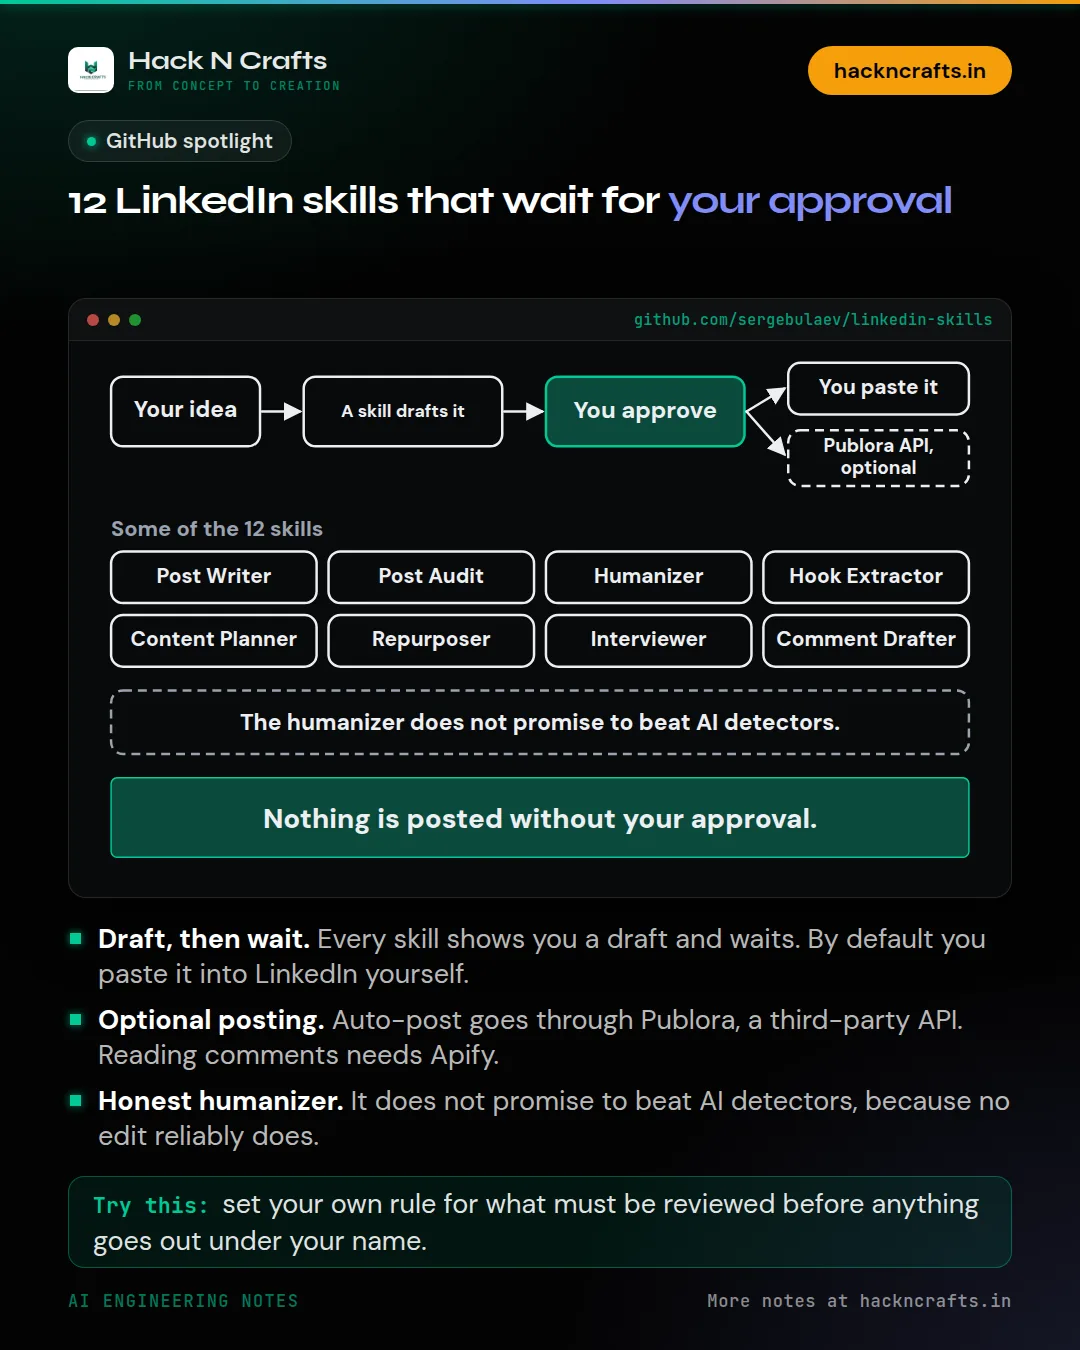
12 LinkedIn skills that wait for your approval
There's a set of 12 Claude Code and Codex skills for writing LinkedIn posts. What I like most is that none of them publish anything without your approval.
 Model Benchmarks
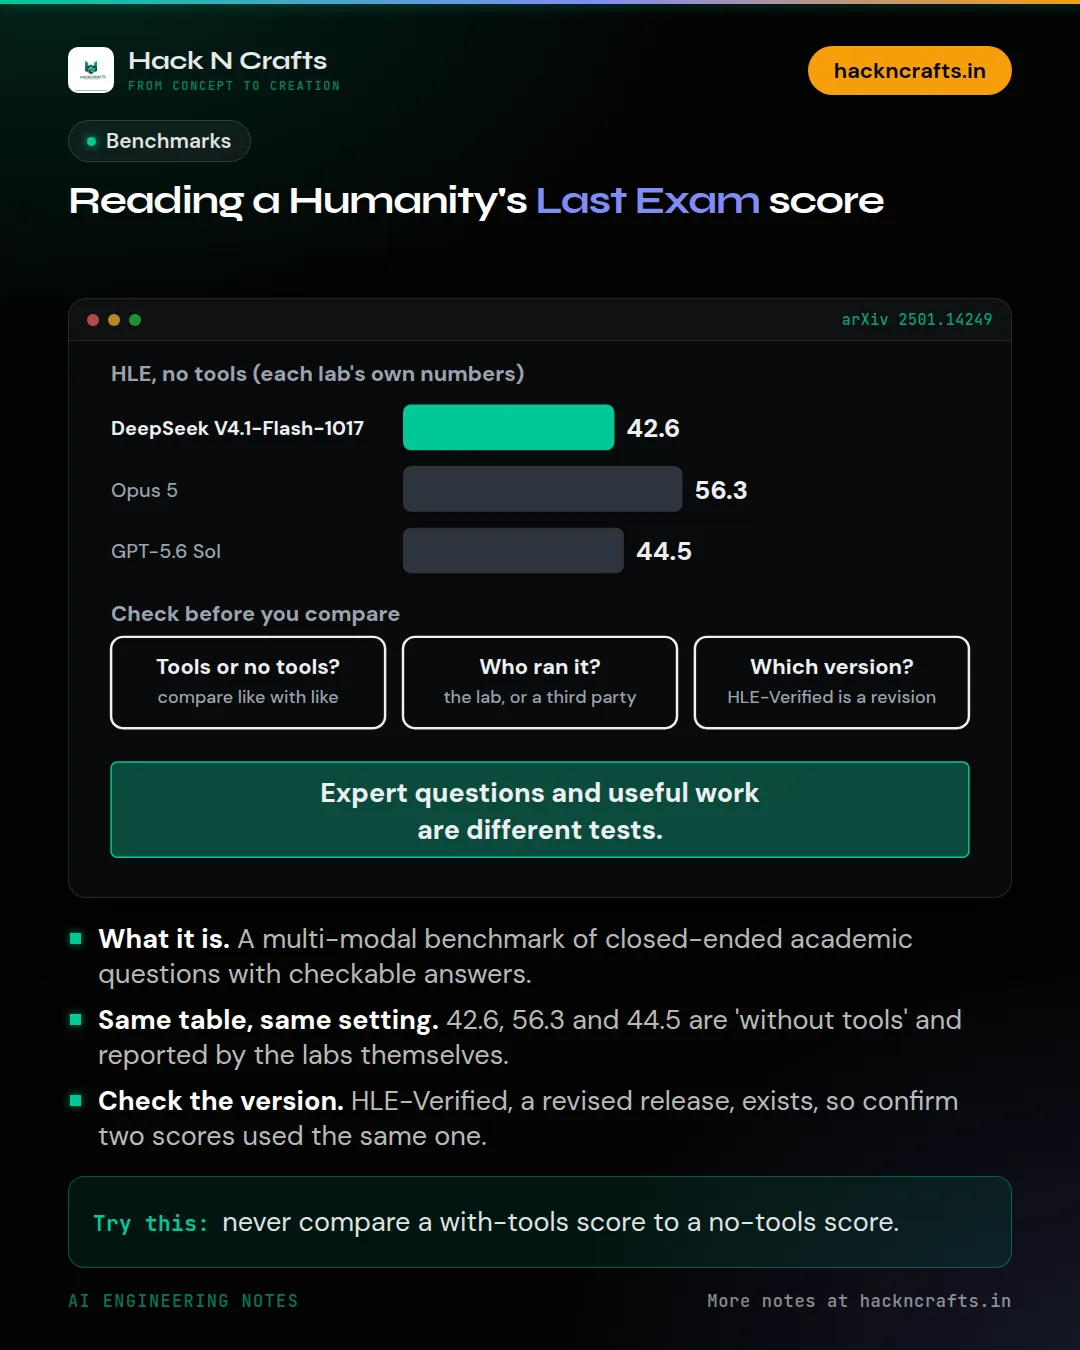
Reading a Humanity's Last Exam score
Humanity's Last Exam has a dramatic name, so a score on it is easy to over-read.
 GitHub Spotlight
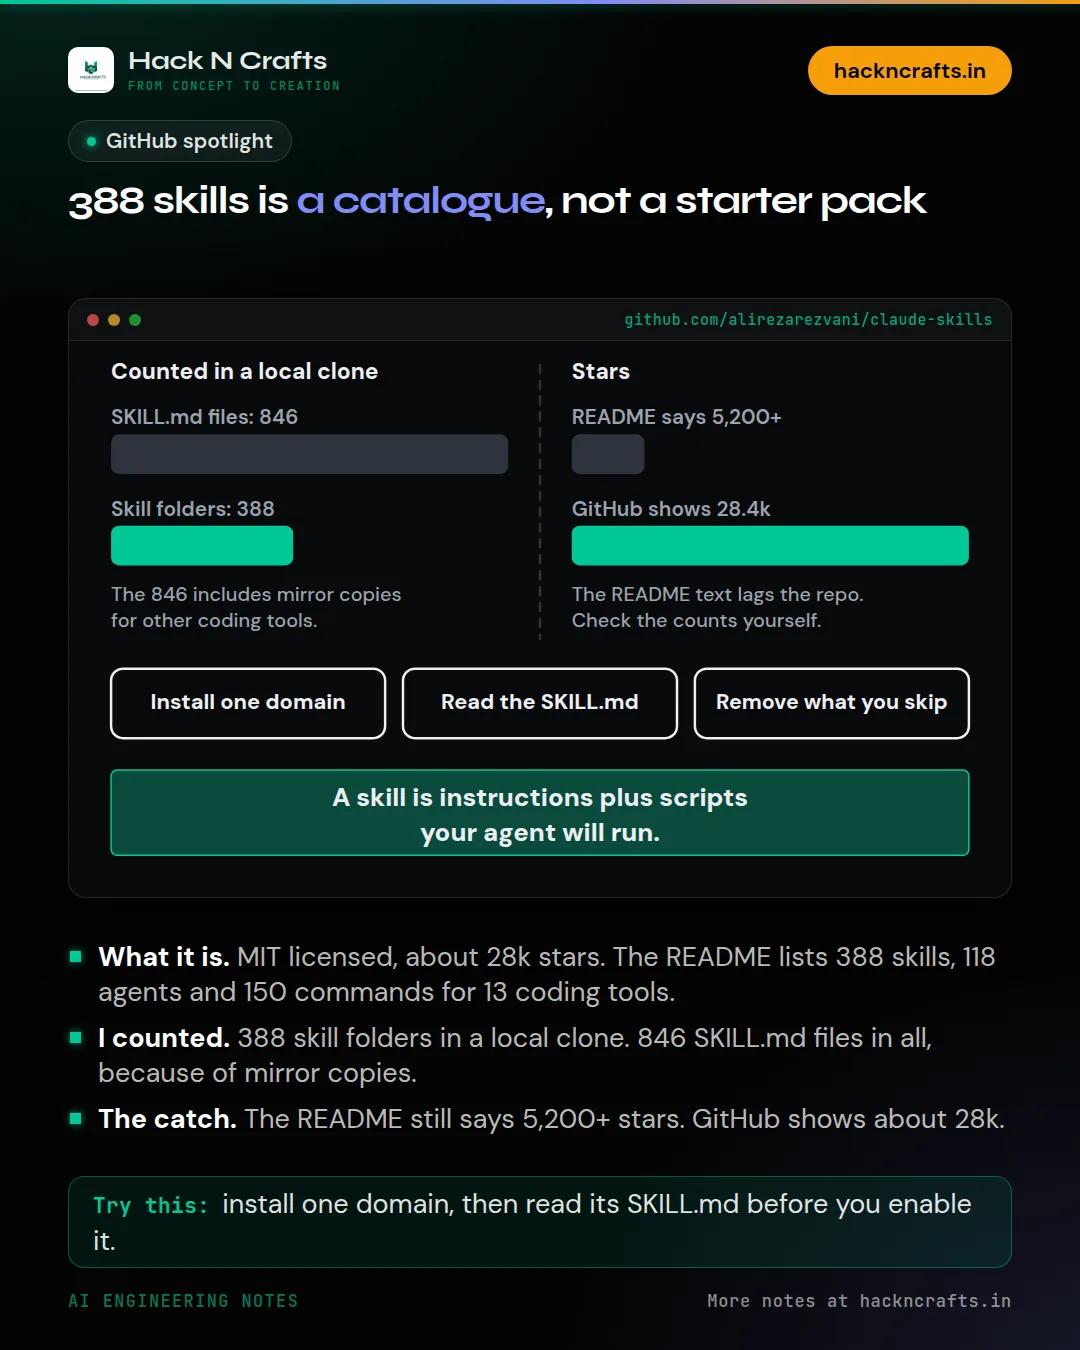
388 skills is a catalogue, not a starter pack
A library of 388 Claude Code skills sounds like a starter pack. I'd treat it as a catalogue.
 RAG
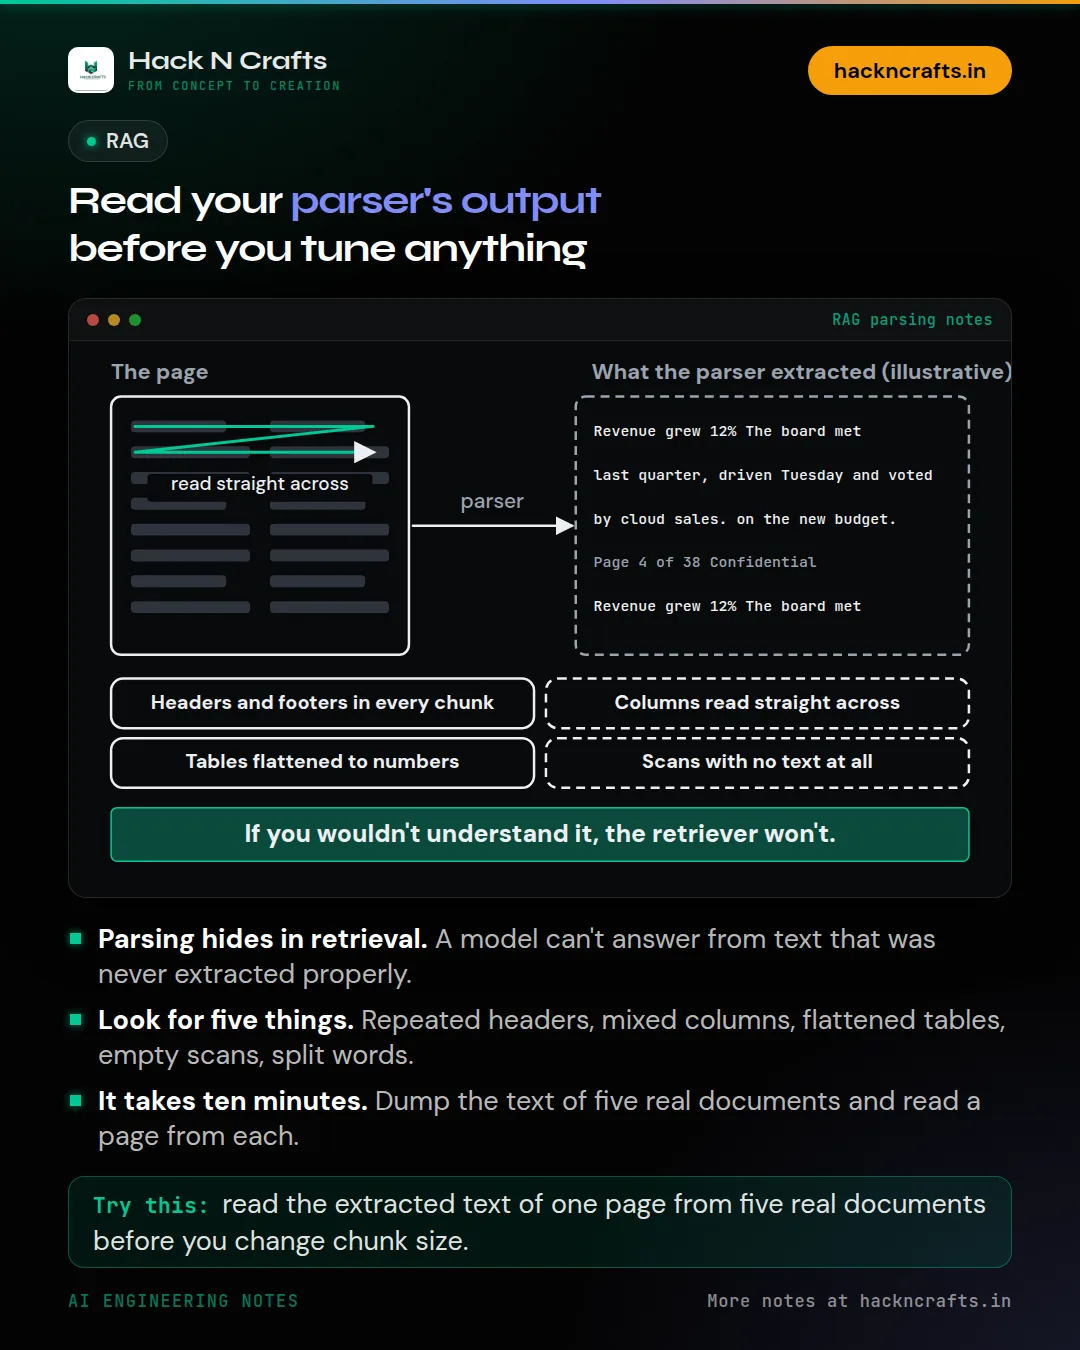
Read your parser's output before you tune anything
Before you touch chunk size or embeddings, open the text your PDF parser produced and read it.
 GitHub Spotlight
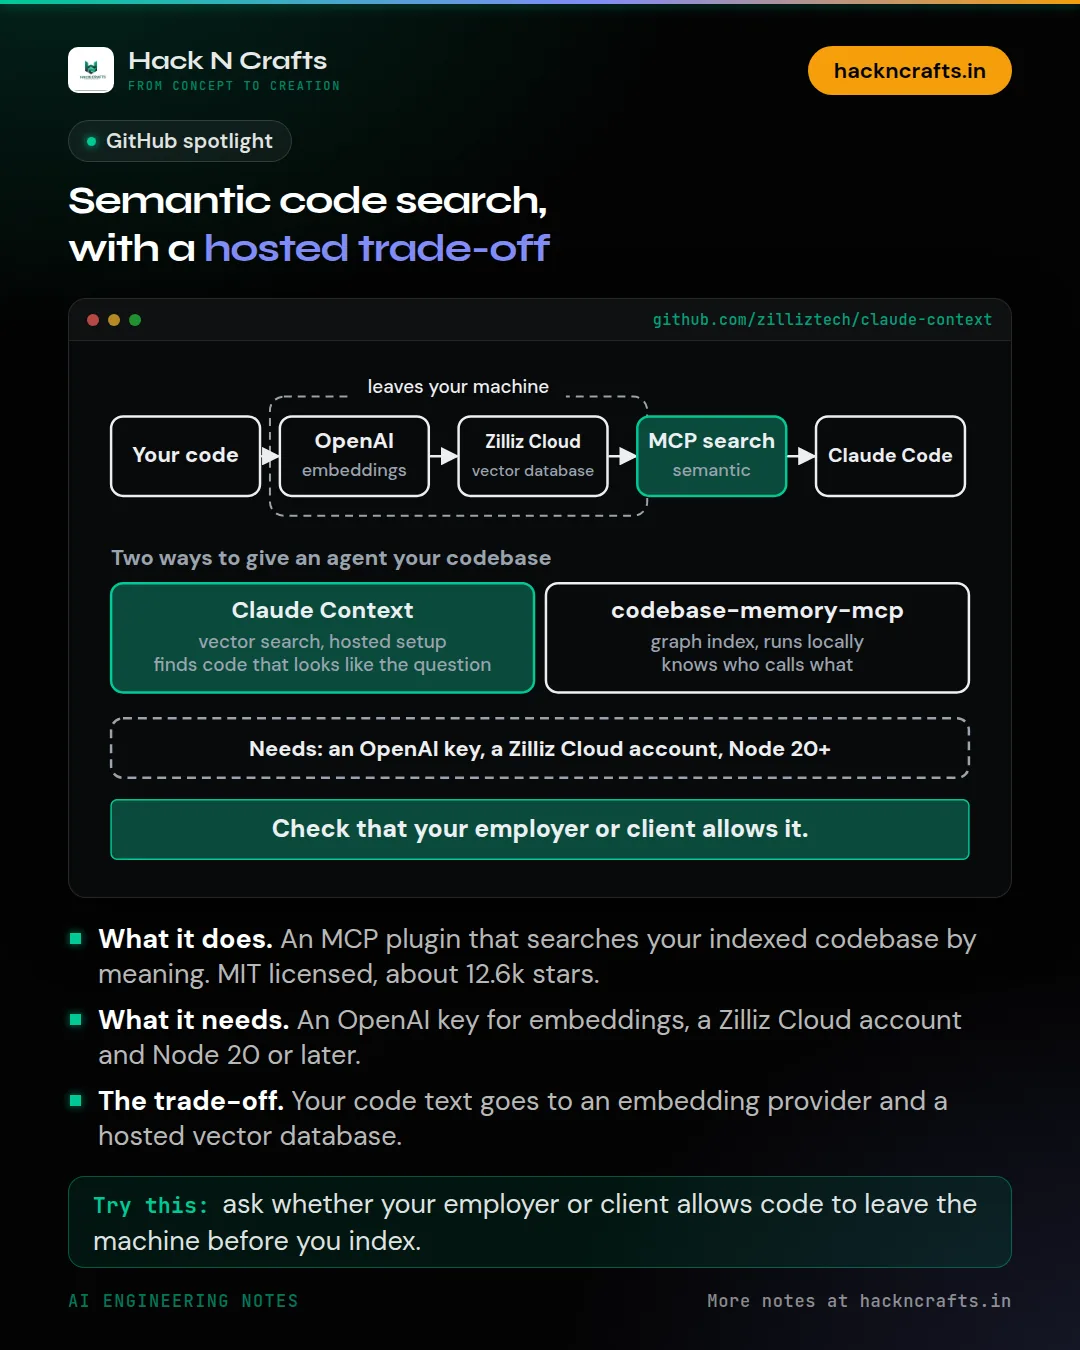
Semantic code search, with a hosted trade-off
Claude Context adds semantic code search to Claude Code through MCP. It also sends your code to two other services, so read the setup before you paste a key.
 GitHub Spotlight
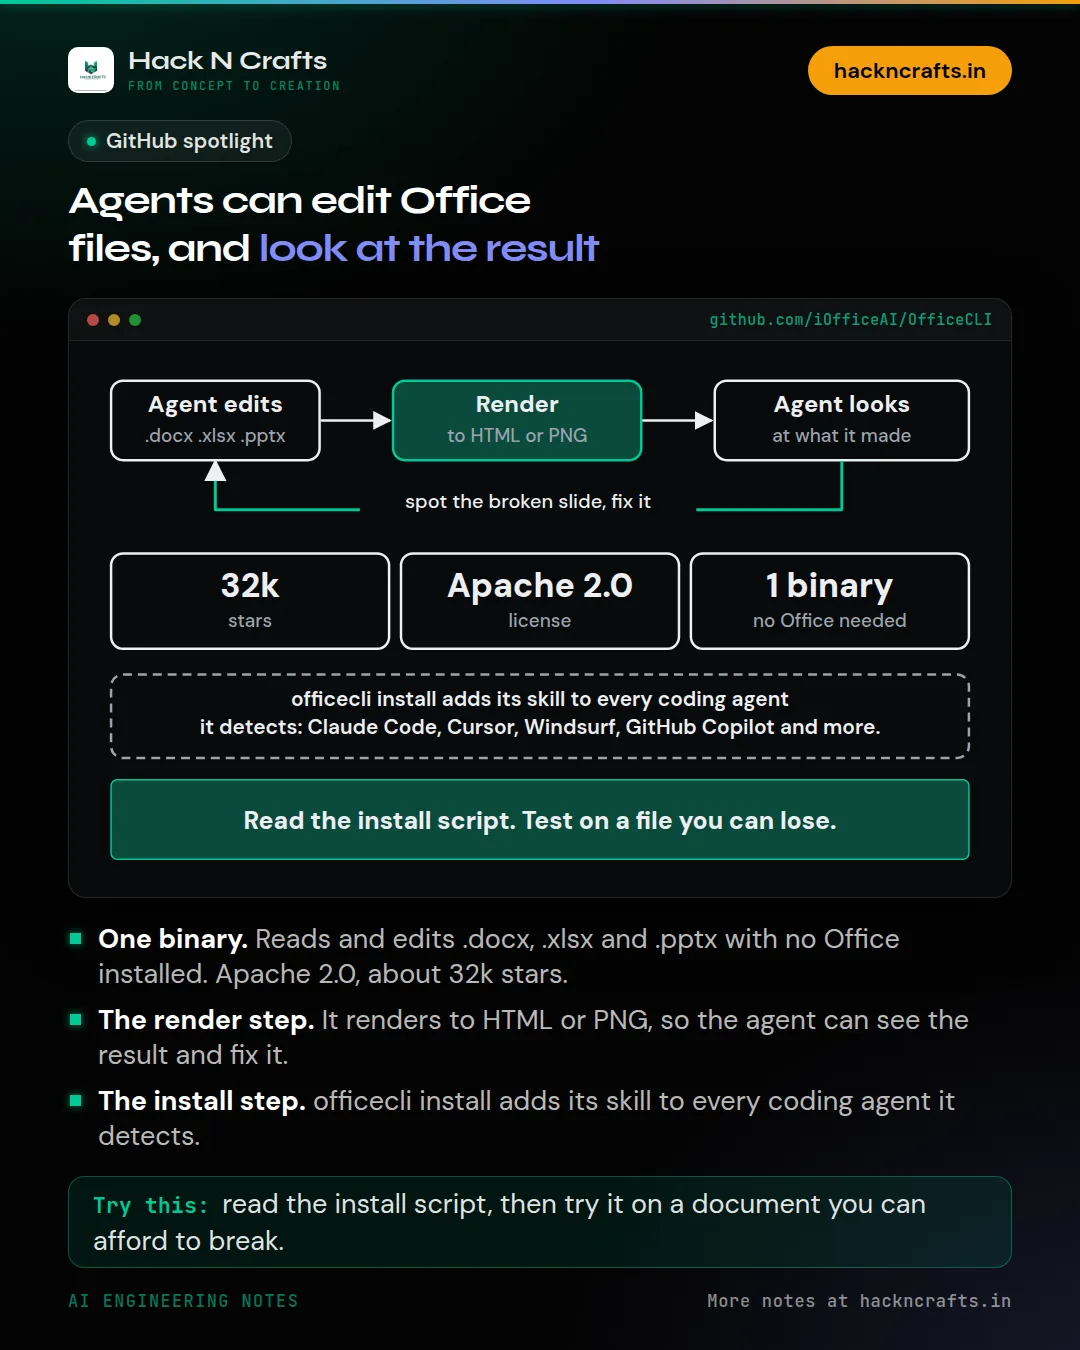
Agents can edit Office files, and look at the result
OfficeCLI lets a coding agent read and edit Word, Excel and PowerPoint files without Office installed.
 GitHub Spotlight
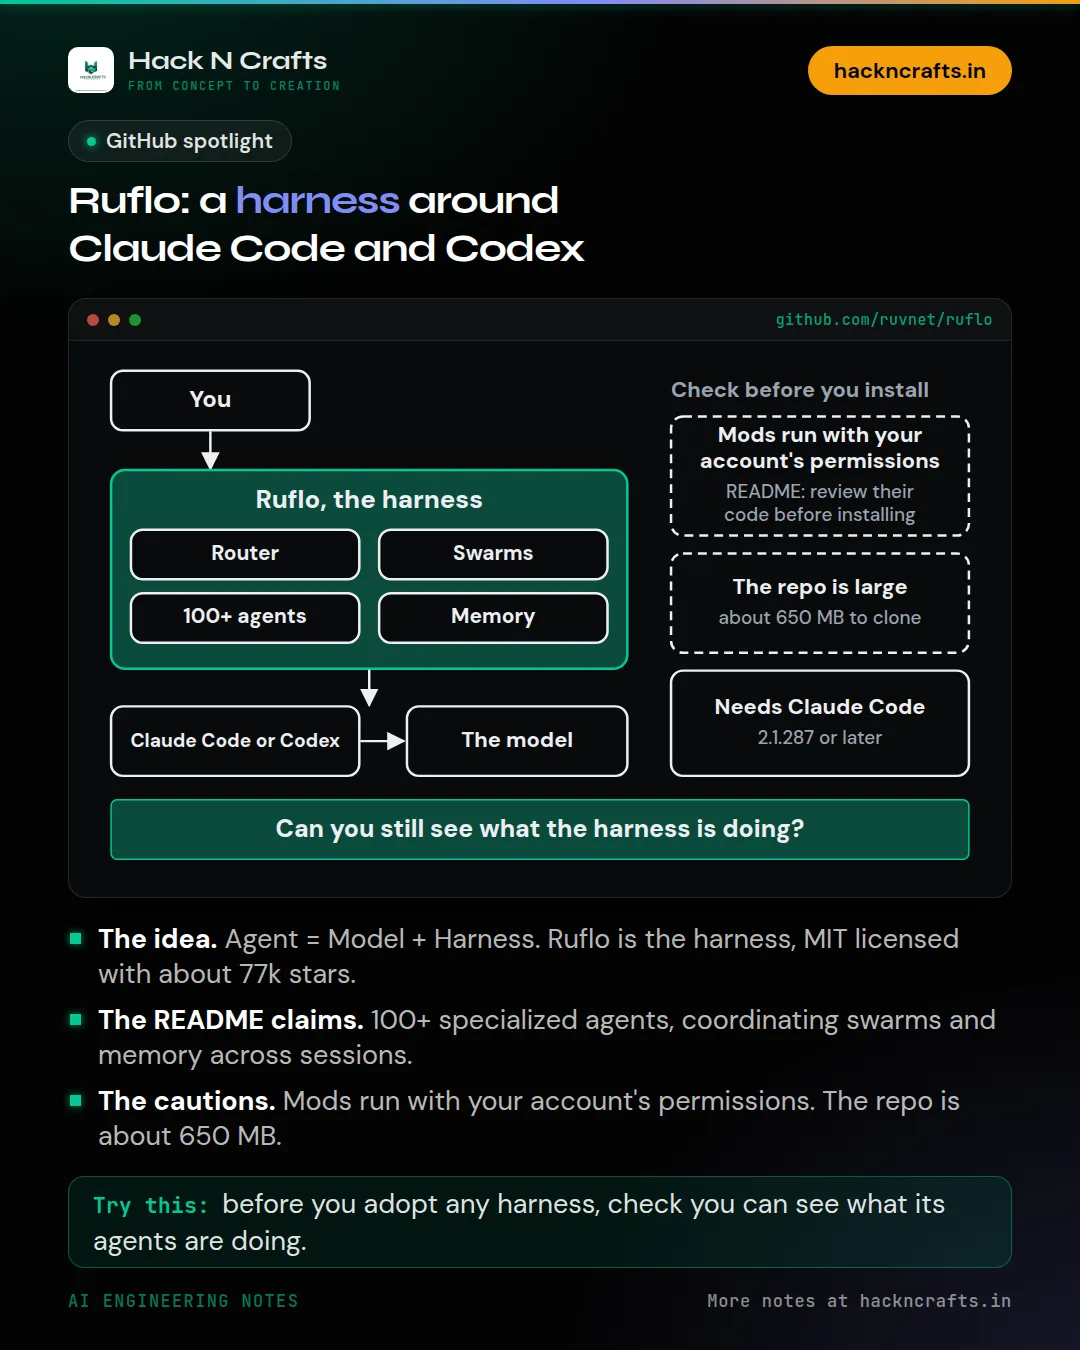
Ruflo: a harness around Claude Code and Codex
Ruflo calls itself an agent meta-harness for Claude Code and Codex. The idea is simple even if the repo is big.
 AI Agents
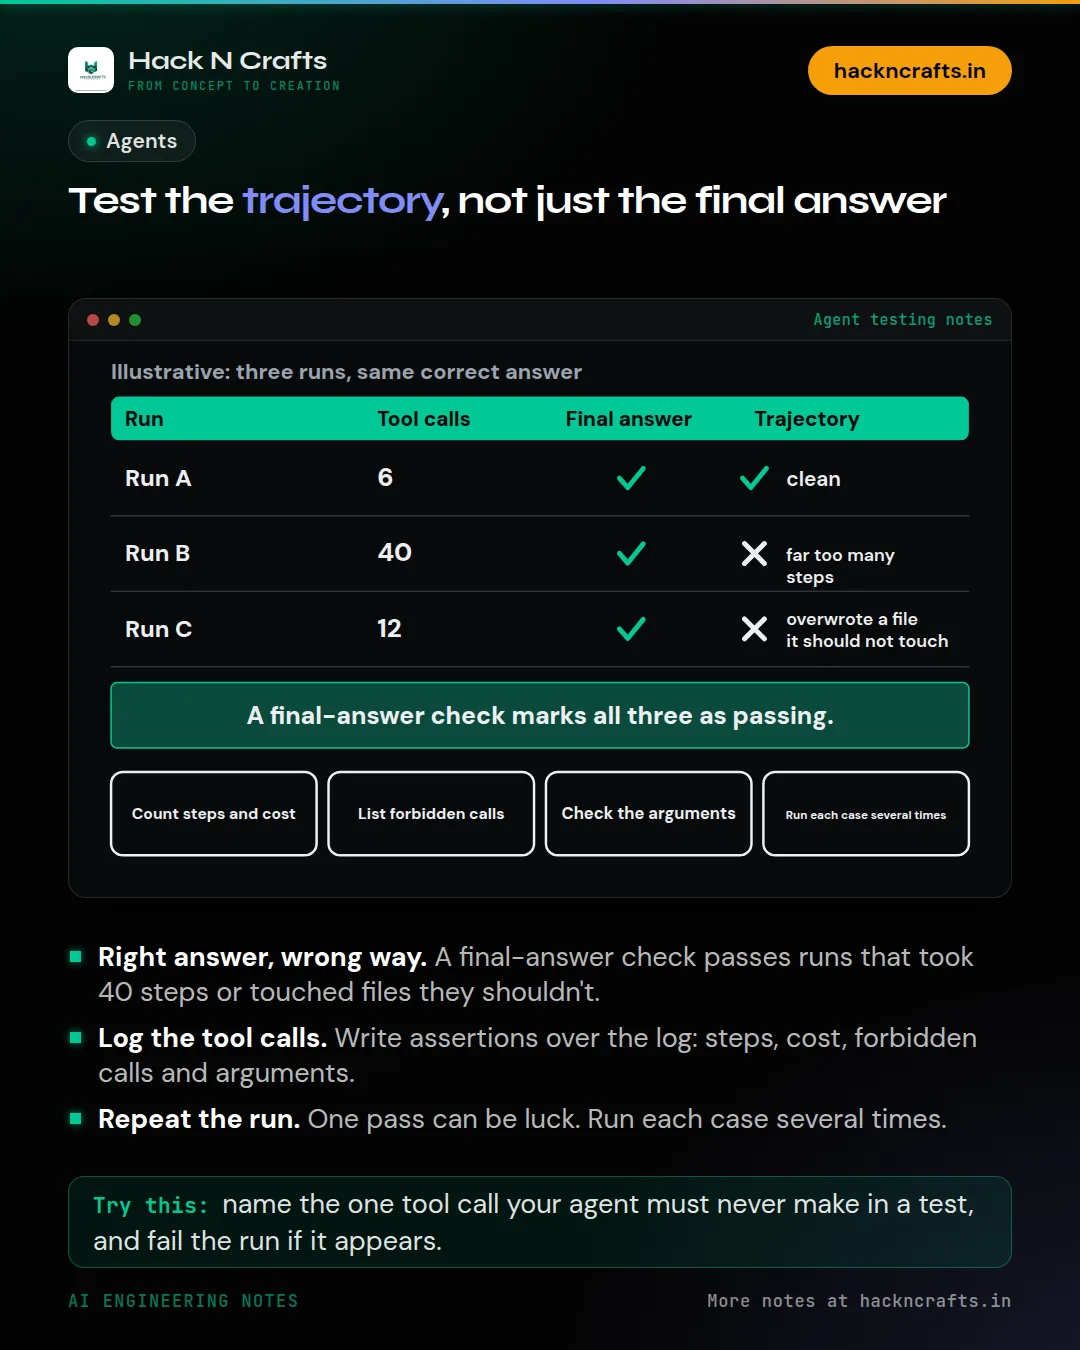
Test the trajectory, not just the final answer
An agent can reach the right answer the wrong way. If you only check the final answer, you'll miss it.
 GitHub Spotlight
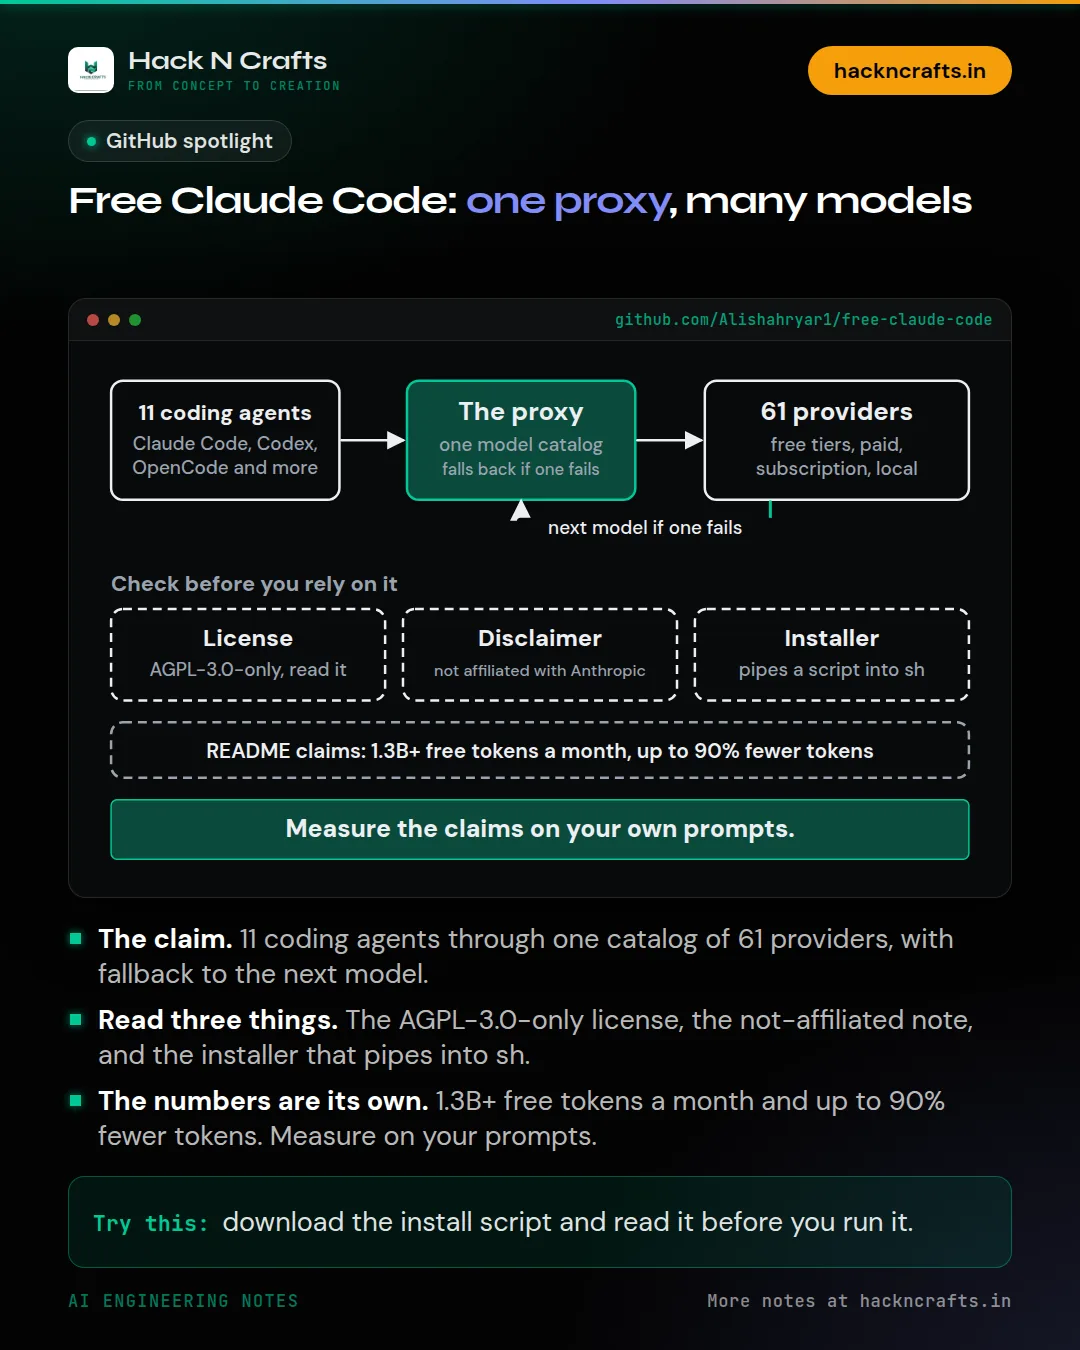
Free Claude Code: one proxy, many models
Free Claude Code is a proxy that lets Claude Code and ten other coding agents talk to models from other providers, including free tiers.
 GitHub Spotlight
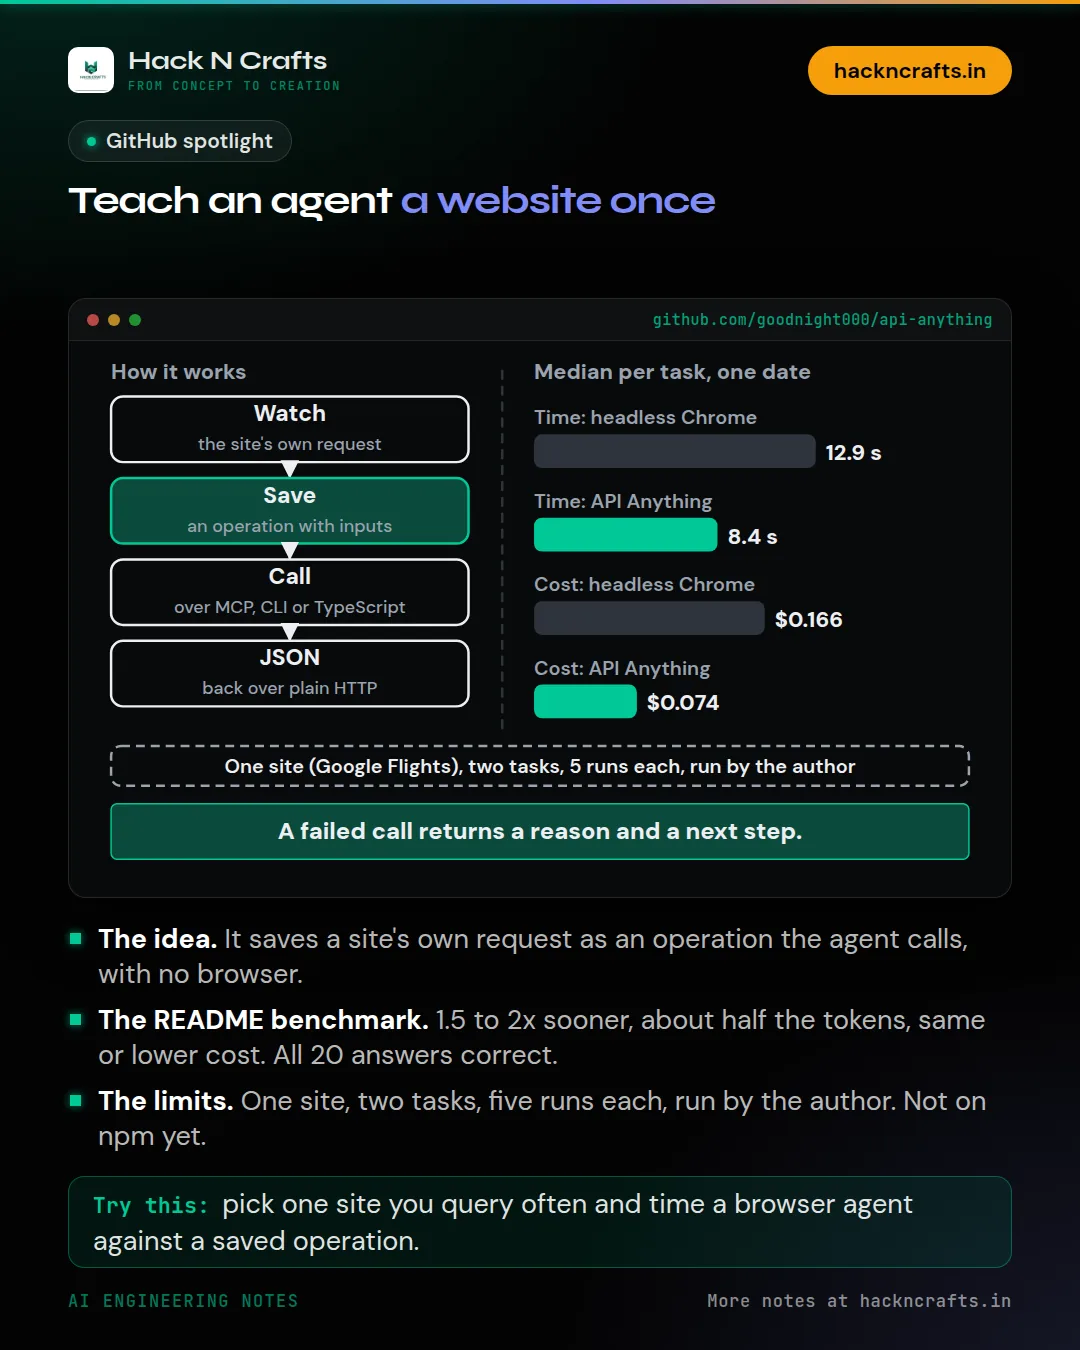
Teach an agent a website once
Teach an agent a website once, then let it call the site like an API. That's API Anything's pitch, and the README backs it with an honest benchmark.
 GitHub Spotlight
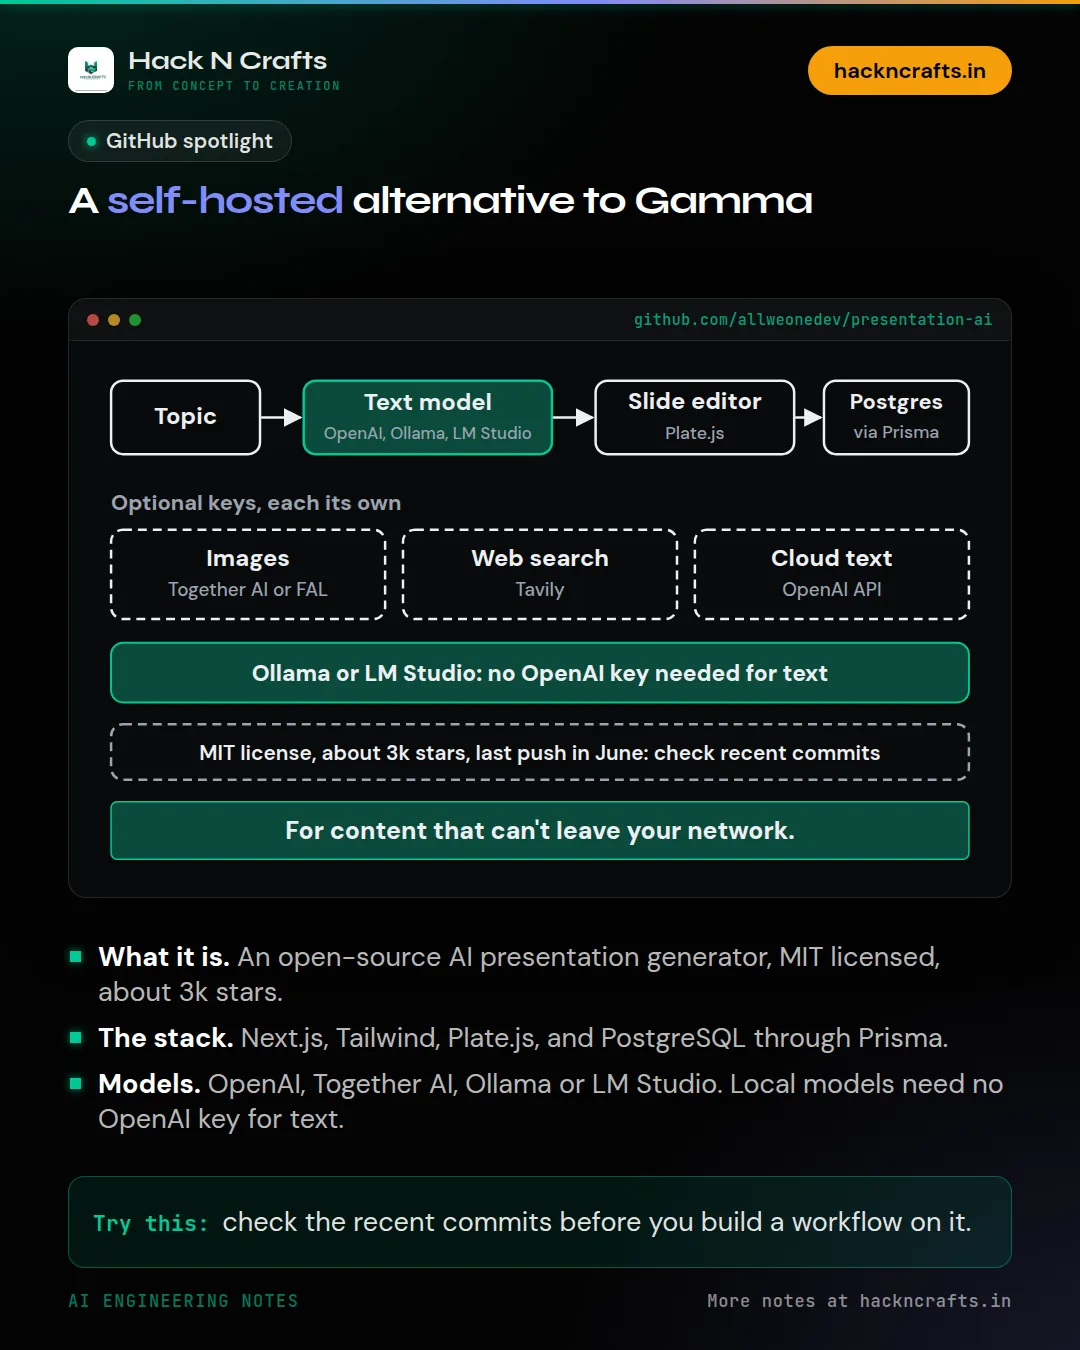
A self-hosted alternative to Gamma
A self-hosted alternative to Gamma that runs on your own database and, if you like, your own models: ALLWEONE's presentation generator.
 AI Agents
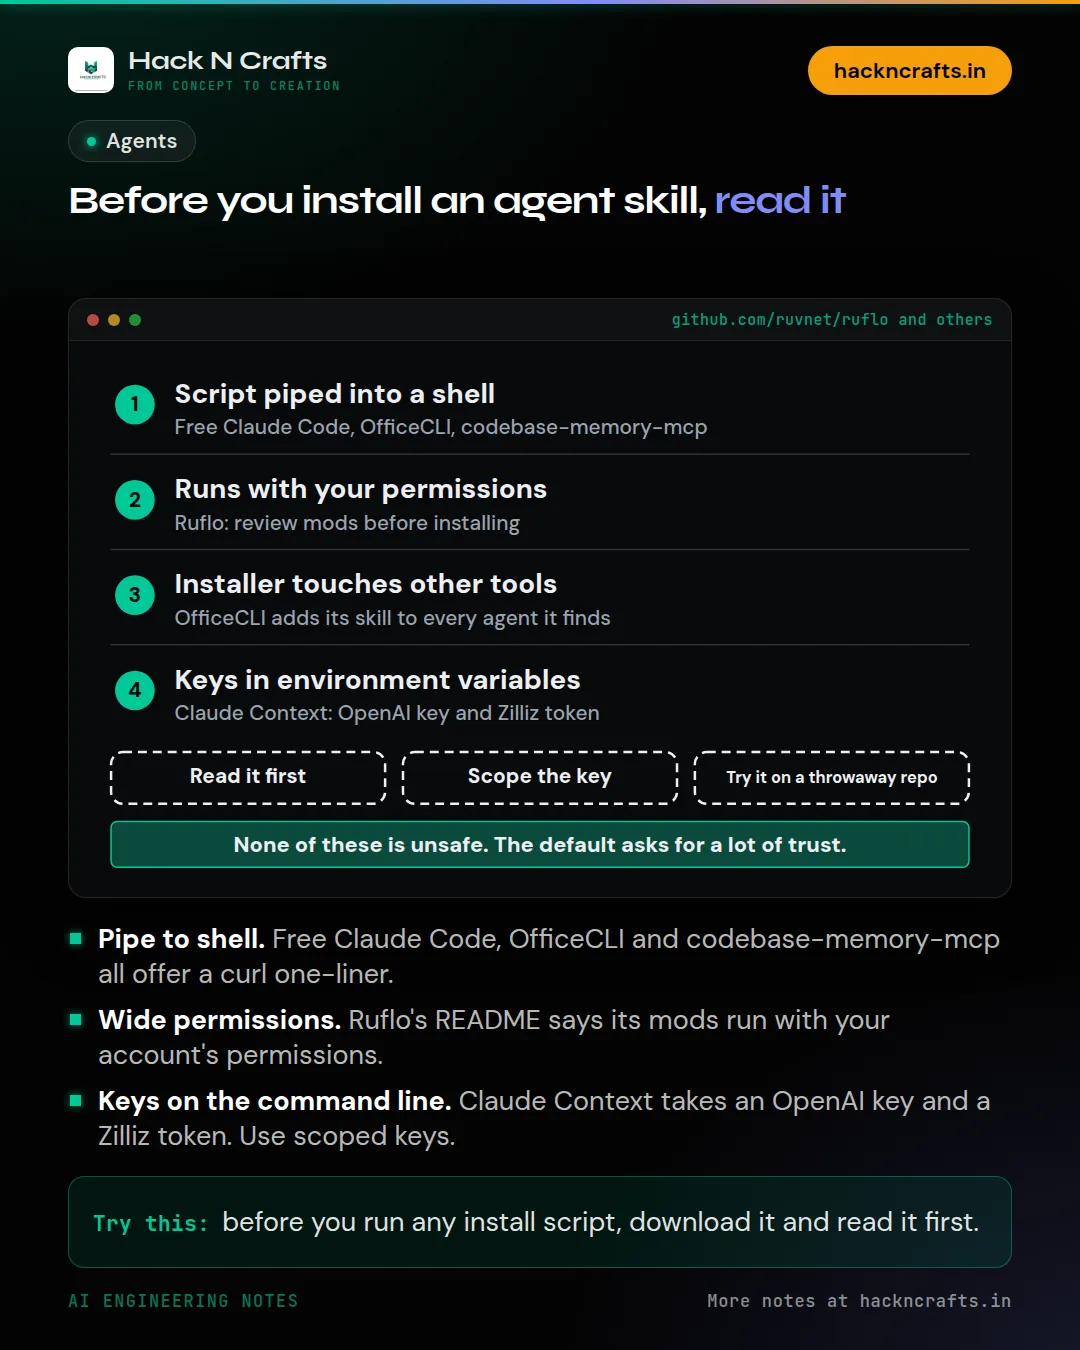
Before you install an agent skill, read it
Before you install an agent skill or plugin, read it. It runs with your permissions, and most install guides tell you to pipe a script into your shell.
Everything the notes mention
19 repos, 19 papers and 6 other pages, each with the notes that cite it.
GitHub repos and skills
- GitHub: DietrichGebert/ponytail
- GitHub: feder-cr/git-ai
- GitHub: activeing123/mcptoon
- GitHub: JuliusBrussee/caveman
- GitHub: VectifyAI/PageIndex
- GitHub: jwuthri-cloud/Tracely-ai
- GitHub: Graphify-Labs/graphify
- GitHub: trailhq/Trail-Code
- GitHub: DeusData/codebase-memory-mcp
- GitHub: OpenLAIR/PremiseCheck
- GitHub: dzhng/jevgrep
- GitHub: sergebulaev/linkedin-skills
- GitHub: alirezarezvani/claude-skills
- GitHub: zilliztech/claude-context
Semantic code search, with a hosted trade-off · Before you install an agent skill, read it
- GitHub: iOfficeAI/OfficeCLI
Agents can edit Office files, and look at the result · Before you install an agent skill, read it
- GitHub: ruvnet/ruflo
Ruflo: a harness around Claude Code and Codex · Before you install an agent skill, read it
- GitHub: Alishahryar1/free-claude-code
Free Claude Code: one proxy, many models · Before you install an agent skill, read it
- GitHub: goodnight000/api-anything
- GitHub: allweonedev/presentation-ai
Papers
- Paper: arXiv 2610.19159
Nine AI agents wrote 135 research papers. None passed. · Five AI items worth your time
- Paper: arXiv 2311.12022
- Paper: arXiv 2610.20424
- Paper: arXiv 2610.21073
Agents fix more issues when they see whole files · Five AI items worth your time
- Paper: arXiv 2610.18784
- Paper: arXiv 2210.07316
- Paper: arXiv 2610.22428
The vocabulary is most of a small model · Five papers worth your time
- Paper: arXiv 2610.07898
A 4B agent that learns from its failed patches · How to read a score with an @k on it · Five papers worth your time
- Paper: arXiv 2610.23787
Agents break speculative decoding. History is why · Five papers worth your time
- Paper: arXiv 2406.12045
- Paper: arXiv 2610.22602
- Paper: arXiv 2610.16071
- Paper: arXiv 2610.18082
- Paper: arXiv 2403.07974
- Paper: arXiv 2610.14157
A phone agent that taps screens and calls app tools · Five papers worth your time
- Paper: arXiv 2610.21046
Check claims with a cheap model after a rewrite · Five papers worth your time
- Paper: arXiv 1911.01547
- Paper: arXiv 2501.14249
- Paper: arXiv 2602.13964
Model cards and pages
- anthropic.com /engineering
When agents write the code, merging is the bottleneck · gitai: an open-source take on Anthropic's Scion · Five AI items worth your time
- openai.com /index
- Hugging Face: deepseek-ai/DeepSeek-V4.1-Flash-1017
A model card that wins some benchmarks and loses others · Five AI items worth your time · Five checks before you trust a model card · Reading a Humanity's Last Exam score
- Hugging Face: google/embeddinggemma-2
EmbeddingGemma 2: one vector space for four modalities · The MTEB average hid the jump · Five AI items worth your time
- Hugging Face: LiquidAI/LFM2.5-24B-A2B
- arena.ai /leaderboard