Give every chunk its context before you embed
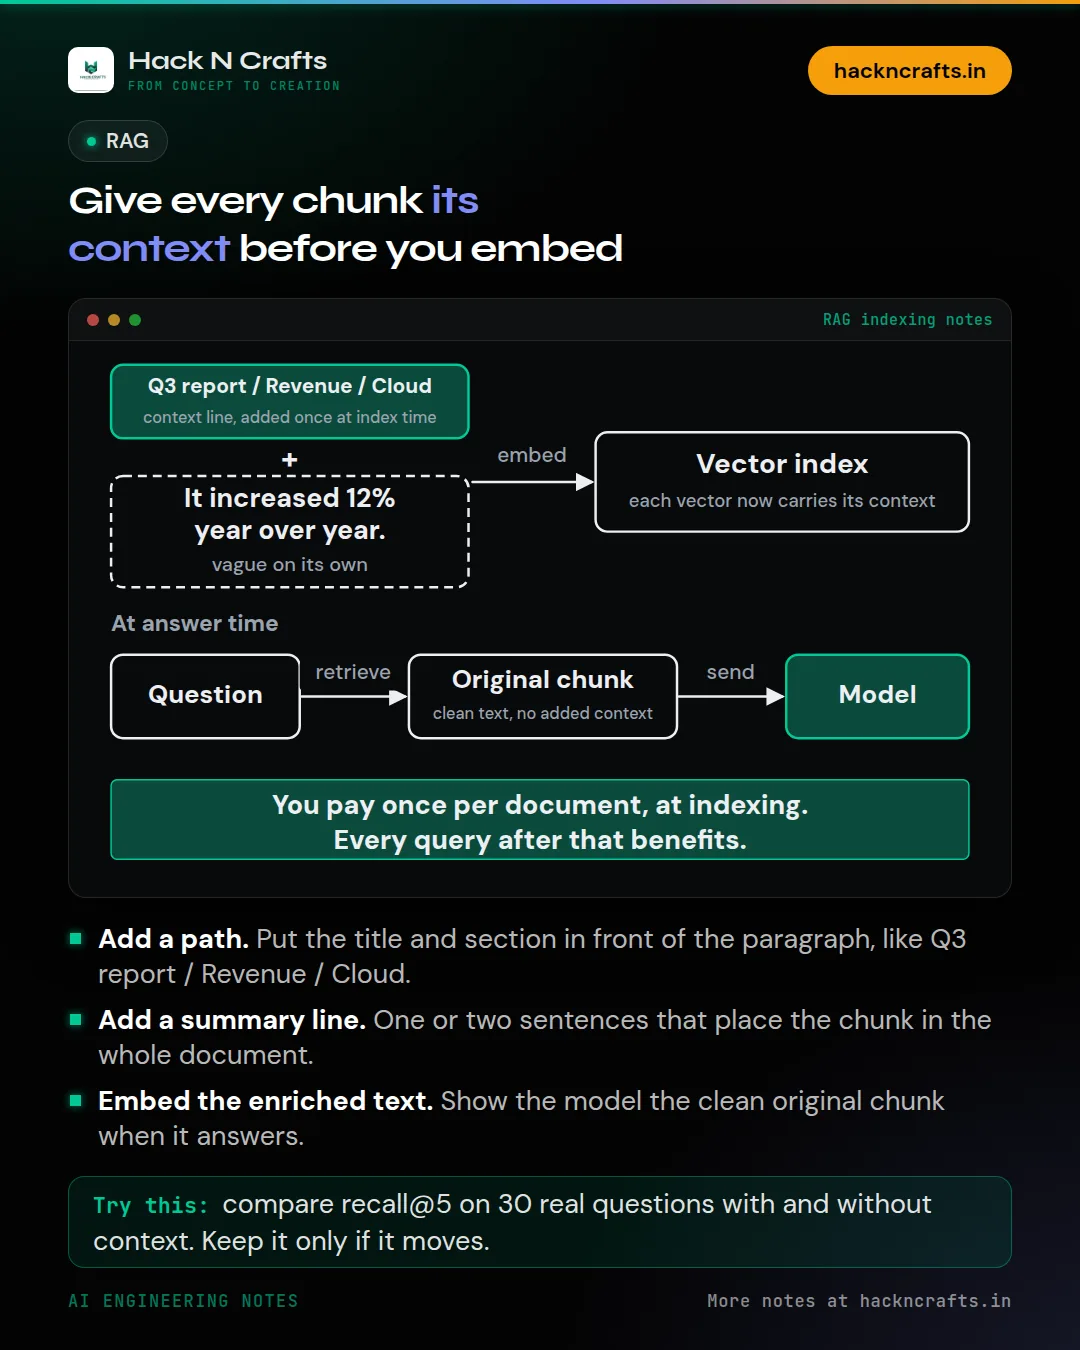
A chunk that says 'it increased 12% year over year' is useless on its own. What increased? Which year?
That's the problem with chunking a long document and embedding the pieces in isolation. The chunk lost the context that made it make sense, so its embedding is vague and the retriever can't match it to a real question.
The fix is cheap: add context to each chunk before you embed it.
- 1Prepend the title and section path. 'Q3 report > Revenue > Cloud' goes in front of the paragraph.
- 2Add one or two sentences that place the chunk in the whole document. A model can write these once, at indexing time.
- 3Embed the enriched text, but show the model the clean original chunk when it answers.
It costs extra work at indexing time, not at query time. That's the right place to spend it, because you pay once per document and every query benefits.
To test it, take 30 questions your users ask and compare recall@5 with and without the added context. If the number moves, keep it. If it doesn't, you saved yourself a complication.
Do your chunks still make sense when you read one on its own?
New notes go out on LinkedIn first. Building something with AI? We can help.