LFM2.5-24B-A2B: 24B parameters, about 2B active
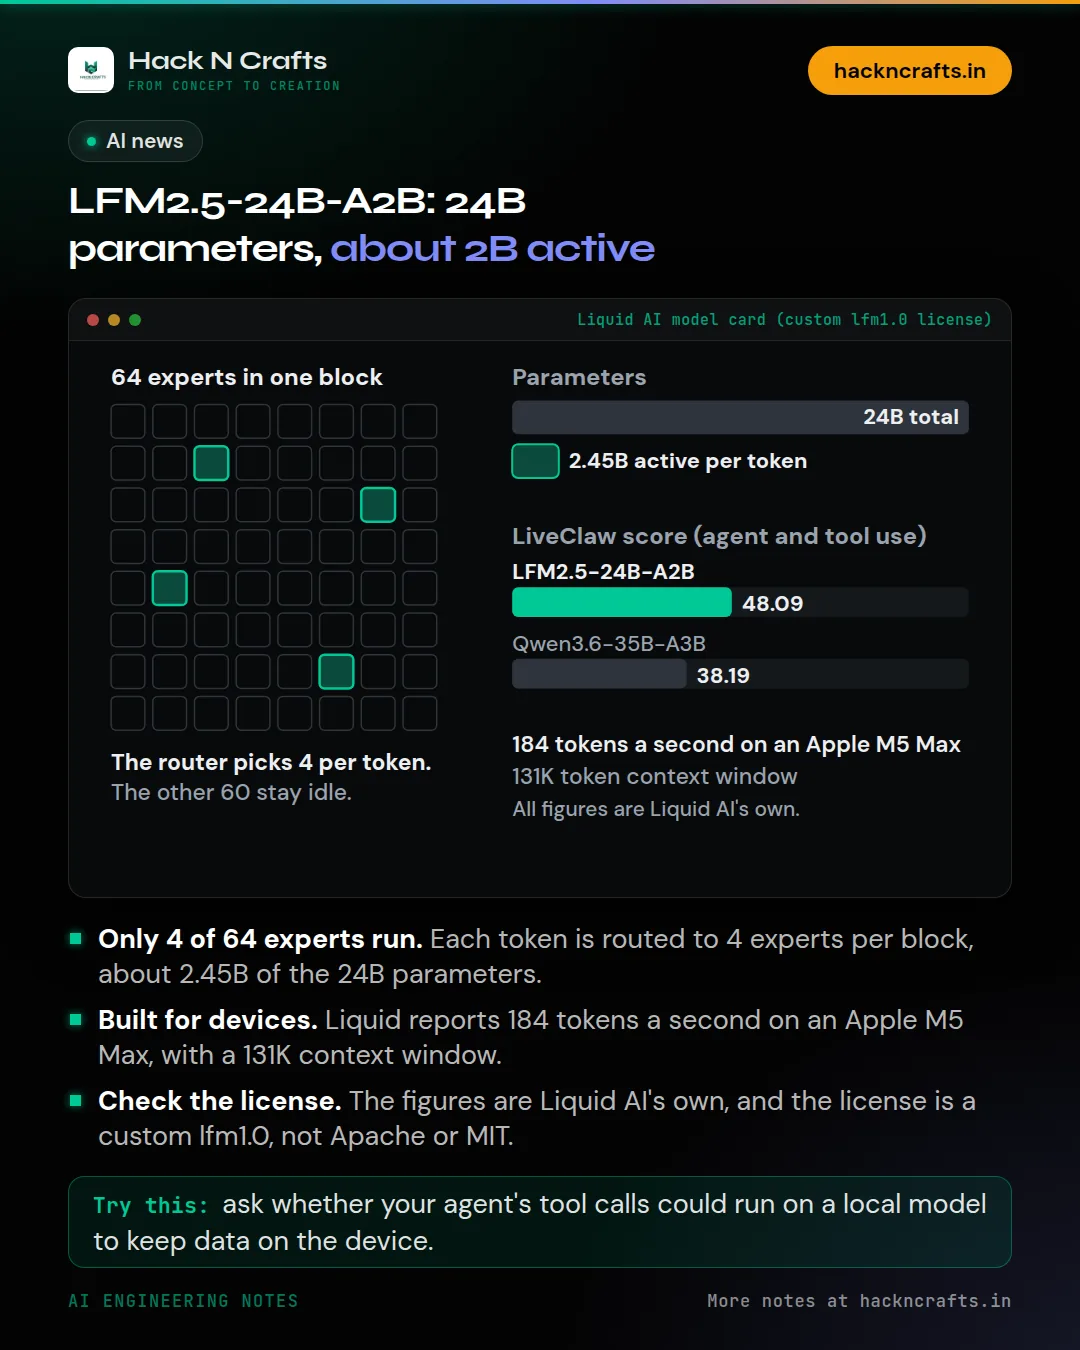
Liquid AI released LFM2.5-24B-A2B, a mixture-of-experts model built to run agents privately on a device. It has 24B parameters, but only about 2.45B are active for each token.
From the model card: 64 experts per block with 4 chosen per token, a 131K context window, 16 languages and 36 trillion training tokens. Liquid reports 184 tokens a second on an Apple M5 Max, and up to 1.7x faster than comparable on-device MoE models. On an agent and tool-use benchmark called LiveClaw it scores 48.09, against 38.19 for Qwen3.6-35B-A3B, a model with roughly 50% more parameters.
The small active size is the trick. Speed and cost per token follow the active parameters, while quality tends to follow the total. That's how a 24B-class model can run on a laptop.
Two cautions. The numbers are Liquid's own. And the license is Liquid's custom lfm1.0 license, not Apache or MIT, so read it before you ship it in a product.
Would you run your agent's tool calls on a local model to keep data on the device? What's stopping you?
Sources
New notes go out on LinkedIn first. Building something with AI? We can help.