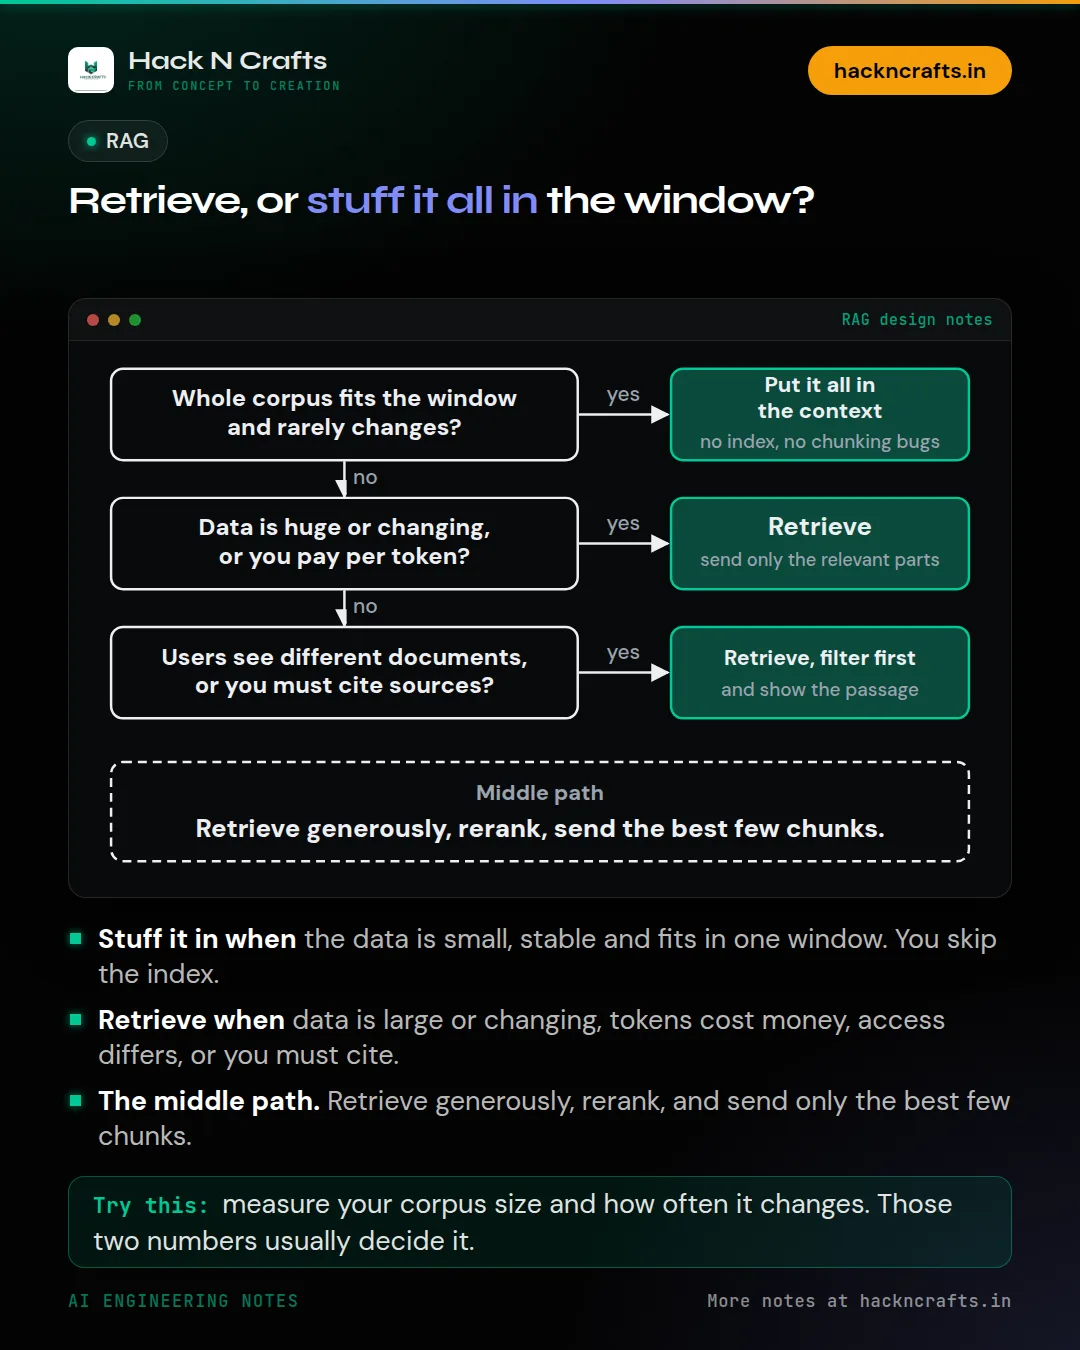
Retrieve, or stuff it all in the window?
Long context windows didn't kill RAG. They changed when you need it.
If your whole knowledge base fits in the window and rarely changes, stuffing it all in is simple and often good enough. You skip the index, the chunking and the retrieval bugs. For a small set of stable documents that's a fair trade.
Retrieval still wins in four cases:
- 1The data is bigger than any window, or grows every day.
- 2You pay per token. Sending 200 pages with every question adds up fast.
- 3Different users may only see different documents, so you have to filter before the model reads anything.
- 4You need to show exactly which passage an answer came from.
There's a quality angle too. Models don't use every part of a long input equally well, and one study of this found that information in the middle is used less reliably than information at the start or the end. A short, well-chosen context can beat a long, noisy one.
A middle path many teams land on: retrieve generously, rerank, then put only the best few chunks in the window. You get the benefits of both.
How big is your corpus, and how often does it change? Those two numbers usually decide it. Which side are you on right now?
New notes go out on LinkedIn first. Building something with AI? We can help.