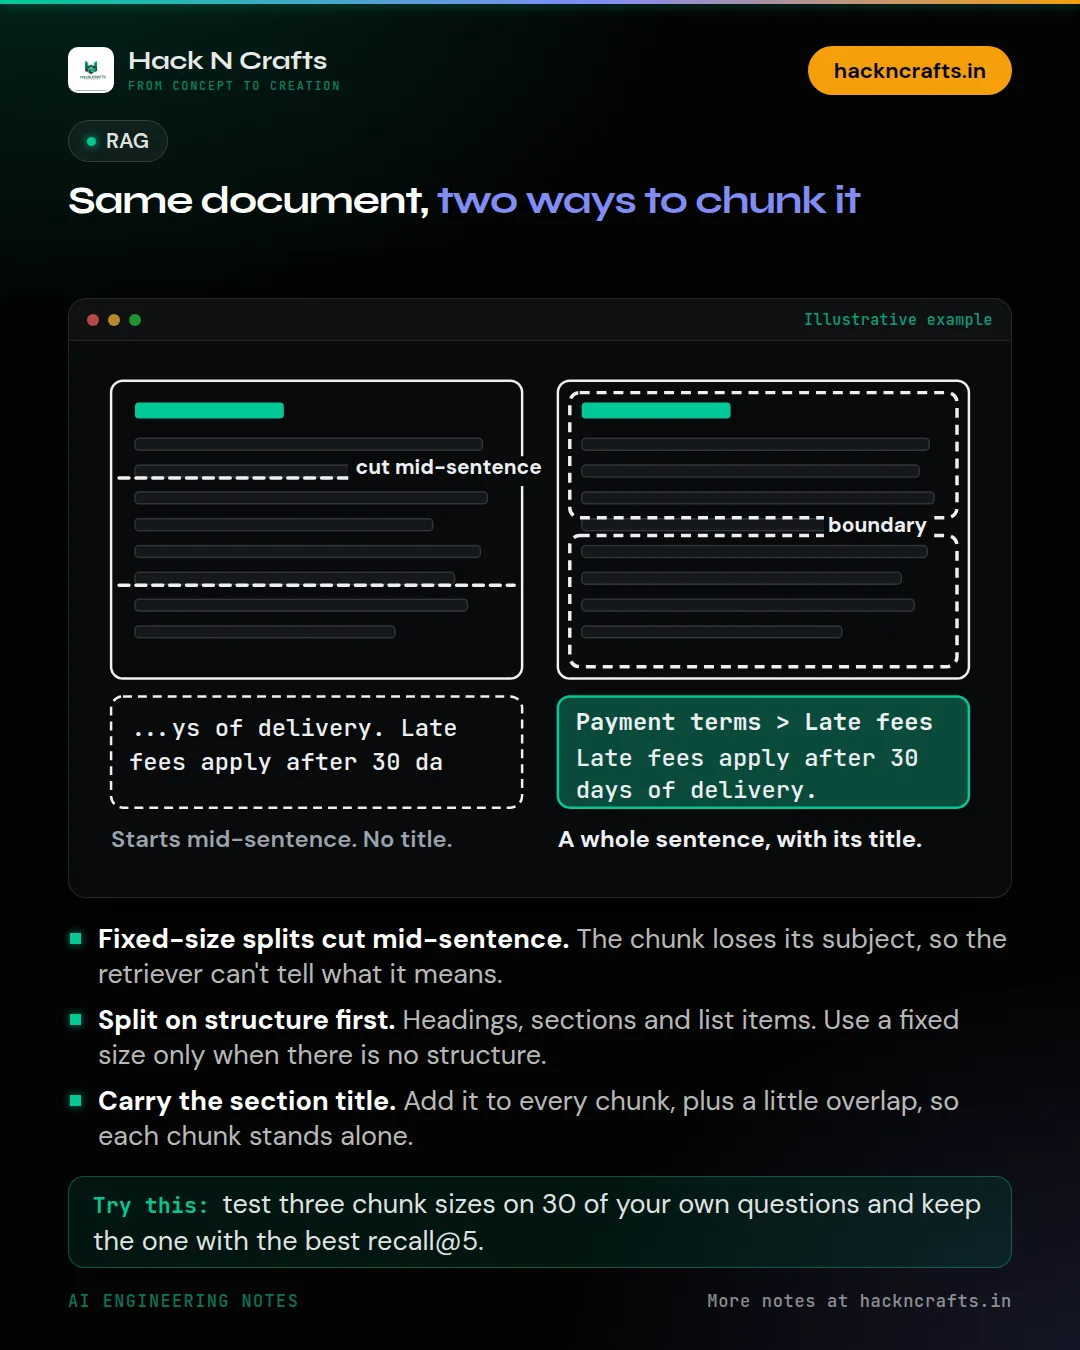
Same document, two ways to chunk it
Most RAG answers go wrong before the model ever sees the question.
The retriever hands back a chunk that starts mid-sentence, or a table row cut off from its header, or one useful line buried under four paragraphs of boilerplate. Then the model does its best with what it got.
A few chunking habits that help:
- 1Split on structure first: headings, sections, list items. Use a fixed size only when there's no structure to follow.
- 2Keep a little overlap, and carry the section title into every chunk so it still makes sense on its own.
- 3Test chunk sizes on your own questions. Start with a few hundred tokens and measure. What works for support tickets won't work for legal PDFs.
None of this is glamorous. It's usually the cheapest accuracy gain you can get before touching embeddings or rerankers.
What chunk size are you running, and have you ever tested it?
#RAG#GenerativeAI#LLM#AI
New notes go out on LinkedIn first. Building something with AI? We can help.