10x fewer tokens, and an honest trade-off
One MCP server claims 10x fewer tokens on code questions. Its own preprint also admits the answers were a bit worse. I like that it says so.
codebase-memory-mcp (46k stars, MIT) is a local MCP server that indexes your repo into a knowledge graph of functions, classes, imports and routes, across 162 languages. It runs on your machine, with no hosted service or API key. Your agent queries the graph, through 17 MCP tools, instead of reading files one by one.
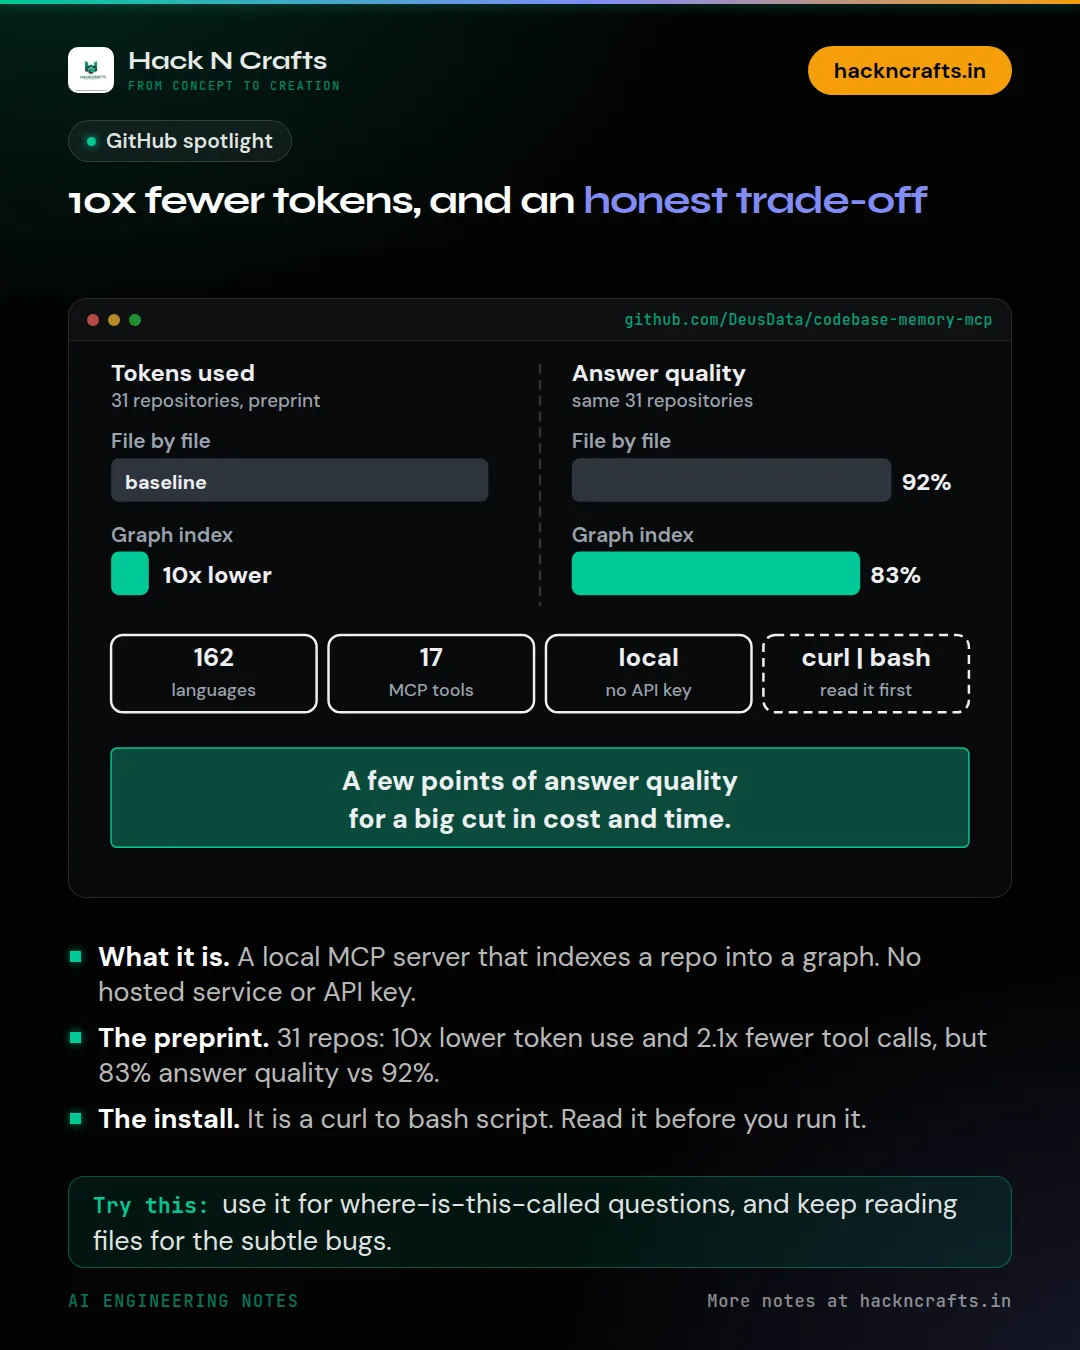
The numbers, as the README reports them. In a five-query comparison: about 3,400 tokens versus about 412,000 with file-by-file exploration, which is where its 120x headline comes from. In the preprint across 31 repositories: 10x lower token use and 2.1x fewer tool calls, with answer quality of 83% for the graph approach versus 92% for file-by-file. I'd quote the 10x.
That last pair is the honest part. You trade a few points of answer quality for a large cut in cost and time. Whether that's good depends on the question. For 'where is this called?' it's probably great. For a subtle bug in code the index doesn't capture well, reading the files may still win.
Install is a script you pipe to bash, so read it first. Then ask your agent to 'index this project'.
Would you take 10x fewer tokens for a few points of accuracy?
Sources
New notes go out on LinkedIn first. Building something with AI? We can help.