Grade retrieval and generation separately
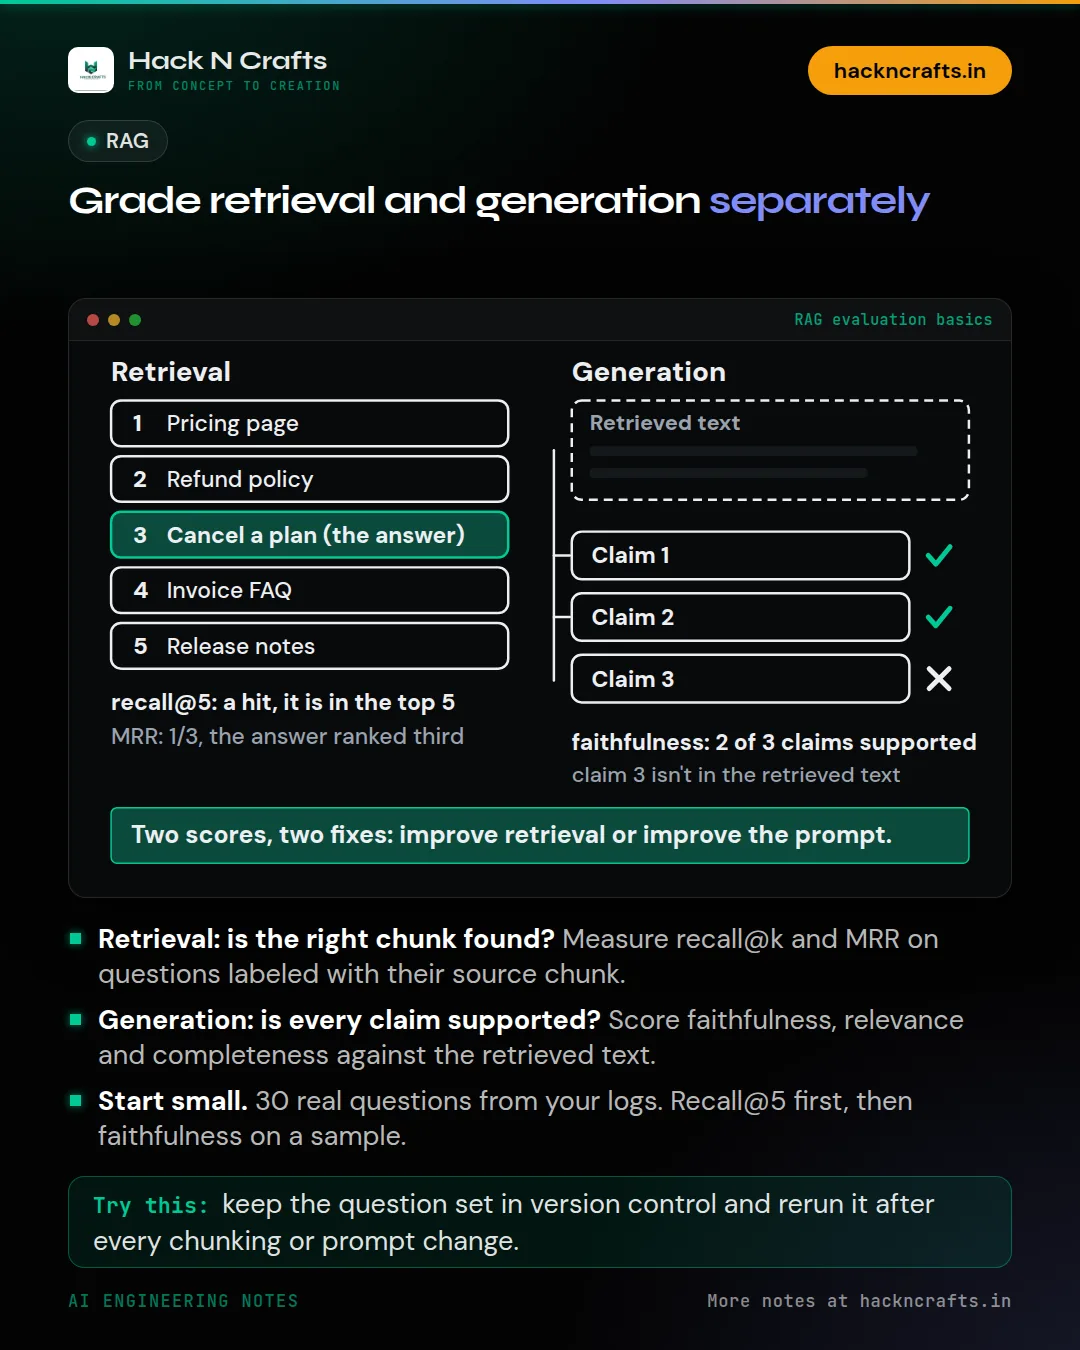
When a RAG answer is wrong, you need to know which half failed. Grade retrieval and generation separately.
For retrieval, you need a small set of questions, each labeled with the document or chunk that holds the answer. Then measure recall@k (is the right chunk in the top k?) and MRR (how high does the first right chunk rank?).
For generation, look at faithfulness (is every claim supported by the retrieved text?), answer relevance (does it address the question?) and completeness (did it skip something that was in the context?).
You can start in an afternoon. Write 30 real questions from your users or your logs, not invented ones. Label the source chunk for each. Compute recall@5 first. If it's low, tweaking the prompt won't help. Only then score faithfulness, with a human checking a sample and an LLM judge validated against that sample.
Keep the question set in version control and rerun it whenever you change chunking, embeddings or prompts. That one habit catches most regressions.
How many labeled test questions does your RAG app have today?
New notes go out on LinkedIn first. Building something with AI? We can help.