Caveman: fewer tokens in, fewer tokens out
Caveman is one of the most starred agent skills on GitHub (113k stars). The pitch is a joke that turns out to be useful: why use many token when few token do trick.
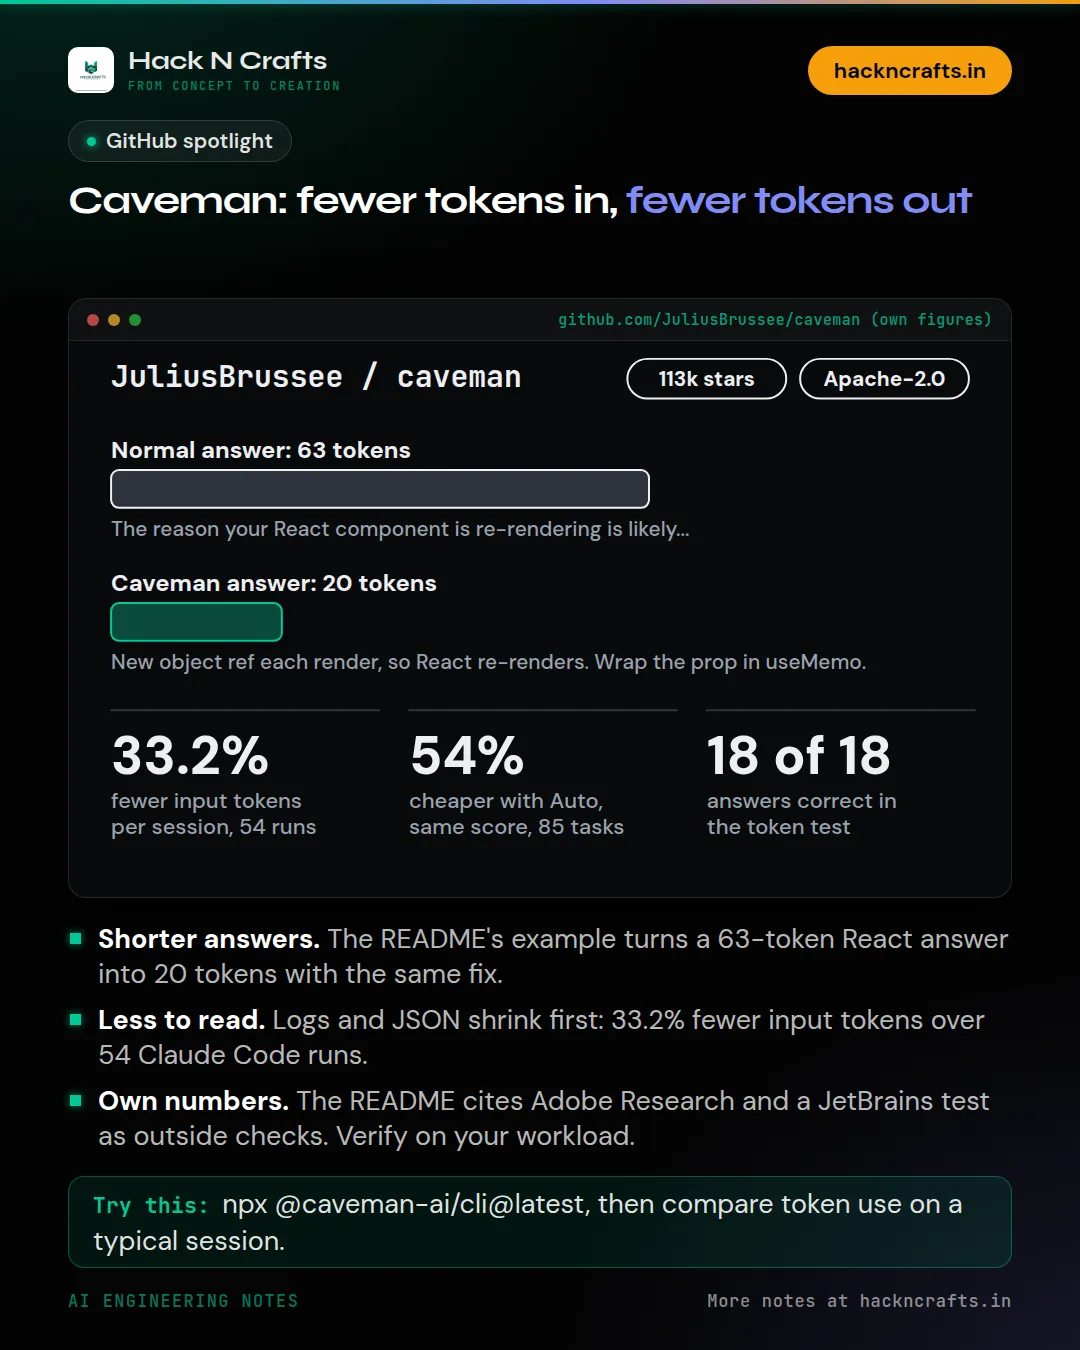
Per the README, it does three things. It makes the agent answer in short, plain sentences and keeps code exact. The README's example turns a 63-token answer about a React re-render into 20 tokens with the same fix. It shrinks logs, JSON and test output before the model reads them, reported as 33.2% fewer input tokens across whole sessions, over 54 Claude Code runs, with 18 of 18 answers correct. And an Auto mode picks the model and effort for each request, reported as 54% cheaper than a top model at high effort on 85 coding tasks with the same score (marked interim).
These are the project's own measurements. The README also cites Adobe Research and a JetBrains blog test as outside checks, and your savings will depend on how chatty your sessions are.
I like the idea because tokens you never send are the cheapest ones, and short answers are faster to read.
Install is one command: npx @caveman-ai/cli@latest. Apache 2.0.
Would you trade a bit of friendliness for shorter, faster agent replies?
Sources
New notes go out on LinkedIn first. Building something with AI? We can help.