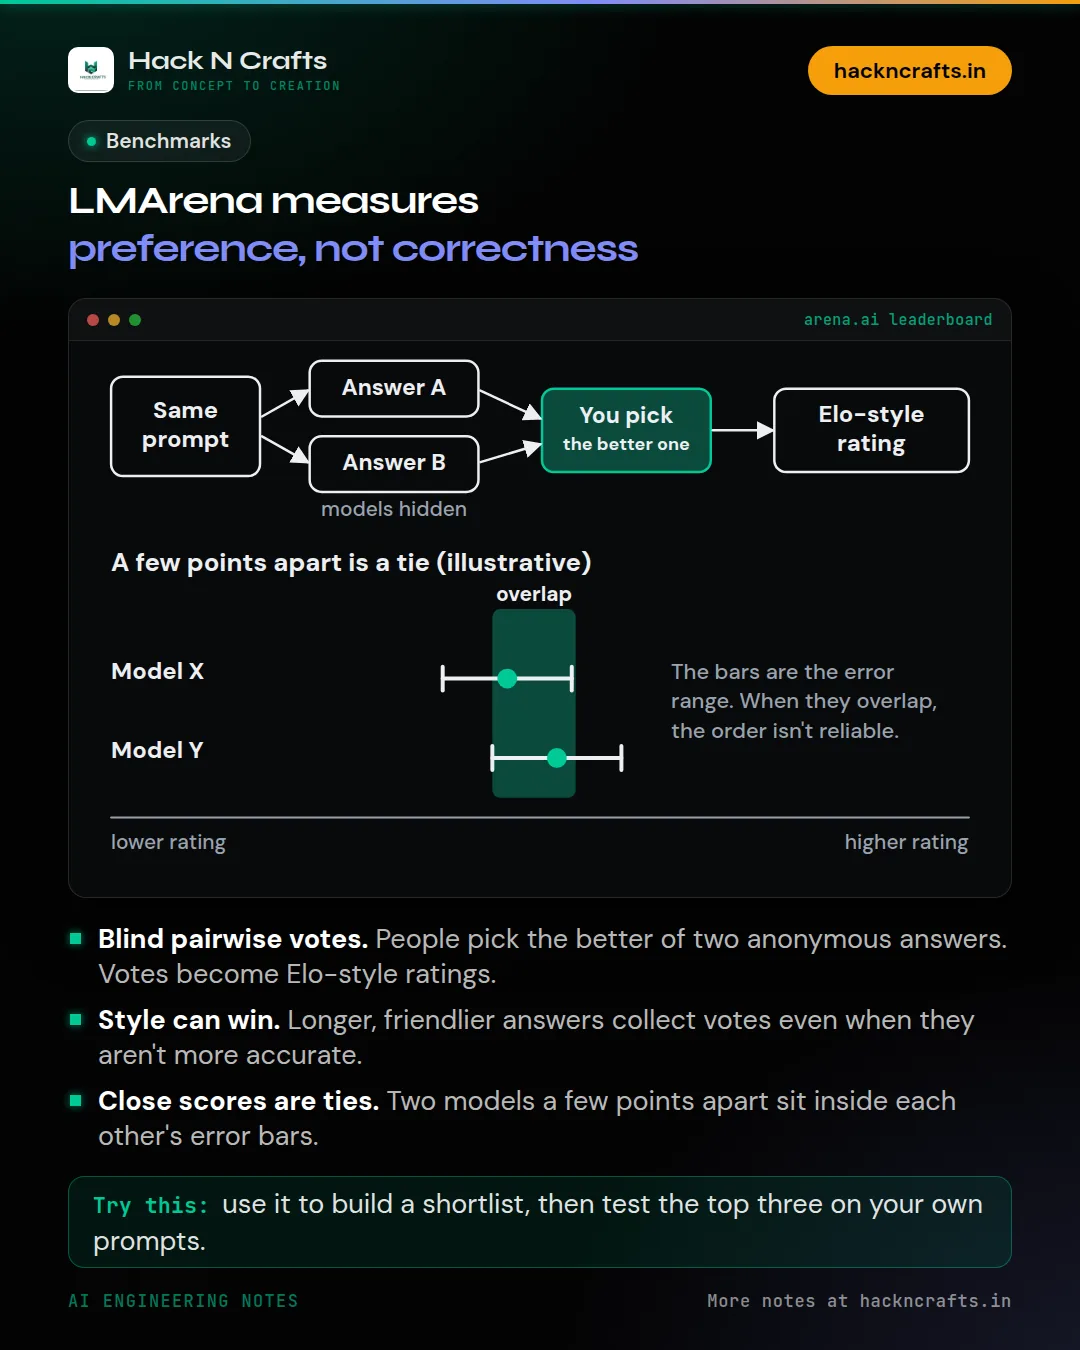
LMArena measures preference, not correctness
Topping LMArena doesn't mean 'most correct.' It means 'most preferred by the people who voted.'
You get two anonymous answers to the same prompt, you pick the better one, and only then do you see which models they were. Many votes get turned into ratings, similar to chess Elo. That matters because it measures something fixed tests can't: which answers real people like, on real prompts, with no known test set to train on.
Reading it carefully matters, though. Style can win. Longer, friendlier, better formatted answers tend to collect votes even when they aren't more accurate, and the Arena offers style-controlled views to correct for that. The voters aren't you. Their prompts skew toward casual chat, coding and creative writing. Scores carry uncertainty, so two models a few points apart are effectively tied. And a model can lead overall while trailing in the category that matches your work.
I'd use it to make a shortlist, then test the top three on my own prompts.
Do you check the Arena before picking a model, or do you go by your own tests?
Sources
New notes go out on LinkedIn first. Building something with AI? We can help.