Predicting a multi-agent failure from its first steps
Can you tell, halfway through, that a multi-agent run is going to fail? A new paper says yes, with over 90% accuracy on two benchmarks.
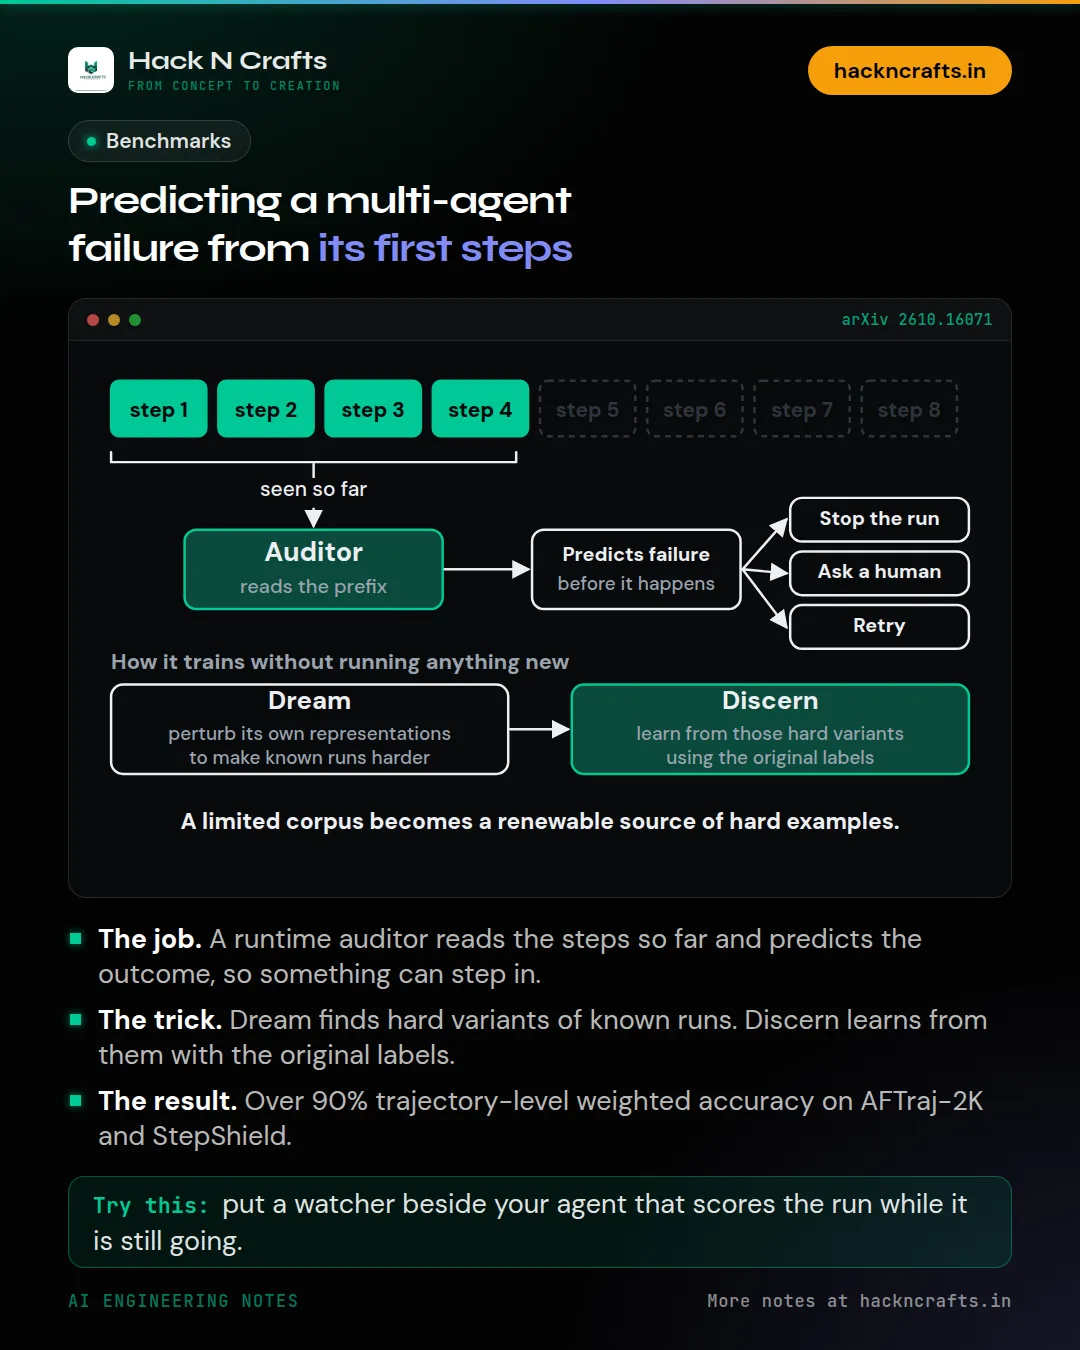
The paper, Dream2Discern (Rutgers, UT Austin and Amazon, on arXiv in mid-October), builds a runtime auditor. It reads the steps an agent system has taken so far and predicts the final outcome, so something can step in early: stop the run, ask a human, or retry.
The hard part is training data. You need runs with verified outcomes, and each one costs real execution and checking. Their trick is to make more training examples without running anything new. In a 'Dream' phase, the auditor perturbs its own internal representations to find versions of known runs that it finds hardest to classify. In 'Discern', it learns from those hard variants using the original labels.
The reported result: over 90% trajectory-level weighted accuracy on both AFTraj-2K and StepShield, while balancing accuracy against how early it can call it.
Why care if you don't train models: the pattern is useful. Agent systems need a watcher that's separate from the agent, and 'predict failure from the prefix' is a clean way to frame the job.
Do you have anything watching your agents while they run, or do you only check afterward?
Sources
New notes go out on LinkedIn first. Building something with AI? We can help.