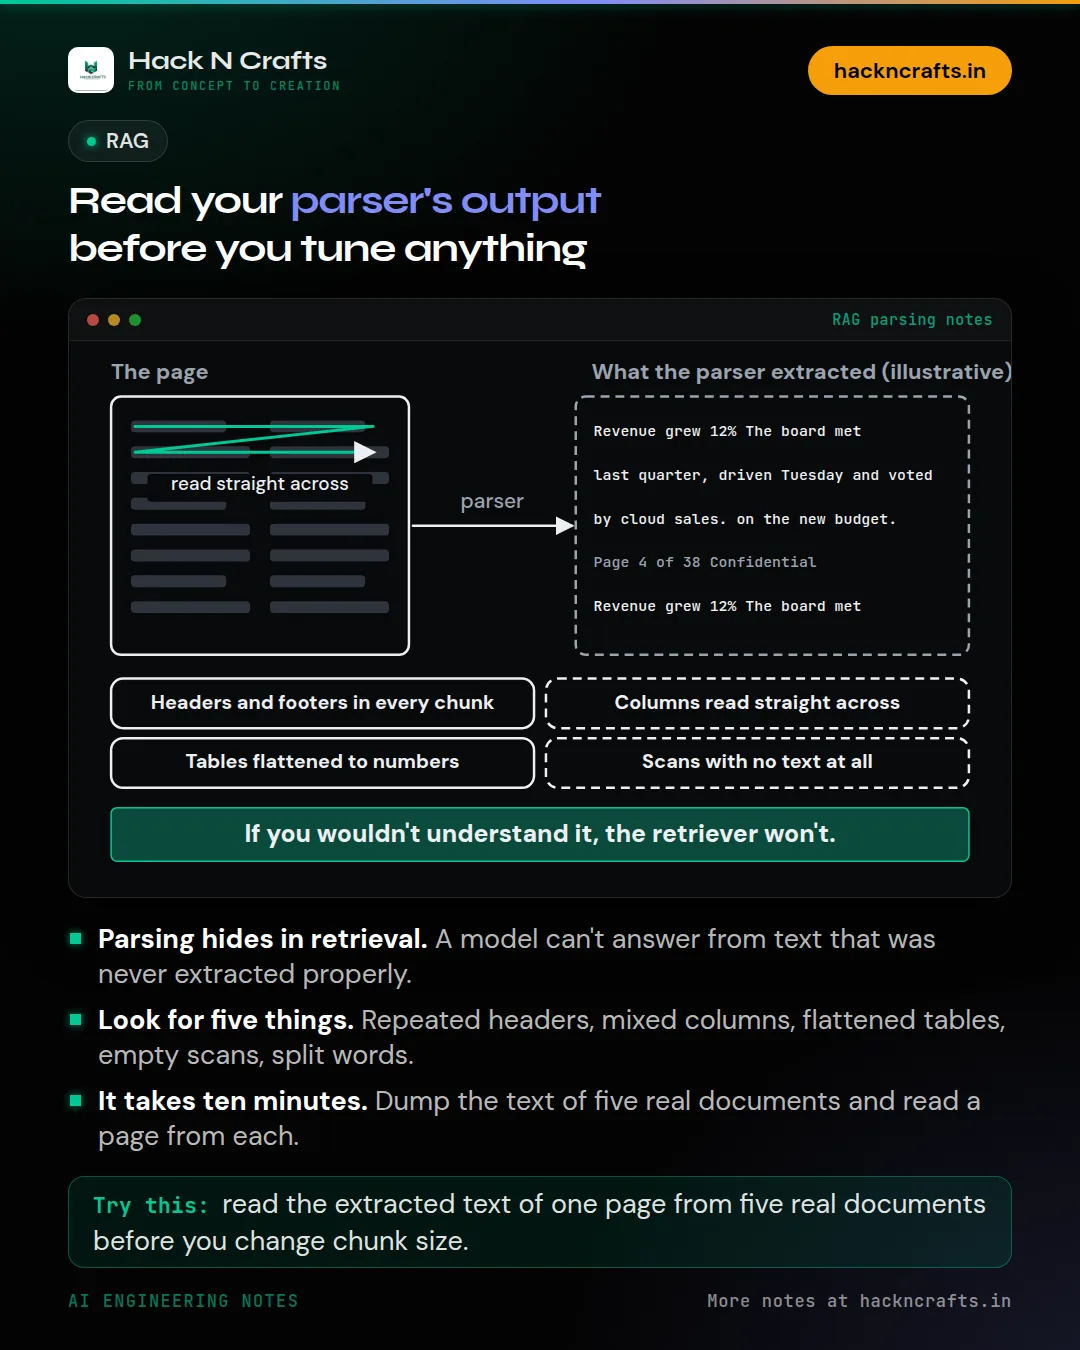
Read your parser's output before you tune anything
Before you touch chunk size or embeddings, open the text your PDF parser produced and read it.
Many RAG quality problems get blamed on retrieval when they are parsing problems. The model can't answer from text that was never extracted properly.
Things to look for:
- 1Page headers and footers repeated in every chunk. They add the same noise to every embedding.
- 2Two-column pages read straight across, so sentences from different columns get mixed together.
- 3Tables flattened into a stream of numbers, with the column names far away.
- 4Scanned pages that produced no text at all, and nobody noticed.
- 5Words split with a hyphen at the end of a line.
It takes ten minutes. Pick five real documents, dump the extracted text to files, and read one page from each. If you wouldn't understand it as a person, the retriever won't either.
Fix the parsing first. After that, the usual chunking and embedding experiments start to mean something.
Which document type has given your parser the most trouble?
#RAG#GenerativeAI#LLM#AI
New notes go out on LinkedIn first. Building something with AI? We can help.