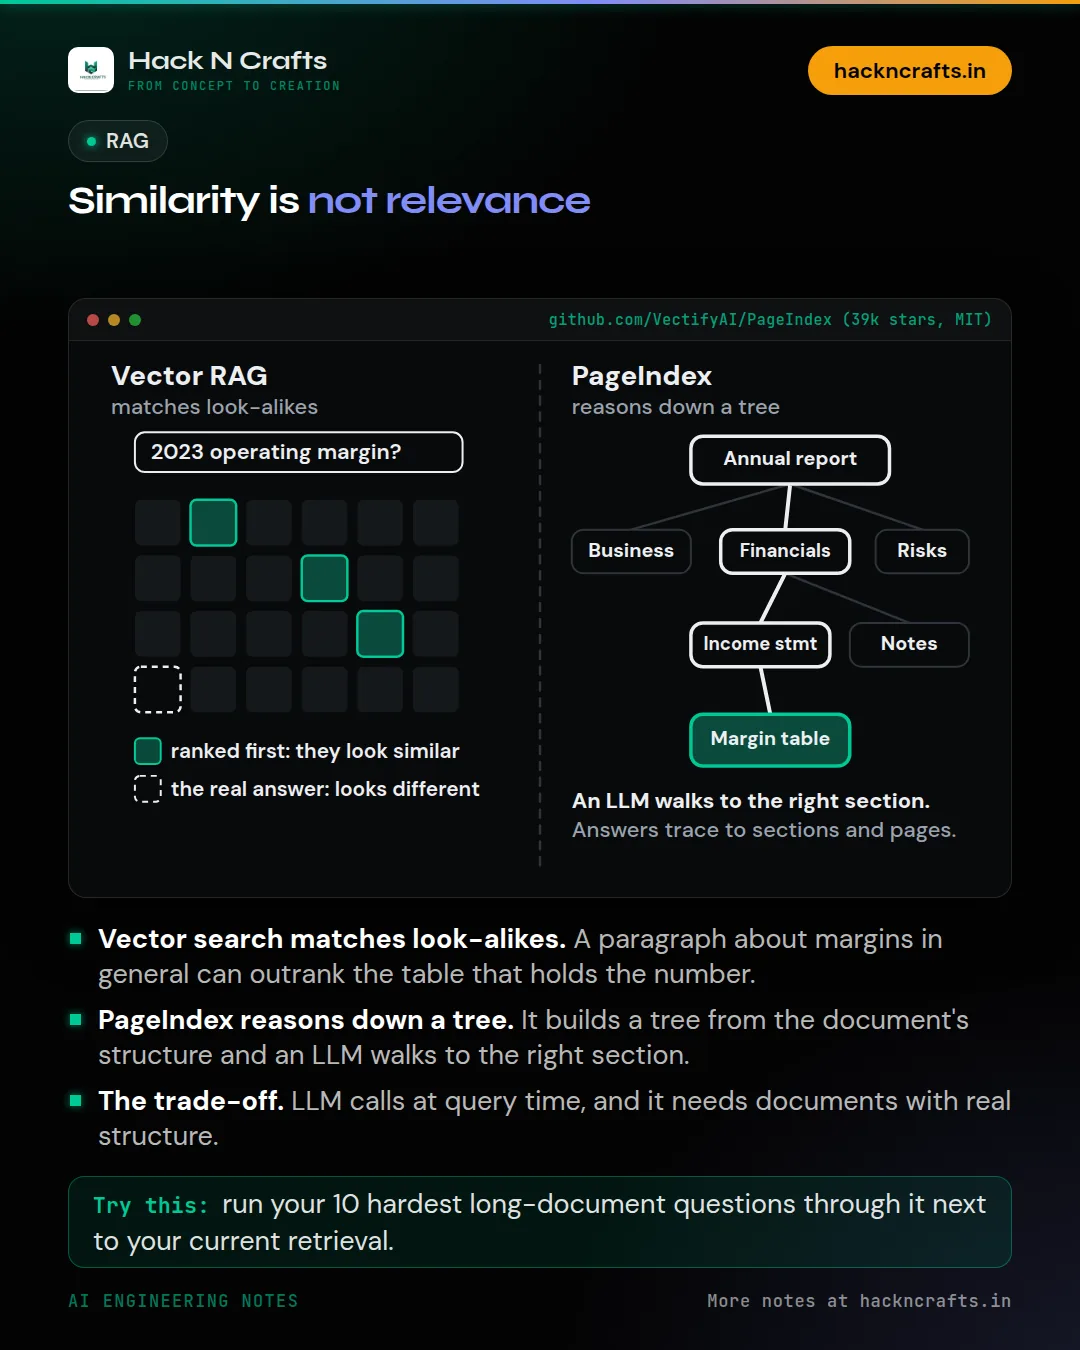
Similarity is not relevance
Vector search finds text that looks like your question. In long reports, the answer often hides in text that doesn't.
Picture a 200-page annual report. You ask for the 2023 operating margin. The most similar chunk might be a paragraph that talks about margins in general, while the actual number sits in a table under a heading that looks nothing like your question.
PageIndex, an open-source project from Vectify AI (39k stars, MIT), takes a different route that it calls vectorless RAG. Per the README, it builds a tree index from the document's own structure, with a short summary at each section. Then an LLM reasons its way down the tree, the way a person flips to the right chapter. Every answer traces back to specific sections and pages. There's no vector database and no chunking. The README says it suits long, structured documents like financial reports, legal filings and manuals.
The trade-off is that a model does the searching, so you pay for LLM calls at query time, and it relies on documents with real structure. For short notes or big messy piles of text, plain vector or hybrid search is probably still the better fit.
If you have long documents, try it on your 10 hardest questions and keep your current retrieval alongside. If it finds answers vector search misses, you've learned something real.
Have you tried a non-vector approach to retrieval? What was the catch?
Sources
New notes go out on LinkedIn first. Building something with AI? We can help.