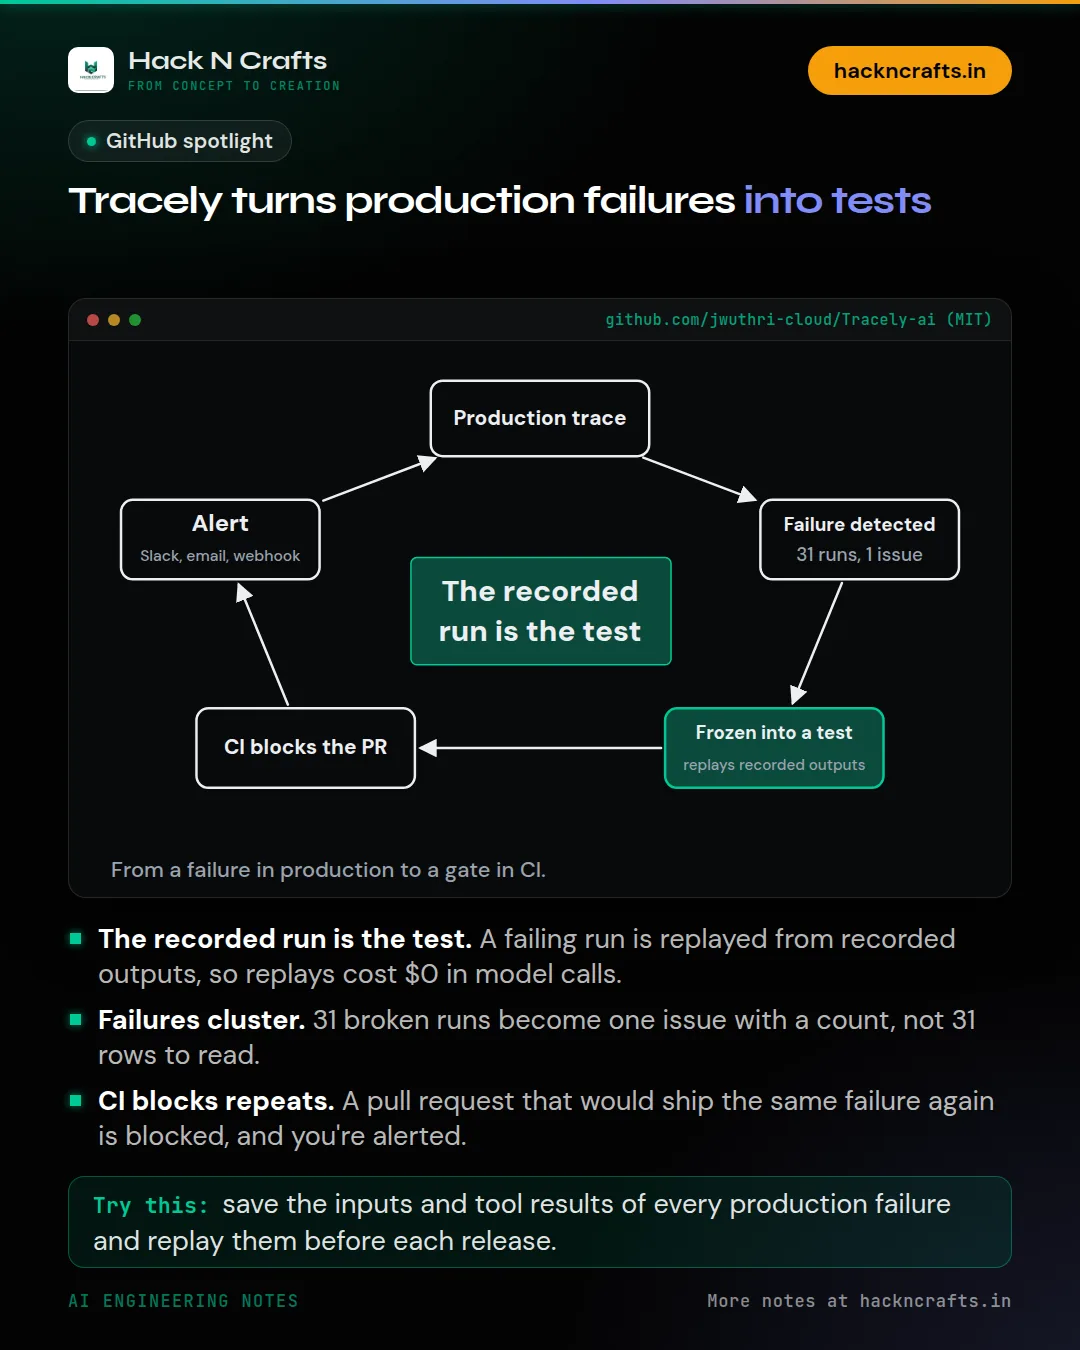
Tracely turns production failures into tests
Most agent eval tools start with a dataset you write by hand: invent questions, write ideal answers, keep them current. That dataset is a guess about what might break.
Tracely, a young open-source project (MIT, about 1k stars, created 11 October), starts from what broke. Per its README, traces come in over standard OpenTelemetry, grouped by conversation and step. Online evaluators grade each run, and failures get clustered, so 31 broken runs become one issue with a count. A failing run is frozen into a regression test that replays from recorded tool and model outputs, so a replay costs $0 in model calls. A pull request that would ship the same failure again gets blocked, and you're alerted through Slack, email or a webhook.
The README's core line is 'The recorded run is the test.'
It's early, and self-hosting needs Postgres, ClickHouse, Redis and MinIO, so it isn't a weekend toy. But the habit is worth copying without the tool. Every time an agent fails in production, save the exact inputs and tool results, and turn them into a test you run before each release.
Do your agent failures turn into tests, or into a Slack thread that gets forgotten?
Sources
New notes go out on LinkedIn first. Building something with AI? We can help.