The MTEB average hid the jump
Before you pick an embedding model, check which part of MTEB moved. The average can hide it.
MTEB, the Massive Text Embedding Benchmark, scores embedding models across many datasets and several task types, including retrieval, classification, clustering and similarity. There are multilingual and code versions too. Most people look at the single average.
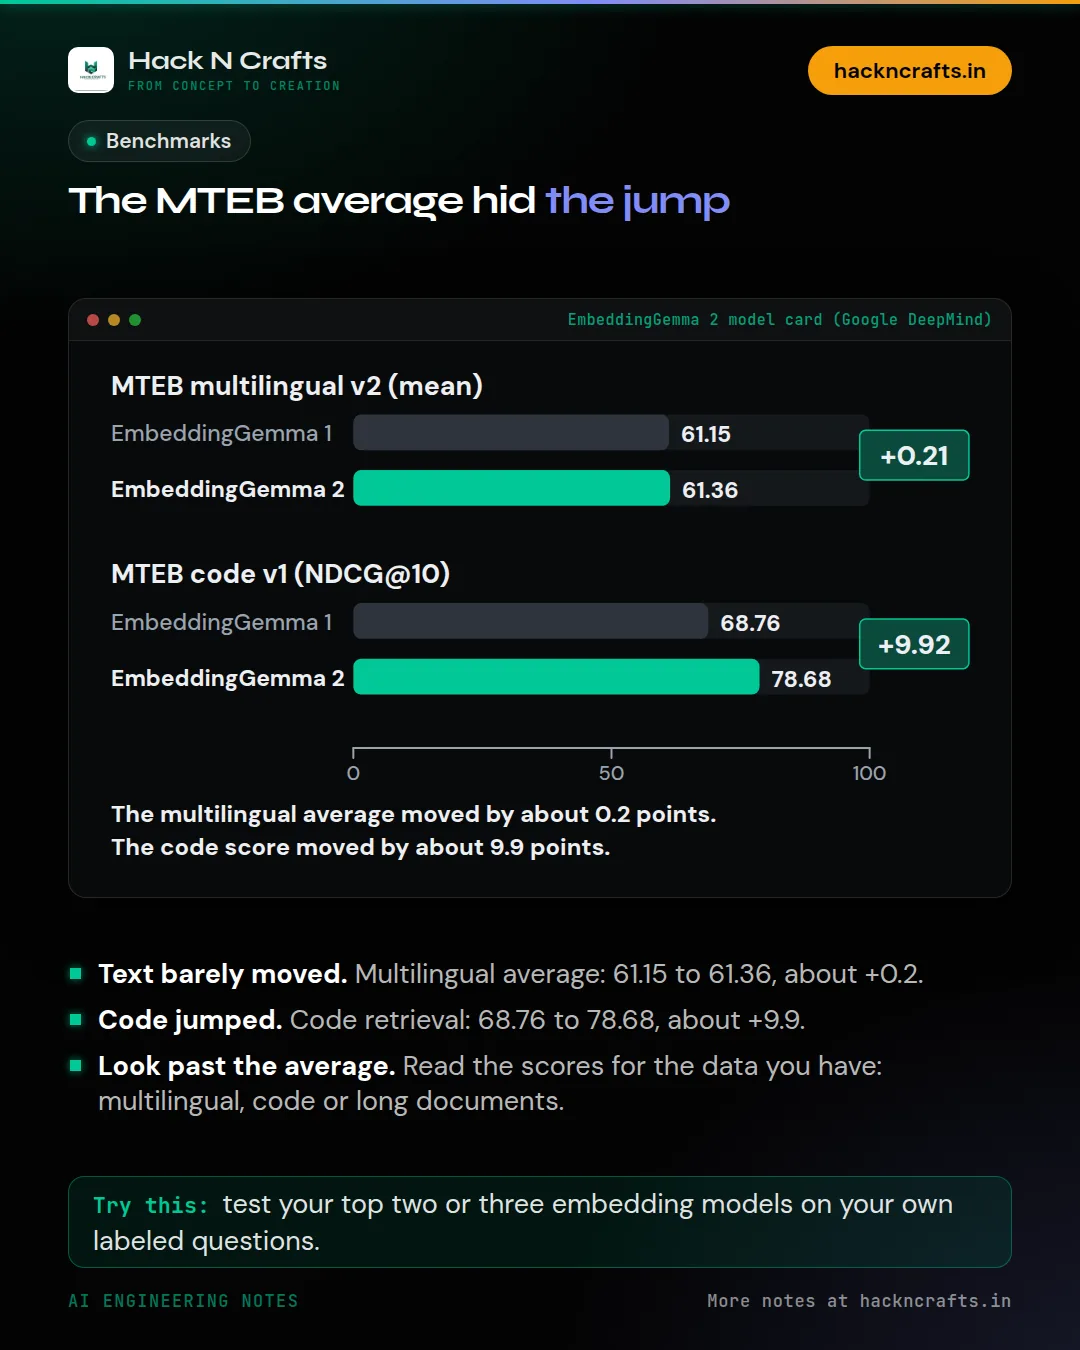
Take Google's new EmbeddingGemma 2. Its model card reports 61.36 on the multilingual MTEB average, against 61.15 for the first version. That looks flat. On the code version, though, the score goes from 68.76 to 78.68. The big change happened in one area, and the average hid it.
For a RAG project, look at the retrieval scores before the overall number. Pick the version closest to your data: multilingual, code or long documents. Check vector size and speed, since a 768-dimension model costs more to store than a 384-dimension one. Treat gaps under a point or two as ties. And remember the benchmarks use public data that a model may have seen.
The best embedding model for you is the one with the best recall on your own labeled questions.
Which embedding model are you using right now, and did you test it against alternatives?
Sources
New notes go out on LinkedIn first. Building something with AI? We can help.