EmbeddingGemma 2: one vector space for four modalities
Google DeepMind released EmbeddingGemma 2, an open embedding model that puts text, images, video and audio into one shared vector space.
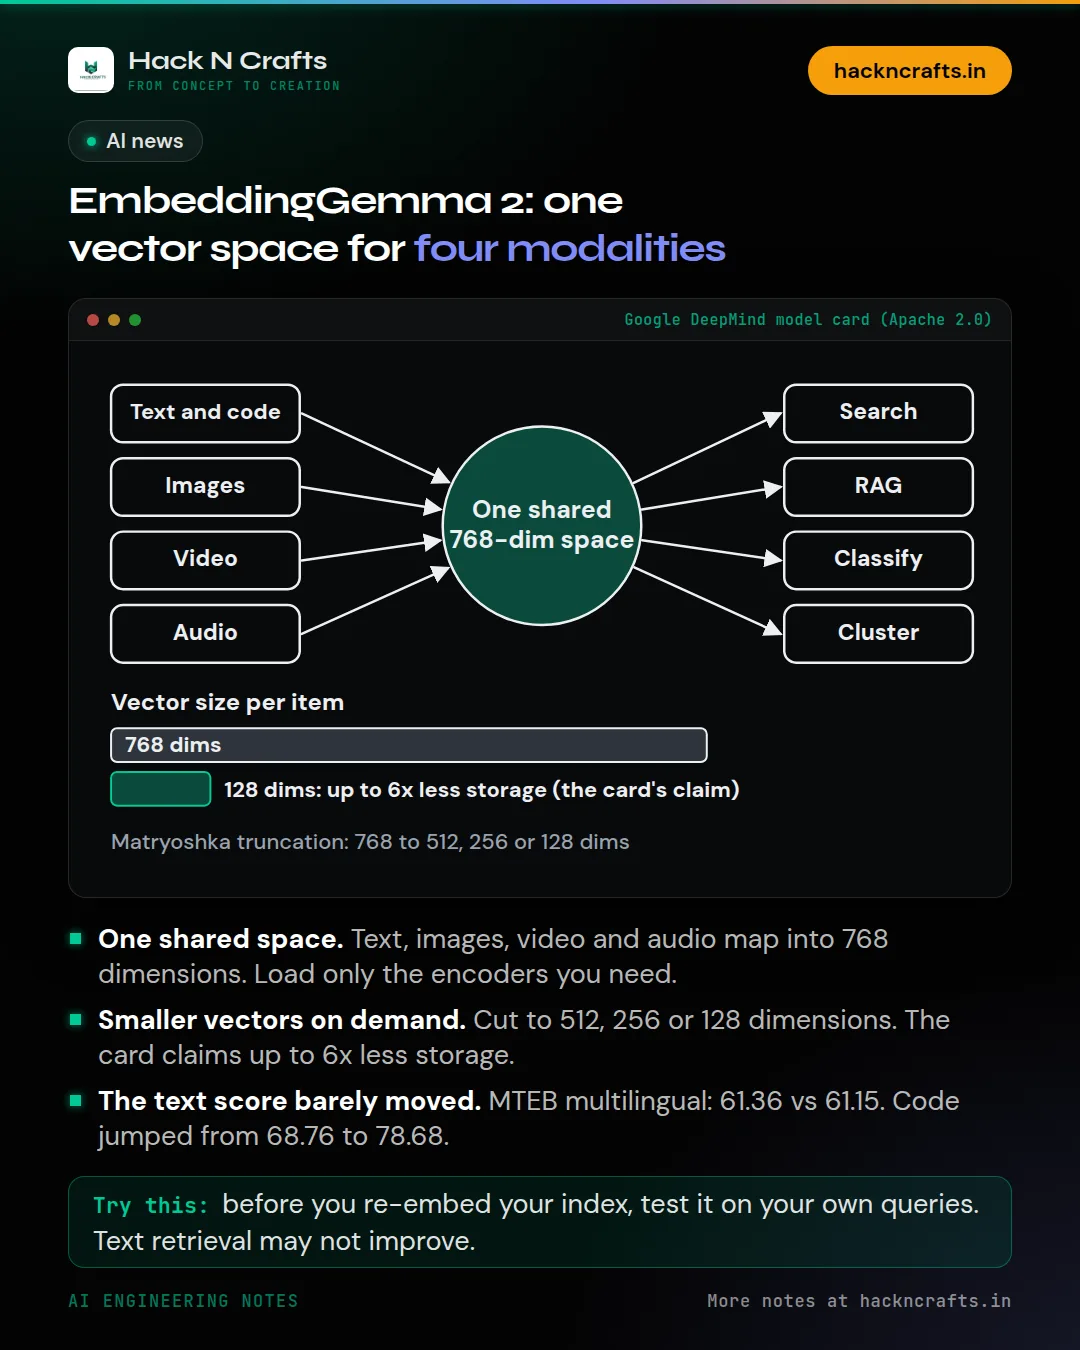
From the model card: 740M parameters in total, made of a 270M text model plus optional 170M vision and 300M audio encoders, so you only load the modalities you need. Vectors are 768 dimensions and can be cut to 512, 256 or 128. At 128 that's up to 6x less vector storage, with what the card calls minimal quality loss. It has an 8K context window, covers 100+ languages, runs on laptops and phones, and uses Apache 2.0.
The benchmark table is the interesting part. On the multilingual text benchmark (MTEB), it scores 61.36 versus 61.15 for the first version. Basically flat. On the code version it jumps from 68.76 to 78.68. The gains are in code and in the new modalities.
For anyone building RAG, that means code search and mixed media get a stronger open option. It also means plain text retrieval probably won't improve much if you swap models, so test before you re-embed your whole index.
Would you use one shared embedding space for images and text, or keep separate indexes?
Sources
New notes go out on LinkedIn first. Building something with AI? We can help.