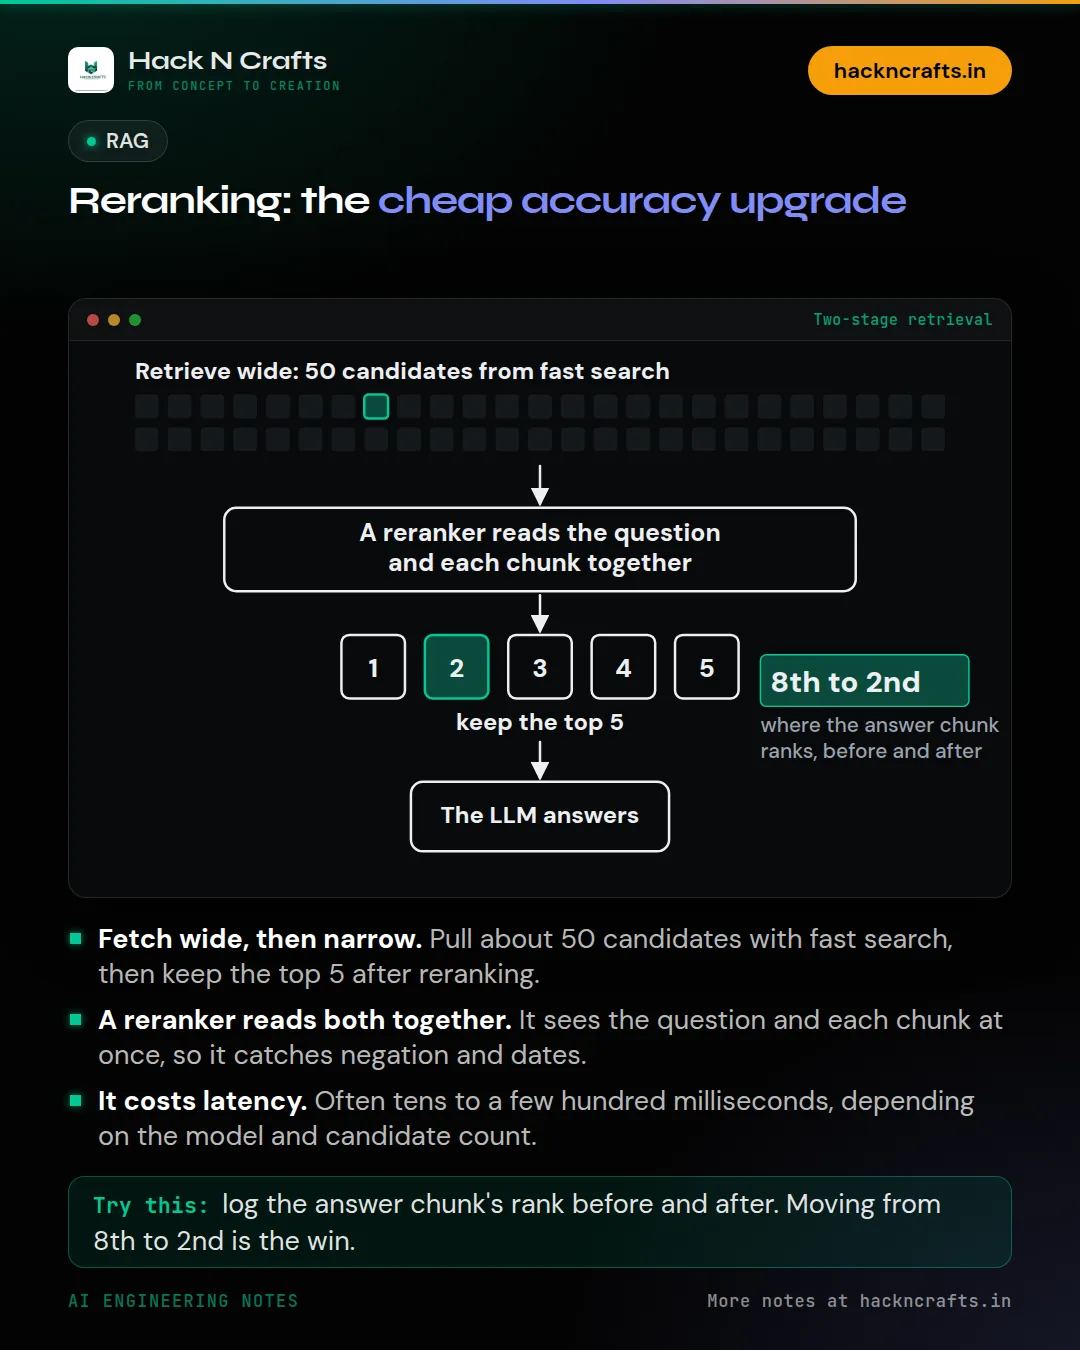
Reranking: the cheap accuracy upgrade
One of the cheapest ways to improve a RAG system is to add a reranker. You don't touch your index or your LLM.
The setup has two stages. First, fetch more candidates than you need, say 50, with fast vector or hybrid search. Then a reranker reads the question together with each candidate and scores how well it answers. You keep the top 5.
Why it helps: embeddings compare the question and the chunk as two separate vectors. A cross-encoder reranker reads them together, so it can catch negation, dates and 'this one, not that one'. It's slower per document, which is why it only runs on the shortlist. Expect some added latency, often tens to a few hundred milliseconds depending on the model and how many candidates you rerank.
To know it's working, log the rank of the chunk that held the answer, before and after. If it moves from 8th to 2nd on a lot of queries, the LLM now sees the right text.
One common mistake is reranking only 5 candidates. If the right chunk isn't in the shortlist, nothing can rescue it. Widen the first stage first.
Do you rerank today? Which model, and did it earn its latency?
New notes go out on LinkedIn first. Building something with AI? We can help.