Retrievers can mix up which color goes with what
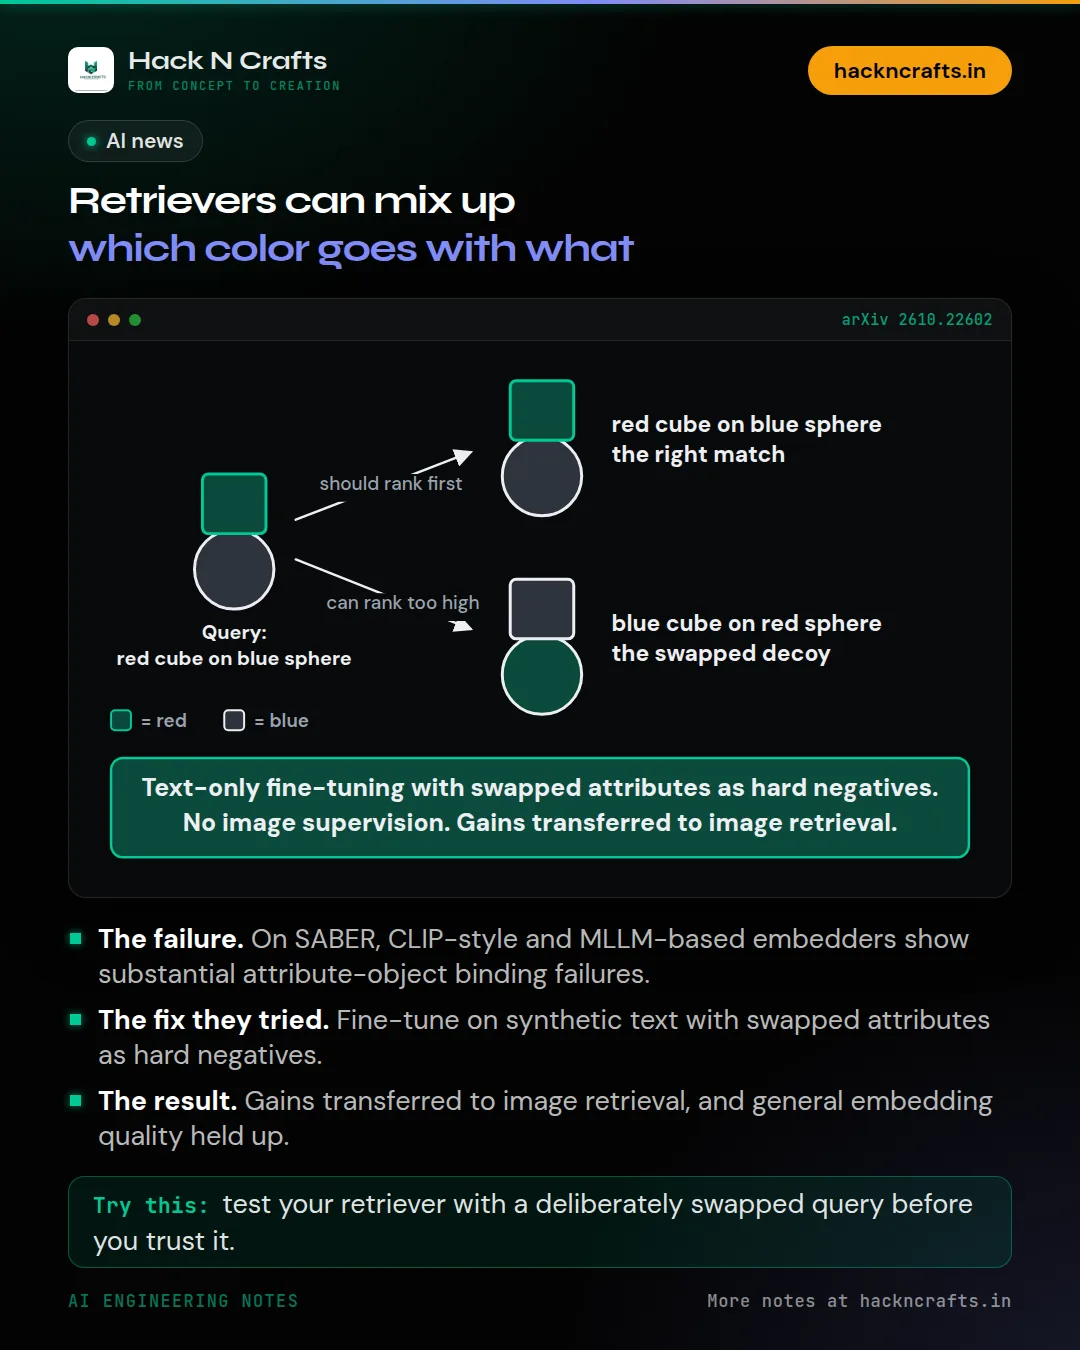
'A red cube on a blue sphere' and 'a blue cube on a red sphere' can look almost identical to a multimodal retriever.
That's the problem behind a new paper, Stuck on Shuffle. Retrieval systems embed images and text into a shared space and match by similarity. For that to work, the embedding has to capture which things are in a scene and how they're combined, so the red goes with the cube. It's called attribute-object binding.
The authors built SABER, a controlled benchmark for it. It covers all four image and text pairings, with scenes of up to ten objects. Their finding: substantial binding failures in both CLIP-style dual encoders and recent embedders built on multimodal LLMs.
Then something useful. They fine-tuned an embedder only on synthetic text about attributes and objects, with hard negatives where the attributes are swapped. No image supervision. The gains transferred to cross-modal and image-to-image retrieval, general embedding quality held up, and they report state-of-the-art on SABER plus gains on negation and instance-retrieval benchmarks.
If you build multimodal search, the lesson is practical: test your retriever with swapped attributes before you trust it.
Have you ever tested your retriever with a deliberately swapped query?
Sources
New notes go out on LinkedIn first. Building something with AI? We can help.